Search results for arXiv
arXiv community
One keyword maps to one global community path.
People
Not Found
Tweets including arXiv

arXiv has many faulty proofs, according to Astra and Opus 5.5. I'm running actual audits to make sure the claimed solutions don't affect the status of the open problems on my list (
Show more


Looking for an ArXiv endorser in Computational Linguistics ( for a new paper submission. I’m a postdoc at HEC, and this is my first ArXiv submission. I would greatly appreciate any help or connections. Please DM me if you can assist. Thank you!
Show more

Source is arXiv 2605.19537 the silent hyperparameter btw:


chinese history but arxiv:
Mao almost collapsed china with his ideological SFT
Deng Xiaoping corrected the trajectory with online RL

i am glad arxiv is cracking down on slop
oh wait

Research repository ArXiv will ban authors for a year if they let AI do all the work

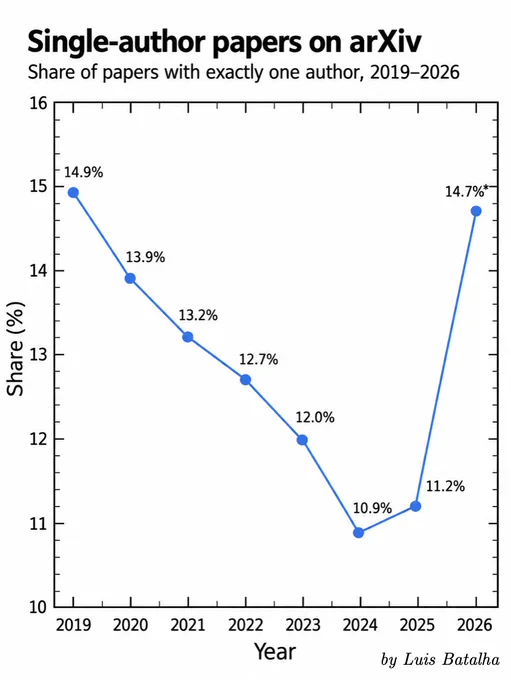
The rise of the "solo" researcher on arXiv

A carefully controlled look at looped transformers (arXiv 2609.19107):
1. Weight sharing is not compute-optimal on fresh data. It costs a constant ~1.06–1.16x compute at every scale.
2. The looped model's gains over vanilla come from elsewhere: the norm + input re-injection boundary operator, and growing depth mid-training. Both improve the scaling exponent. Neither needs weight sharing.
3. Looping is still a parameter-free way to get growth. Tied growth keeps the exponent gain at vanilla param count.
4. Weight sharing wins on multi-epoch, data-constrained training.
Show more
