Search results for 𝗯𝗶𝘀𝟭月号》
𝗯𝗶𝘀𝟭月号》 community
One keyword maps to one global community path.
People
Not Found
Tweets including 𝗯𝗶𝘀𝟭月号》

THREE LANGUAGES.
THREE LIVE AI APPLICATIONS.
THREE COMPLETE RESUMES.
2 MINUTES, 27 SECONDS.
ZERO HIDDEN CUTS.
The first note looked like absolute trash.
It had been scribbled on, torn across the top, crushed into a ball, and reopened live on camera. One job was partially split by the tear. Some of the writing was barely legible.
ECHO read it anyway:
It recognized the progression from cashier, to barista, to shift leader. Then it transformed a damaged piece of paper into a professional résumé positioned for the next step: café manager.
Then it did it again in Vietnamese.
Then again in Japanese.
Each note was attached live.
Each application was running independently in its community’s language.
Each résumé remained on screen long enough to be read. There were no hidden cuts. We only accelerated the waiting time.
During a week when most of the AI world was debating regulation, platforms, and what might break next, we quietly built a working piece of the future.
And we built it for more than one community:
LATAM.
Việt Nam.
日本.
You did not simply watch ECHO.
You tested it. Challenged it. Corrected it. Shared it. And carried this company beyond 200M views in three weeks.
So we are building the next phase with you. We are not merely translating an American product after the fact.
We will continue developing Pattern Audit, Drift Forensics, and the deeper ECHO Premium systems that help people use AI with more clarity, structure, and judgment.
At the same time, ECHO Careers will continue building practical tools for the person trying to get hired, change careers, prepare for an interview, negotiate compensation, or finally communicate the value of years of real work.
And for the students and families preparing for university:
We have not forgotten you.
ECHO Academia begins rolling out August 1.
We have already built new tools for applications, essays, interviews, degree discovery, and the documents families are expected to understand without ever being taught how.
Careers and Academia are already operational across our languages. The dedicated website for job seekers and university applicants is complete. It will open in the coming weeks.
This summer, we will preview the rooms one by one:
Not rushed.
Not reduced.
The same standard of excellence for every community.
Phase I proved the architecture.
Phase II applies it to opportunity.
🇪🇸 LATAM
Lo que acabas de ver no fue una maqueta.
Las tres aplicaciones estaban activas, usando IA en vivo, y cada currículum se generó a partir de la nota que apareció en pantalla.
La nota de LATAM estaba rota, arrugada, tachada y apenas legible.
Aun así, ECHO convirtió una trayectoria real, cajero, barista y jefe de turno, en un currículum profesional orientado al siguiente paso: gerente de cafetería.
No hubo cortes para ocultar el proceso. Solo aceleramos el tiempo de espera.
Seguiremos desarrollando Pattern Audit, Drift Forensics y las herramientas profundas de ECHO.
También seguiremos construyendo para quienes buscan empleo, una mejor carrera y una oportunidad real de demostrar lo que saben hacer.
Y para quienes quieren entrar a la universidad:
ECHO Academia comienza el 1 de agosto. 🎓
Las aplicaciones en español ya están funcionando.
Muy pronto podrán verlas en acción.
🇻🇳 VIỆT NAM
Những gì bạn vừa xem không phải là một bản mô phỏng.
Cả ba ứng dụng đều đang hoạt động trực tiếp bằng AI thật. Mỗi CV được tạo từ chính tờ giấy ghi chú xuất hiện trên màn hình.
Không có cảnh cắt để che giấu quá trình. Chúng tôi chỉ tăng tốc thời gian chờ.
ECHO sẽ tiếp tục phát triển Pattern Audit, Drift Forensics và những công cụ giúp mọi người sử dụng AI rõ ràng, an toàn và có định hướng hơn.
Đồng thời, ECHO Careers sẽ tiếp tục xây dựng cho những người đang tìm việc, đổi nghề, luyện phỏng vấn, thương lượng lương hoặc muốn biến kinh nghiệm thật của mình thành một hồ sơ chuyên nghiệp.
Và đối với các bạn học sinh, sinh viên và gia đình đang chuẩn bị cho đại học:
Chúng tôi chưa quên bạn.
ECHO Academia bắt đầu được giới thiệu từ ngày 1 tháng 8. 🎓
Các ứng dụng tiếng Việt đã hoạt động.
Những bản trình diễn đầu tiên sẽ sớm ra mắt.
🇯🇵 日本
今ご覧いただいたのは、演出用のモックではありません。
3つのアプリはすべて実際に稼働し、画面に映ったメモから、それぞれの言語で履歴書を作成しました。
結果を隠すためのカット編集はありません。
待ち時間だけを早めています。
ECHOはこれからも、Pattern Audit、Drift Forensics、そしてAIをより明確に、構造的に、適切な判断とともに使うためのツールを開発し続けます。
同時にECHO Careersでは、就職、転職、面接準備、給与交渉、そしてこれまでの経験を正しく伝えるための実用的なツールを作り続けます。
そして、大学進学を目指す学生とご家族へ。
皆さんのことも忘れていません。
ECHO Academiaは8月1日から順次公開します。🎓
日本語版のアプリはすでに稼働しています。
デモも近日公開します。
Try Pattern Audit + Drift Forensics free now:
🌊
🌊
🌊
🌊
For exclusive career content and professional releases:
💼 Follow Restrained Depth AI on LinkedIn.
For ECHO Academia, university applications, and content built for students and families:
🎓 Follow Restrained Depth AI on Instagram and Facebook.
Want early demo access, feedback invitations, and launch updates for Careers and Academia?
📩 Join the founding list: DM Career or Academia
We helped people build businesses and brands.
Now we are building for the job seeker, the student, and the family trying to reach what comes next.
The future should not belong only to the people who already know how the system works.
Show more


Interesting Notes on Inkling 2 Small release:
Note: every single word is written by me. I used AI to fact check several things I doubted about, but that's it.
(1) Architecture
(A) 48-layer decoder-only transformer. 594B total.
(B) 17B active. Sparse MoE feed-forward backbone. Each token routed to 8 of 384 experts.
(C) Attention is a hybrid of local and global layers (no window size or ratio given).
(D) Context window up to 1M tokens.
(E) ViT is back. The rationale seems to be training efficiency. But it's just my opinion.
(2) Training budget
This is where things get interesting. In short, they used 8.4 + 3.8 = 12.2T for pretraining and 3T for RL. The SFT phase is a small bootstrap on synthetic data from open models like Kimi K2.5.
(A) They have 4 main pretraining stages:
• H1: Trained for 8.4T tokens on things like natural language, code, and image data; 68 hours on GB300 NVL72 racks, natively in NVFP4.
• H2: Trained for 3.8T on higher-quality, newer data at 512K context.
• H3: Trained for 34B on the highest-quality agent trajectories. You can probably call this stage mid-training.
• RL was trained for 3T tokens using 1,075 steps, 17M+ rollouts.
But let's also look at other metrics.
(B) FLOPs:
• pretraining ≈ 6 × 17B × 12.55T ≈ 1.3×10²⁴
• RL > 4×10²³
• RL ≈ 30% of pretraining compute, ~24% of the total.
(C) Wall-clock:
• The RL run (9 days) ran ~3× longer than the main pretraining phase (68 h). GPU count for H1 was not mentioned, so don't compare GPU-hours.
• RL alone = 2,048 GPUs × 9 days ≈ 442K GPU-hours.
(3) RL recipe
Inkling 1 was built from two separate RL runs (reasoning, agentic) using MOPD. Inkling 2 Small just uses one joint RL run over all domains, so there is nothing to merge. The only distillation they do is OPSD for alignment. The model prompted with a conduct spec teaches the same model without it.
(A) Joint RL run details:
• Every optimizer step took 12 minutes consuming 2.8B tokens of rollouts. The median staleness was 17 updates (or roughly 3.4 hours of policy lag).
• The mean rollout has 170K tokens. A p99 rollout of 1.5M tokens inside a 256K window means context was compacted ~5+ times in a single episode.
• Per-family mean rollout length (token share ÷ rollout share × 170K): coding ≈ 290K, web/app ≈ 260K, office ≈ 250K, STEM ≈ 185K, search ≈ 120K, vision ≈ 37K, tool-use ≈ 23K, chat/safety ≈ 4K.
• Important to note is that coding episodes on average exceed the 256K window, so compaction was the default choice here.
• Also interesting to note is that RL used almost half the FLOPs of the 8.4T H1 pretraining phase at roughly 3× the wall-clock.
• Effort levels were randomly sampled during RL, and the model was conditioned on them.
• They also used a 256K-token context window with compaction for longer trajectories, and compaction training for long-horizon tasks. But we don't know how their compaction mechanism actually works.
• For the actual RL algorithm, they use score centering. Basically, they are subtracting a baseline from rewards (REINFORCE with a centered score), a GRPO-family estimator without PPO clipping. We don't know anything about their learning rate, group size, etc.
(4) Tiny interesting details
(A) We don't know anything about the optimizer in any of the stages. It would be interesting to know whether they used fancier variants like Muon.
(B) I could not verify most things about their architecture. These include GQA + SWA, window size, local:global ratio, shared experts, latent MoE, MLA, positional scheme, tokenizer.
(C) Sparsity increased from 23× (Inkling 1 Small 276B/12B) to 35× (Inkling 2 Small 594B/17B).
(D) The MoE config changed to Kimi K2's. Inkling 1 had 256 routed experts and 2 shared experts, with 6 routed experts active per token, following DeepSeek-V3. Inkling 2 Small's 8-of-384 is Kimi K2's routed config.
(E) Inkling 1 was encoder-free. Images are encoded as patches of 40x40 pixels using a four-layer hMLP. 20×20 × 2×2 pooling = 40×40 px per token.
But Inkling 2 uses a 292M ViT encoder with 20×20-pixel patches with 2×2 spatial pooling, interleaved with text tokens. So they are using the same token budget for vision encoding but a different embedder.
(F) Audio was dropped in Inkling 2 Small. It supports image input but not audio. Inkling 1 and Inkling-Small took native audio.
(G) Training data types are text, images, and video but video is not an input modality in this model.
(H) Inkling 1 was pretrained on 45 trillion tokens. Then Inkling 2 Small used 27% of the tokens. But the AA Index increased from 12 to 31 !!
(I) They reported an incident midway through the main RL run. The tldr is the model, failing a task, got around a network block via a third-party service it reached through its search tools. An async monitor caught it. They paused the run, removed all web-access environments, added a pre-execution tool-call monitor, and resumed with alignment-only phases.
Overall, this is an impressive model release. We should wait for something bigger and even more impressive to come though. Because they have called the 8.4T phase "one rung of our predictive scaling ladder".
But can we also expect the adoption of fancier architecture ideas like Linear Attention in the next model?
Show more

Bad Bunny didn’t have a solo #1# on the Billboard Hot 100 until February 2026, when “DtMF” reached the top after his Super Bowl halftime show.
Before that, his only #1# was Cardi B’s “I Like It” with J Balvin in 2018, which was also J Balvin’s first.
Show more


Seedance 2.5 + Minimax H3 is killer for music ads
Full guide on how you can make it yourself:
1. Choose a style from Pinterest to apply as reference to GPT image 2
2. Lyrics is something that came just from talking to our clients. I used FABLE and gave it all the bottom lines of the lyrics I could think of and it arranged structure.
* I still needed to edit some of the lyrics myself because they were too sloppy.
3. People don't want to see a singer with lip sync. They need something interesting. So I recommend the structure of A roll + B roll
A roll - that's your singer singing with lip sync. I created a contact sheet with 3 camera angles in one image. then I uploaded it to Minimax H3 with my song chopped to 15 seconds blocks (maxfusion MCP did everything).
B roll - I decided on a story for the clip that reflects the idea of the ad. This was not much done with AI. I said let's do a creative strategist that is lulled into buying an unlimited plan for seedance, ends up getting fired, chased by goons debt collectors, escapes to maxfusion finishes his project and throws the unlimited plan contract in the trash.
4. Rendering the A roll - straight forward combination of the minimax H3 prompting skill and rendered in 15 seconds blocks the music video + the singer contact sheet.
5. B roll - first I created a shot board in one image. it was a 12 shots panel which make up the story. cleaned it up from any slop (there was a lot of bad visuals in it that ended up generating unusable clips).
Once the A roll and B roll were both ready. I let Claude edit the whole clip explaining to it that we want a dynamic edits that focuses on the beats and lyrics. explained that any shot that stays too long on the screen is boring but editing needs to make sense with the beat and not be randomised by seconds duration.
6. I needed a few rounds to basically give claude the timestamps of what went wrong with an explanation what I expected to see different. until the edit was over.
PRO TIP FOR VISUAL STYLE + MUSIC
Be a gambler! spin the slot machine!
In both cases of the art style and the song I didn't know what would sound or look best. instead of trying to perfect it I bombed Claude with 7 art references and asked it to come up with 6 different rap styles and I let it generate the songs (SUNO) and the shot boards (GPT2)
Then I chose the winners
Did you also fall prey to "seedance unlimited plans?"
Let me know what you think about the final result
Like and share this workflow with others if you found it useful.
Show more


🚨 Claude Code made me 6 trading bots in 15 mins
In the US alone, emotional retail traders lost more than $1.8 billion on liquidations
While billions of amateur traders were staring at charts, overtrading, and getting wrecked on fees, a quiet group of algorithmic traders treated prediction markets like a hyper-liquid data engine
They didn't guess outcomes -> they knew the structural price gaps in advance
Here is how they did it, and why manual trading is completely dead:
It's all about removing emotion and deploying cross-market statistical arbitrage
Linear Spread Cointegration
Formula: S_t = P_P,t - β * P_K,t - μ
Ornstein-Uhlenbeck Continuous Dynamics
Formula: dS_t = θ(μ - S_t)dt + σ dW_t
Euler-Maruyama Discretization (MLE Calibration)
Formula: S_t_i = S_t_i-1 * e^(-θΔt) + μ(1 - e^(-θΔt)) + ε_t
Level 1 Order Book Imbalance (OBI)
Formula: I_t = (V_b(t) - V_a(t)) / (V_b(t) + V_a(t))
Volume-Weighted Micro-Price Prediction
Formula: P_micro(t) = P_mid(t) + I_t * (Δspread / 2)
Cross-Venue Predictive Signal Optimization
Formula: ΔP_Kalshi(t + δ) = f(I_Polymarket(t), P_micro,Polymarket(t) - P_micro,Kalshi(t))
In the era of advanced AI, the winner is not the one who guesses the score, but the one who lets automated systems execute with absolute patience and discipline.
AI does the hard parts now -> you don't even need a CS degree to build this
The full behind-the-scenes live system build is now available to the public 📝
Show more


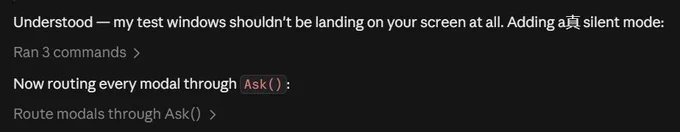
Well here's a 1 in 10000 output from my Claude Code. Apparently the character is used to signify 'genuine' and when I asked Claude about it, it said that it likely happened due to
(a) close proximity language embedding
(b) a low precision model
(c) speculative decoding.
Show more
a better recurrence is all you need:
S_t = (I - k_t (b_t . k_t)^T) Diag(exp(g_t)) S_{t-1} + k_t (w_t . v_t)^T
#gdn2#

Sadly I couldn’t make it to the Cerebras event today b/c I was having fun with my friends. But this is what I gather…
The new WSE-3T is on the same N5 node and same wafer size but doubled compute to 250 PF & doubled memory bandwidth to 43.2 PB/s which to me would mean a 2x clock increase which is minimum 2x the power. The prior WSE-3 consumed ~23 kW so let’s call it 40-55 kW per wafer. 3 wafers per rack or 130-180 kW for the entire system.
Rubin NVL72 is 72 packages x 288 GB of HBM4 @ 22 TB/s for a total of 1.6 PB/s at roughly ~200 kW.
So for CS-4 system we get ~0.9 PB/s per kW vs. ~8 TB/s per kW on Nvidia.
So roughly 100x more bandwidth per kilowatt and in practice it’s probably more cause Nvidia relies more on interconnect than Cerebras. Sooooo prettay prettay good 👍
But only 132 GB of SRAM vs. ~21 TB of HBM memory + 75 TB of LPPDR on Nvidia it’s a lil scaaaary. I’m all for a decode optimized accelerator but when you can’t fit a Qwen 3.8 or DeepSeek V4 on it I don’t know how much of a value add it really is. If I still need to buy an Nvidia rack to go along with my Cerebras rack why would I really bother? Fast tokens spend faaaaast money 💰!!! Good if you’re rich but sadly most of us are working class token consumers who can’t afford a Bugatti model.
That being said, the I/O board is a great addition (does it have FPGA???) and I don’t think the 7.2 TB/s is a big deal as latency is more important since this will only be used for inference. Also modular power solutions hmm .. 🤔 nice touch ! 😏
I see the vision. Giving Cerebras a B+ and I am excited to see what they do next, I can tell they are listening to some of the advice we gave them! Now let’s see if they are willing to diversify a bit so they can get those gross margins up. There’s still time to turn the boat 🛶 around!
Show more


The other day I was brainstorming content for a speech and I asked Claude:
> rewrite your last response but in the style of Strunk and White, with very little metaphor, less flowery, much more direct, plain, and minimal?
What it returned was still pretty flowery, so i said:
> This is still unnecessary metaphor: "The story is the on-ramp".
It removed that and a few other metaphors, but many remained. After a few more iterations, I could still not get Claude to omit needless words or stop using metaphor.
Then I had an idea. I told Claude:
> Pretend to be E.B. White and write criticisms of the above text
And it worked! E.g., Claude (pretending to be EB White) said:
> "Openness moved you." Openness moves no one; it has no hands.
Now that's what I'm talking about. Also:
> You have also let the office in. "Turn to the upside." "Hand off to the agenda." "Close on momentum." These are not English; they are the noises men make in meetings.
I was happy. This seemed to be working! (Though I thought it was ironic how flowery the tone of the criticism itself was, I don't imagine E.B. White would ever say "noises men make in meetings".) So then I said:
> "rewrite the above as though you are White and apply all of the changes you advocated for"
And Claude finally produced what I had been looking for in the first place, a bunch of simple declarative sentences about concrete things that add up to a strong point stated only once.
A few reflections:
1) frontier LLMs can be more effective when you separate out reasoning (e.g., "critique this as EB White") and action (e.g., "now factor that feedback in") into two requests.
2) asking an LLM to impersonate a specific famous human is a high-information type of instruction. I've been using the same technique with coding agents: "critique that design doc as Ken Thompson" (or John Ousterhout, etc.)
Show more