Search results for AgentDevelopment
AgentDevelopment community
One keyword maps to one global community path.
People
Not Found
Tweets including AgentDevelopment

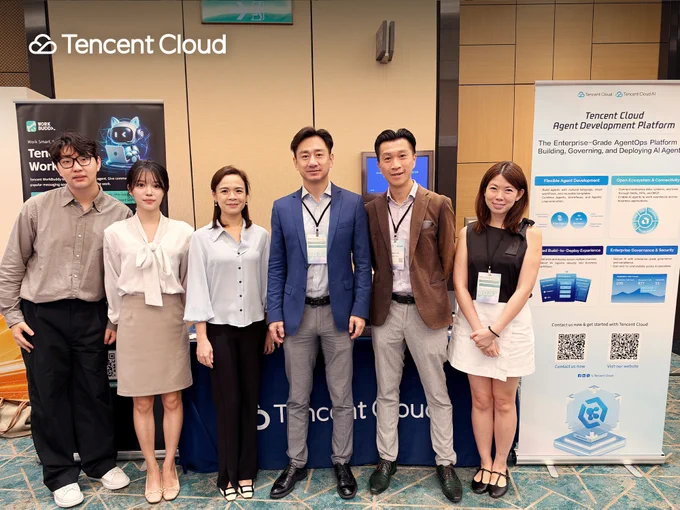
The HKIB Annual Banking Conference 2026 brought together over 900 industry professionals to explore what it truly means to "Transform to Excellence." It was incredible to connect with so many banking leaders at the Tencent Cloud booth as we explored the future of digital banking.
We were thrilled to showcase how Tencent Cloud is enabling banks to enhance their day-to-day operations through:
🚀 WorkBuddy: Transforming collaboration and productivity.
🤖 Agent Development Platform: Empowering banks to build intelligent AI agents that streamline workflows and decision-making.
🔐 eKYC: Delivering secure, seamless, and compliant digital identity verification for a smoother customer onboarding experience.
🏢 Tencent Cloud Enterprise: Providing a robust, scalable foundation for banks to modernise their infrastructure and operations.
📈 Tencent Marketing Cloud: Helping banks engage customers with data-driven insights and personalised experiences across every touchpoint.
The conversations we had about empowering banking professionals with AI-driven tools and end-to-end digital solutions were truly inspiring. Thank you to everyone who stopped by to share and interact with us!
#TencentCloud# #HKIB2026# #BankingConference# #FinTech# #DigitalTransformation# #AI# #AgentDevelopment# #WorkBuddy# #eKYC# #TencentCloudEnterprise# #TencentMarketingCloud# #FutureOfBanking# #HongKong#
Show more




# Decision Points in AI Agent Development
🎯 The Hook
When something goes wrong, do you stop immediately or keep going at reduced quality? The uniquely difficult thing about AI agents is that outputs routinely land in a gray zone: "partially correct, partially wrong." Eight out of ten items are right, but two are inaccurate. Is returning that partial result helpful or dangerous? This is a different kind of judgment from traditional software's binary pass/fail.
📋 Overview
This is a design decision about how AI agents behave when encountering errors or anomalies. Fail-fast means immediately halting and returning an explicit error. Graceful degradation means reducing quality or functionality while still returning some result. At any individual error point, this is a binary choice -- stop or continue -- with no middle ground. However, different error types can be assigned different policies.
🔍 Decision Points
The key axes are the damage from acting on partial results and the latency budget.
📌 Partially incorrect results flowing downstream causes serious harm → Fail-fast. Financial transactions, medical decisions, legal document generation. The damage from partial errors being treated as correct far exceeds the cost of halting and retrying.
📌 Partial results are hard to distinguish from complete results → Fail-fast. If degraded output risks being mistaken for complete output, an explicit error is safer. False confidence is more dangerous than fail-fast.
📌 Partial results are better than nothing → Graceful degradation. When summarizing 10 documents and 2 fail to fetch, returning 8 summaries is more useful than just an error message.
📌 Quality degradation can be explicitly communicated → Degradation works well. When you can clearly state "1 of 3 sources could not be retrieved," partial results are genuinely useful.
📌 Accountability is required → Lean toward fail-fast. When you must explain "why this incomplete result was returned," explicit errors are easier to manage.
💡 Key Details
🔹 The essential value of fail-fast is preventing problem concealment. When a problem is detected, an alert fires immediately, enabling rapid root-cause investigation and resolution. With graceful degradation, problems can be masked and by the time they surface, the blast radius may have expanded significantly.
🔹 The essential value of graceful degradation is maintaining availability. In many scenarios, partial functionality is more useful to users than complete shutdown. Additionally, when fail-fast forces re-execution of the entire process, tokens consumed by the successful portions are wasted -- degradation can be more cost-efficient.
🔹 The biggest risk of graceful degradation: partial results flowing downstream indistinguishable from complete results. When downstream systems cannot differentiate "normal response" from "degraded response," batch processes run on incomplete data, or degraded states persist undetected for extended periods.
⚖️ Trade-offs
Fail-fast gains safety and early error detection at the cost of reduced availability and retry expenses. When a long-running process is aborted at the final stage, all prior token spend is wasted. Graceful degradation gains availability and cost efficiency at the risk of incomplete results being treated as authoritative.
🏆 The proven approach is a degradation ladder with severity levels:
Level 1 (minor): partial data missing → return the rest with explicit notation of what's missing
Level 2 (moderate): primary model failure → switch to fallback model with explicit quality disclaimer
Level 3 (critical): core data missing or integrity errors → fail-fast
When in doubt, ask yourself: "If a user acts on this partial result, could irreversible damage occur?" If the answer is yes, fail-fast.
🛠️ Use Cases
💰 Financial transaction automation → Fail-fast. Partially incorrect trade instructions being executed is irrecoverable. An error message with retry is far safer.
📚 Document summarization service → Graceful degradation. When some document fetches fail, return summaries for what was retrieved with "summarized M of N documents" explicitly stated. More useful than an error message.
🤖 Conversational assistant → Graceful degradation. When one tool call fails, compose an answer from other sources with "some information could not be retrieved" appended. Far better UX than complete shutdown.
📊 Data pipeline → Fail-fast. Downstream batch processes running on incomplete data creates cascading impact. Stop, fix, and re-run is safer.
🏥 Medical decision support → Fail-fast. Judgment based on partial test results is dangerous. When required information is incomplete, return an explicit error and defer to human judgment.
#AIAgents# #SoftwareArchitecture#
Show more
# Decision Points in AI Agent Development
🎯 The Hook
Are you asking your LLM to calculate taxes? One of the most common mistakes in AI agent development is having the LLM reason through tasks that code could solve instantly. Wasted tokens, inconsistent results, impossible debugging. But the inverse is equally dangerous: trying to handle natural language interpretation with if-else chains until you drown in edge cases. Drawing the right line between LLM and code is essential.
📋 Overview
For each processing step in an AI agent, the design question is whether to have the LLM reason in natural language or delegate to conventional code and tools. LLMs are probabilistic -- they may return different outputs for the same input -- but excel at interpreting ambiguous inputs and handling unforeseen cases. Code is deterministic -- same input always yields same output -- and is easy to test, but cannot handle cases not anticipated in advance. Correctly leveraging this asymmetry determines the system's reliability and cost efficiency.
🔍 Decision Points
The heuristic is simple: can you write it as if-else?
📌 Fully describable by rules, procedures, or algorithms → Delegate to code. Tax calculation, inventory aggregation, date comparison, schema validation, format conversion. Having the LLM do these wastes tokens and risks errors. LLMs are notoriously bad at arithmetic and precise string operations.
📌 Input is natural language requiring intent interpretation → Let the LLM reason. Structuring a user's vague request is the LLM's sweet spot. Interpreting "reschedule tomorrow's meeting" -- what "tomorrow" means and what "reschedule" entails -- cannot be handled by if-else.
📌 Classification categories change dynamically, judgment criteria are context-dependent → LLM. When you cannot enumerate all cases in advance, code leads to edge-case explosion.
📌 Generation, summarization, translation, or other creative tasks → LLM. These are simply not achievable with code.
📌 Calculation errors are unacceptable → Code is mandatory. Financial calculations, permission checks, inventory management. Probabilistic LLMs should not be trusted here.
💡 Key Details
🔹 LLMs excel at deciding "what to do"; code excels at executing "how to do it." This asymmetry is the foundational design principle for agent systems. The most common and effective architecture has the LLM handle planning, classification, and interpretation while code handles computation, validation, and execution.
🔹 The litmus test: if the input determines a unique output, it is code's job. Calculations, lookups, format conversions, validations, database operations -- all code.
🔹 Symptoms of over-delegating to LLM: same input returns different results, triggering "the answer was different last time" complaints. Token spend far exceeds projections, and analysis reveals most is spent on code-replaceable tasks. High test flake rates destabilize CI/CD.
🔹 Symptoms of over-delegating to code: every new request type requires adding classification rules or parsers, slowing development. If-else chains balloon and become unmaintainable. Unexpected inputs get blanket error responses, rejecting requests the system could have handled.
⚖️ Trade-offs
LLM gains flexibility and generality at the cost of reproducibility, expense, and debuggability. Code gains determinism and efficiency at the cost of flexibility and requires code changes for new cases.
🏆 The default is: if it can be solved deterministically, delegate to code. LLMs are expensive, inconsistent, and hard to debug. Limit LLM usage to tasks that code genuinely cannot solve. This is the core philosophy of "probabilistic judgment to the LLM, deterministic control to code."
🛠️ Use Cases
🧮 Expense reimbursement bot → Hybrid. Information extraction from receipt images and expense category classification go to the LLM. Tax calculation, total computation, and policy compliance checks are code.
🔍 Customer support → Hybrid. Intent classification of user inquiries goes to the LLM. Order status lookup, refund processing, and inventory checks are code (API/DB calls).
📊 Data analysis assistant → Hybrid. Interpreting "compare last month's sales by region" goes to the LLM. Actual query generation, execution, and aggregation are code. Summarizing and interpreting results goes back to the LLM.
⚠️ Anti-pattern: asking the LLM "what is 123 times 456?" LLMs can get arithmetic wrong. One line of `123 * 456` gives the guaranteed correct answer every time.
#AIAgents# #SoftwareArchitecture#
Show more
# Decision Points in AI Agent Development
🎯 The Hook
Your LLM generates an output. You ask the same LLM "is this correct?" and it says yes. Feeling reassured? You shouldn't be. That's like proofreading your own essay -- except worse. LLM hallucinations are generated with high confidence, so the same model that produced the error will confidently confirm it's correct. Whether to use a separate verification system or rely on self-reflection is a decision that determines output quality.
📋 Overview
After an AI agent generates output, you need to decide whether to verify it using the same system (same model, same prompt chain -- "self-reflection") or an independent system (different model, different prompt, or deterministic code like schema validation and database lookups). Same-system verification inherits the generation model's biases, knowledge limits, and hallucination tendencies. Separate-system verification is structurally decoupled from those biases. This is a binary choice -- the verification system either shares the generator's weights or it doesn't.
🔍 Decision Points
The core question is how much damage occurs when a flawed output passes through.
📌 High-stakes domains (finance, healthcare, legal) → Separate verification. When incorrect output flowing downstream causes irreversible damage, you need structural bias elimination.
📌 Factuality verification required → Separate verification is essential. Hallucination detection is fundamentally difficult for the model that produced the hallucination. Cross-referencing with external knowledge sources or deterministic code is the only reliable approach.
📌 Accountability requirements → Separate verification is stronger. When explaining "why we judged this output correct" to a third party, self-reflection by the same model is a weak justification. Results from an independent verification system carry more weight.
📌 Casual conversation or draft generation → Same-system is sufficient. The cost of separate verification is not justified when some errors are acceptable.
📌 Extremely tight latency budget → Same-system. If the additional latency of separate verification is unacceptable, a quick self-check is the pragmatic choice.
💡 Key Details
🔹 The nature of self-confirmation bias: LLMs tend to evaluate their own outputs favorably. This is similar to how humans overlook their own typos, but in LLMs it manifests more systematically. Hallucinations are especially problematic because they are "errors the model generated with conviction" -- the same model's self-check cannot detect what it was already confident about.
🔹 The structural advantage of separate verification: when the generator's biases and the verifier's biases are independent, the probability of both failing in the same direction drops dramatically compared to either failing alone. Deterministic code verification (JSON schema checks, numerical range validation, external database lookups) has zero probabilistic error -- it is the most reliable verification method available.
🔹 The design advantage of separation: generation requires creativity and flexibility; verification requires precision and strictness. These are opposing requirements. Rather than forcing one system to do both, dedicated verification systems can be optimized for their purpose -- temperature set near zero, prompts tuned for a critical, error-finding stance.
⚖️ Trade-offs
Same-system verification is simple to implement, low cost, and has full access to the generation context. But it has a critical blind spot: it cannot catch hallucinations. Separate-system verification structurally eliminates bias and is more trustworthy, but adds model inference cost, latency, and complexity in transferring the full generation context to the verifier.
🏆 The proven approach is a two-stage pipeline. First stage: same-system self-reflection catches formatting and logical consistency issues. Second stage: separate-system final verification via deterministic code or an LLM Judge confirms factuality and quality. The first stage removes obvious problems, reducing the cost of the more expensive second stage.
🛠️ Use Cases
💰 Financial report generation → Separate verification. Numerical accuracy is verified by deterministic code (re-executing calculations, cross-referencing external data). Self-reflection is nearly incapable of catching numerical errors.
📝 Blog post drafting → Same-system is fine. Self-reflection suggests improvements to logic flow and expression. A human does the final review, so the rigor of separate verification is unnecessary.
🏥 Medical information factuality → Separate verification mandatory. Double verification: cross-referencing against a medical literature database (deterministic) plus a cross-check by a different model.
🤖 Code generation → Separate verification. Correctness of generated code is verified not by LLM self-reflection but by actually compiling and running tests (deterministic code). This is the most reliable verification method available.
#AIAgents# #SoftwareArchitecture#
Show more
# Decision Points in AI Agent Development
🎯 The Hook
Do you validate every agent output before it reaches the user, or let it through and audit a sample afterward? "Check everything for safety" sounds right, but adding semantic validation with another LLM call effectively doubles your cost and latency per request. On the flip side, deciding "post-hoc is fine" can mean hallucinations reach users and become incidents. Here's how to find the right balance.
📋 Overview
This is a design decision about when to validate AI agent outputs. Inline validation checks every output in real time immediately after generation, blocking anything that fails. Post-hoc / sampling validation lets outputs through first, then audits them in batch or via random sampling. It is fundamentally a trade-off between quality assurance and latency, coming down to whether you prioritize the cost of bad outputs reaching users or the latency budget.
🔍 Decision Points
The primary axis is the cost of a bad output reaching the user.
📌 Legal risk, financial loss, or safety concerns → Inline validation is mandatory. Financial advice, medical information, legal documents, externally published content -- when unqualified output reaching users is unacceptable, you need full blocking.
📌 UX degradation or manual correction needed → Inline for high-risk paths only, post-hoc for the rest. Not every output needs the same rigor.
📌 Internal tools, draft generation, exploratory output → Post-hoc sampling is sufficient. Sample 5-10% of outputs for quality monitoring, discover problem patterns, and feed improvements back into prompts and guardrails.
The secondary axis is the latency budget.
📌 Sub-200ms response required → Inline validation limited to structural checks (schema validation, range checks). Semantic validation moves to post-hoc.
📌 Standard 1-10s latency → Full inline validation stack (structural + rule-based + semantic) is feasible.
📌 30s+ batch processing → Apply full inline validation on every item, plus deeper post-hoc analysis.
💡 Key Details
🔹 Inline validation works best as a three-tier stack. Tier 1: structural validation (JSON schema, PII detection) at a few milliseconds. Tier 2: rule-based validation (policy engine, OPA/Rego) at 10-50ms. Tier 3: semantic validation (separate LLM for factuality checking) at hundreds of milliseconds to seconds. Not every path needs all three tiers.
🔹 The hidden strength of post-hoc validation is depth. Without real-time constraints, you can run multi-LLM-Judge cross-checks, human reviews, and external data source verification. The real value is the feedback loop: discovering problem patterns in samples and using them to improve guardrails and prompts.
🔹 The critical weakness of post-hoc validation: some outputs cannot be recalled once delivered. Sent emails, external API calls, content already displayed to users -- these are irreversible. If the output triggers an irreversible side effect, post-hoc is too late.
⚖️ Trade-offs
Inline validation guarantees safety but adds latency and cost. Applying semantic validation to every output effectively doubles your LLM spend. High false-positive rates (blocking valid outputs) cause retry cascades that degrade UX. Post-hoc validation has zero latency impact and enables deeper analysis, but accepts a "leakage window" where problematic outputs reach users.
🏆 The proven pattern is a hybrid: inline for high-risk paths, post-hoc sampling for low-risk paths. In practice, the most effective structure is "inline (structural + rule-based) + post-hoc (semantic deep-dive)." Structural validation has minimal latency impact, so run it inline on everything. Expensive semantic validation is inline only for high-risk paths; the rest gets sampled post-hoc.
🛠️ Use Cases
🏥 Medical information chatbot → Full inline validation. All three tiers including factuality checking via separate LLM. The cost of hallucination reaching a patient far outweighs validation latency.
💬 Internal Slack bot → Post-hoc sampling. Internal use tolerates some errors. The important thing is the feedback cycle: sample, find patterns, improve prompts.
🛒 E-commerce product description generation → Hybrid. Structural validation (price ranges, required fields) inline; expression appropriateness validated post-hoc.
📧 Automated email replies → Inline validation. Sent emails are irreversible side effects. PII leakage and policy violation detection must happen before sending.
#AIAgents# #SoftwareArchitecture#
Show more
# Decision Points in AI Agent Development
🎯 The Hook
Single LLM provider or multi-provider? "We should use multiple providers for resilience" sounds prudent, but have you priced in the real cost? Maintaining abstraction layers, tuning prompts per provider, running parallel quality evaluations. The overhead of multi-provider is routinely underestimated. On the other hand, are you comfortable betting everything on one vendor?
📋 Overview
This is about whether your AI agent should use a single LLM provider (OpenAI, Anthropic, Google, Azure OpenAI, etc.) or multiple providers in parallel. "Provider" here means the API vendor, not different models within the same vendor. Each provider differs in API specification (tool calling format, streaming protocol, error codes), pricing, rate limits, and availability SLA. Moving to multi-provider ripples through infrastructure, prompts, and evaluation -- operational cost increases non-linearly.
🔍 Decision Points
The key axes are provider trust and system availability requirements.
📌 SLA requirement is 99.9%+ and the provider's track record falls short → Consider multi-provider. LLM provider outages and rate limits tend to be more frequent and less predictable than traditional SaaS.
📌 Heavy dependency on provider-specific features (prompt caching, batch API, fine-tuning) → Stay single-provider. An abstraction layer reduces you to the lowest common denominator, losing provider-specific optimizations.
📌 Small team → Stay single-provider. If you lack the resources to maintain parallel prompt tuning and quality evaluation across providers, quality management on the secondary provider will suffer.
📌 Regulatory or data sovereignty requirements → Multi-provider. When certain requests must be routed to specific regions or providers, there is no alternative.
💡 Key Details
🔹 Single provider's greatest asset is depth of optimization. You can focus prompt tuning on one model family and leverage prefix caching and context caching for major cost and latency reductions. Output quality, style, and structured output precision remain stable.
🔹 Multi-provider's greatest asset is fault tolerance. When Provider A goes down, automatic failover to Provider B maintains availability. Task-based provider selection also enables cost optimization. The "always ready to switch" posture doubles as negotiation leverage.
🔹 The hidden costs of multi-provider: building and continuously maintaining adapters that absorb API differences (tool calling formats, streaming protocols, error codes) across providers. The same prompt performs differently across providers, requiring per-provider prompt tuning and evaluation. Pre-validating quality degradation during failover scenarios.
⚖️ Trade-offs
Single provider gains depth of optimization and operational simplicity at the cost of vendor lock-in and availability risk. Multi-provider gains fault tolerance and strategic flexibility at the cost of abstraction layer maintenance and quality management complexity.
🏆 The proven approach: start with a single provider behind an abstraction layer. Use something like LiteLLM or an AI Gateway from day one, even with just one provider. When availability or cost issues surface, adding a second provider becomes a manageable migration rather than a rewrite. Direct integration without an abstraction layer makes future migration prohibitively expensive.
🛠️ Use Cases
🚀 Startup MVP → Single provider with abstraction layer. Prioritize development speed, but keep the door open for multi-provider later.
🏥 High-SLA systems (healthcare, finance) → Multi-provider. When downtime is unacceptable, pre-validate your failover target and combine with circuit breaker patterns for automatic switchover.
🌍 Global deployment with data sovereignty → Multi-provider. Route EU requests to EU-based providers, Japan requests to domestic regions.
📊 High-traffic systems → Multi-provider. Distribute traffic across providers for rate limit relief and cost optimization.
#AIAgents# #SoftwareArchitecture#
Show more
# Decision Points in AI Agent Development
🎯 The Hook
RAG, fine-tuning, or long context? When giving your LLM domain knowledge, the default answer of "just use RAG" is not always right. Each approach stores, updates, and retrieves knowledge in fundamentally different ways, and picking the wrong one leads to stale answers, missing citations, or runaway token costs. Let's break down how to choose.
📋 Overview
There are three primary methods for equipping AI agents with domain-specific knowledge. RAG (Retrieval-Augmented Generation) searches an external knowledge base and injects relevant information into the prompt at inference time. Fine-tuning (FT) adjusts model weights through additional training, baking knowledge into the model itself. Long context feeds entire documents directly into a large context window. Because each method differs in where knowledge lives, how it updates, and what it costs, you need to pick a primary approach for each use case.
🔍 Decision Points
The core question is: how often does the knowledge change, and do you need to cite your sources?
📌 Knowledge changes frequently → RAG. FAQ entries, pricing, inventory data: just re-index and you're current. FT requires days-to-weeks of retraining -- impractical for volatile information.
📌 Source attribution is required → RAG again. Only RAG can point to "page 12 of document X" as the basis for an answer. FT-baked knowledge becomes "the model just knows," with no way to trace it back. This is a dealbreaker in high-accountability environments.
📌 Output style and tone must be consistent → FT. "Always respond in legal-document format" is hard to enforce through RAG-injected examples. FT embeds the behavior at the model level, eliminating the need for in-context demonstrations and saving context window space.
📌 Few documents, full structure matters → Long context. For tasks like interpreting an entire contract where cross-section references matter, chunking destroys context. Feeding the whole document into a large window preserves structural relationships.
💡 Key Details
🔹 RAG's fundamental strength is the separation of knowledge from the model. Knowledge lives in an index; reasoning lives in the model. This decoupling means knowledge updates never require retraining. The trade-off: output quality depends heavily on retrieval quality -- chunk splitting, embedding model choice, and reranking strategy all need tuning.
🔹 FT's fundamental strength is stable behavioral transformation. For tasks requiring consistent output format, it can actually be cheaper per request than RAG (no retrieval cost, no prompt injection tokens). The trade-off: updating knowledge requires the full dataset-preparation, training, and validation cycle.
🔹 Long context's fundamental strength is implementation simplicity. No vector DB, no retrieval pipeline, no chunking, no training infrastructure. The trade-off: token-based pricing makes costs scale linearly with document size, and the "Lost in the Middle" phenomenon (attention weakening for mid-window content) limits reliability as input grows.
⚖️ Trade-offs
RAG excels at freshness and attribution but requires building and maintaining a retrieval pipeline. FT excels at stylistic consistency but is slow to update and opaque about sources. Long context is the simplest to implement but constrained in cost and scalability.
🏆 The production playbook is often a hybrid: FT for style, RAG for facts. Fine-tune the model for output format, tone, and terminology. Use RAG to inject up-to-date factual information at inference time. Use long context as a complement to RAG when chunk splitting would destroy important document structure.
🛠️ Use Cases
🏢 Internal knowledge base Q&A → RAG. Documents update daily, and answers need source citations.
⚖️ Legal document review → FT + RAG. FT unifies legal tone and format; RAG injects current case law and regulations.
📄 Full contract interpretation → Long context. Feed the entire contract in and let the model reason across clauses.
🏥 Medical information → RAG is mandatory. Source attribution is non-negotiable, and information freshness is critical. Medical knowledge baked in via FT is indistinguishable from hallucination -- dangerous.
When in doubt, start with RAG. In most business systems, knowledge is a living thing, and the ability to cite sources is the foundation of trust.
#AIAgents# #SoftwareArchitecture#
Show more
# Decision Points in AI Agent Development
# Prompt Control vs Code/Policy Control 🛡️
🎯 The Hook
When constraining agent behavior, you either "ask nicely" via prompt or "build a wall" in code. This distinction maps directly to probabilistic compliance versus deterministic enforcement. Writing "do not output personal information" in a prompt can be overridden by prompt injection or diluted by context expansion. A regex that detects and blocks PII patterns works reliably regardless of what the LLM decides. The real question is: which constraints do you elevate to code?
📋 Overview
Prompt control writes constraints into the LLM's system prompt or instructions to guide behavior. Typical techniques include few-shot examples, negative instructions, and role setting. Code/policy control implements constraints as executable code (conditionals, regex, schema validation) or via policy engines (OPA/Rego, Cedar, etc.), forcibly controlling LLM inputs, outputs, and operations.
🔍 Decision Points
Two variables drive this decision: **failure cost** and **accountability**.
📊 **By constraint type**:
Enforce with code/policy:
- 🔒 Boundary and legal constraints (PII output prohibition, amount limits, forbidden operations)
- 🔒 Irreversible operation restrictions (deletion, transfers, publication)
- 🔒 Output format enforcement (JSON schema, value range validation)
Guide with prompts:
- 💬 Response quality and style (tone, politeness, technical terminology usage)
- 💬 Context-dependent judgment guidelines (what to prioritize under which circumstances)
💡 Key Details
🟢 **Prompt control excels in flexibility and expressiveness.** Written in natural language, it can instruct subtle nuances and context-dependent behavior. "Use formal language for legal teams, allow technical jargon for engineers" is naturally expressed in a prompt. Changes require only rewriting the prompt -- no deployment. The weakness is low reliability: constraints can break under prompt injection, context expansion, and model updates. Version control, testing, and auditing are also difficult.
🟡 **Code/policy control excels in certainty and auditability.** Constraints are version-controlled as code, verified by unit tests, and preserved as audit trails. "Why was this output blocked?" is uniquely identified by the policy version and rule ID. It is immune to prompt injection and model updates. With policy engines, rule changes can be reflected without deployment. The weakness is limited expressiveness -- qualitative constraints like "respond politely" cannot be expressed in code.
⚖️ Trade-offs
| Dimension | Prompt Control | Code/Policy Control |
|---|---|---|
| Reliability | Probabilistic (can break) 🔴 | Deterministic 🟢 |
| Expressiveness | High (nuance capable) 🟢 | Low (condition → judgment only) |
| Auditability | Requires prompt history tracking | Version control + audit trails 🟢 |
| Injection resistance | Vulnerable | Immune |
| Change velocity | Prompt rewrite only | Policy update or deployment |
| Development cost | Low | Infrastructure + skills needed |
🛠️ Use Cases
🔵 **Prompt control fits**: Response tone and style guidance, context-dependent judgment guidelines, cases where constraint violation impact is minor.
🔴 **Code/policy control fits**: PII and financial data output control, irreversible operation restrictions, regulated processes, strict output format validation.
📌 **Default strategy**: "Boundaries (constraints that must not break) go in code; guidance (desirable behavior) goes in prompts." When in doubt, ask yourself: "How much does it hurt if this constraint is violated?" If the pain is significant, enforce it in code. If minor, guide it via prompt. The most practical architecture is a two-layer structure: policy enforcement plus prompt guidance. Code/policy deterministically enforces boundaries while prompts guide LLM behavior within those boundaries. Even when prompt guidance fails, policy acts as the final safety net.
#AIAgents# #SoftwareArchitecture#
Show more
# Decision Points in AI Agent Development
# Plan-then-Execute vs ReAct 📝
🎯 The Hook
"How far ahead do you look before you move?" This is an inescapable fork in agent design. Do you build a plan first, then execute it? Or do you alternate between observation and action one step at a time? Whether a plan exists as an explicit artifact -- reviewable, approvable, debuggable -- changes everything about approval flows, cost control, and debugging. LLM calls are expensive, so planless trial-and-error wastes tokens. But in dynamic environments, even a carefully crafted plan goes stale mid-execution.
📋 Overview
Plan-then-Execute generates a structured execution plan (JSON/YAML) before any action is taken. The plan includes step ordering, tools and arguments for each step, and expected results. After the plan is finalized (and optionally approved by a human), steps are executed sequentially. ReAct has the LLM repeat an observe-reason-act cycle one step at a time. There is no explicit plan -- the "plan" is implicit in the LLM's internal reasoning at each step and is not externally accessible.
🔍 Decision Points
**Task variability** is the primary axis.
📊 **By environment dynamism**:
- Static (data and external state rarely change during execution) → Plan-then-Execute
- Semi-static (mostly stable but some steps encounter state changes) → Plan-then-Execute + re-planning on deviation
- Dynamic (each step's result heavily influences the next choice) → ReAct
📊 **By task nature**:
- Procedures are routine and humans want to approve in advance → Plan-then-Execute
- Procedures are roughly known but details are determined at runtime → Plan-then-Execute (coarse plan + runtime adjustment)
- Procedures are unknown and exploration is needed → ReAct
When **failure cost** is high (irreversible operations involved), there is a strong motivation toward Plan-then-Execute.
💡 Key Details
🟢 **Plan-then-Execute excels in transparency and control.** The plan is an explicit intermediate artifact, so humans can verify "is this procedure safe?" before execution. Plans containing irreversible operations can be reviewed in advance, securing safety. Debugging separates "was the plan wrong?" from "was the execution wrong?" Planning also prunes unnecessary steps, reducing token consumption. The weakness is plan staleness -- environmental changes can trigger a meta-loop of plan-fail-replan, so re-planning attempts should be capped at 2-3.
🟡 **ReAct excels in adaptability.** It responds to environmental changes at the granularity of individual steps and handles unexpected situations (API errors, unexpected data formats, additional user information) flexibly. It suits environments too dynamic for upfront planning and tasks requiring exploratory progress. Implementation is simpler too -- no infrastructure for plan generation, storage, validation, or re-planning. The weakness is unpredictability and cost: the number of steps is unknown in advance, and self-loop risk is real.
⚖️ Trade-offs
| Dimension | Plan-then-Execute | ReAct |
|---|---|---|
| Transparency | Plan is an explicit artifact 🟢 | Implicit (LLM internal reasoning) 🔴 |
| Human approval | Approve entire plan upfront | Must intervene per step |
| Cost control | Upper bound estimable from step count | Unknown in advance |
| Adaptation to change | Re-planning needed (added cost) | Per-step adaptation 🟢 |
| Debugging | Separate plan vs. execution investigation | Must analyze all step logs |
| Implementation complexity | Plan infrastructure required | Loop control only |
🛠️ Use Cases
🔵 **Plan-then-Execute fits**: Processes with irreversible operations, workflows requiring human approval, cost-sensitive processing, routine procedural tasks.
🔴 **ReAct fits**: Debugging and investigation, processing in dynamically changing environments, tasks with unknown procedures requiring exploration, prototype development.
📌 **Default strategy**: Default to Plan-then-Execute, and make plans human-editable. The most practical compromise is "plan first, re-plan only on deviation." Build the plan, execute steps, and trigger re-planning only when execution results diverge significantly from expectations. Re-planning includes failure context to avoid repeating the same mistakes. Cap re-planning attempts at 2-3.
#AIAgents# #SoftwareArchitecture#
Show more
# Decision Points in AI Agent Development
# Orchestration vs Choreography 🎼
🎯 The Hook
When coordinating multiple agents or services, you face a fundamental choice: place a conductor at the center, or let each component dance autonomously? Orchestration means a central authority controls everything. Choreography means each component reacts to events on its own. The locus of control is fundamentally different, and it shapes fault handling, auditing, debugging, and scaling in entirely different ways.
📋 Overview
In orchestration, a central orchestrator defines the entire workflow, invokes components sequentially or in parallel, aggregates results, and decides the next step. Temporal, Airflow, and LangGraph's Supervisor pattern are typical implementation platforms. In choreography, each component subscribes to events on an event bus (Kafka, EventBridge, etc.), autonomously processes events it cares about, and publishes new events. No central entity knows the overall control flow.
🔍 Decision Points
The primary axis is **accountability**.
🏛️ **Favor orchestration when**:
- You need to explain the overall flow and decision rationale at each step after the fact
- Strict sequencing constraints exist (review → approval → execution)
- LLM outputs need validation or transformation before passing to the next step
- Central budget management (tokens, time, cost) is required
- Component count is roughly 10 or fewer
🌊 **Favor choreography when**:
- High throughput and high scale are required and a central point becomes a bottleneck
- Many teams independently develop and deploy components
- "Reacting to events" is the primary processing pattern (notifications, logging, async aggregation)
- Strict execution order tracking is unnecessary
💡 Key Details
🟢 **Orchestration excels in clarity of control and auditability.** The entire workflow is defined in one place, so "how far have we progressed" and "why was this step executed" are always clear. Recovery from failures pinpoints exactly which step failed and resumes from there. Agent-specific advantage: LLM outputs can be validated before proceeding to the next step, blocking hallucination propagation at each stage.
🟡 **Choreography excels in loose coupling and scalability.** Components share only event schemas and know nothing about each other's existence. Adding a new component is just adding an event subscription -- no changes to existing components. Each component scales independently, with the event bus acting as a buffer to absorb temporary load spikes.
⚖️ Trade-offs
| Dimension | Orchestration | Choreography |
|---|---|---|
| Overall state visibility | Always clear 🟢 | Requires event log correlation 🔴 |
| Auditability | High (causal chains are traceable) | Low (distributed tracking needed) |
| Scalability | Central becomes bottleneck | Independent component scaling |
| Coupling | High (changes concentrate on center) | Low (schema sharing only) |
| Hallucination control | Validate at each step | Each component needs own guardrails |
| Team independence | Orchestrator changes cause conflicts | Independent development and deployment |
🛠️ Use Cases
🔵 **Orchestration fits**: Business systems, regulated processes, review-approval workflows, processing requiring LLM output validation. Environments demanding accountability.
🔴 **Choreography fits**: High-throughput event-driven processing, notification/log aggregation/analytics pipelines. Large-scale systems where many teams independently develop components.
📌 **Default strategy**: For business systems, orchestration (centralized) is the default. In systems involving AI agents, a central entity that controls and validates LLM's probabilistic outputs is critical for both safety and auditability. A practical compromise is "centralized core, event-driven periphery" -- the orchestrator manages the main business flow while peripheral async processing (logging, notifications, analytics) is loosely coupled via events.
#AIAgents# #SoftwareArchitecture#
Show more