Search results for Decoding
Decoding community
One keyword maps to one global community path.
People
Not Found
Tweets including Decoding

Decoding what IRS scrutiny on tax dodges means for ETFs


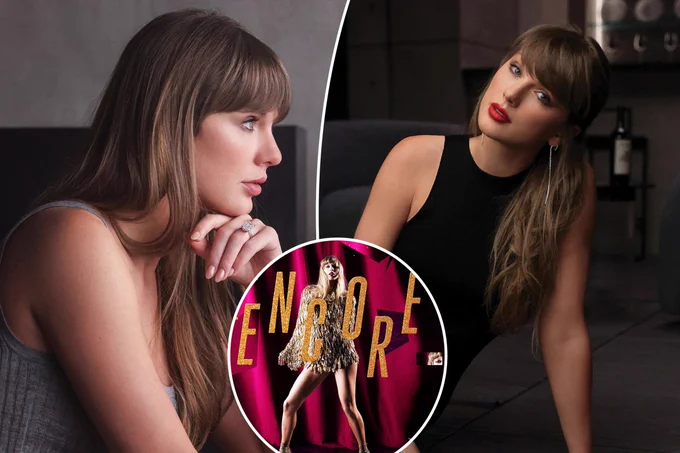
Decoding Taylor Swift’s 4 new ‘TLOAS: The Encore’ songs
Decoding story likes when you’re dating be like...
🎥: bananabonani


Spec Decoding (DSpark) finally works with Pipeline Parallelism in vLLM!! 🔥 A lot of the GPU poor/proletarian have been asking for this feature for a while now, but it took the recent Kimi K3's massive 2.8T parameters affecting the GPU middle class (B200) for it to be implemented!
Before this change, GPU poors that needed to use pipeline parallelism, as their weights didn't fully fit on 1 server, would not be able to take advantage of DSpark.
Shoutout to yongqinwang-cmd & Inferact for implementing it in vLLM!
Show more


Scientists are decoding the secrets of how water freezes.


Tired of decoding meeting notes that say, “As you can see on this slide…” without the actual visual? 🖼️
“Take notes for me” in Google Meet now includes screenshots of presented slides and visuals directly within the meeting notes to help you get a more complete picture.
Learn more in our latest drop →
Show more


Yesterday's special: decoding. Today's special: new routes. ✨
2027 new destinations:
Philadelphia to Reykjavik (Airbus A321neo)
Philadelphia to Vienna (A321XLR)
Philadelphia to Porto (A321XLR)
2027 new routes:
New York to Amsterdam (A321XLR)
New York to Nice (A321XLR)
Chicago to Tokyo (Boeing 787-9)
Charlotte to Barcelona (777-200ER)
New York to London Heathrow (787-9) (Fourth daily flight added)
2027 seasonal extensions:
Charlotte to Paris (777-200ER)
Miami to Milan (787-8)
Which route are you most excited for? Send this to your travel buddy and start planning now. Flights go on sale this Monday. ✈️
Show more

The NYSE welcomes @decodingbio in celebration of the 4th Annual AI x Bio Summit.

vLLM integrated PyNvVideoCodec to offload video decoding from CPU to GPU's NVDEC.
Result: 2x+ throughput at 8×H100, CPU bottleneck gone! This is huge for video captioning at scale (AV training, metadata), and ships with CUDA vLLM releases.
🔗
Show more


My talk about llama.cpp speculative decoding (MTP, dflash, dspark) at dotAI 🦙🦙 replay available soon!
