Search results for RateLimiting
RateLimiting community
One keyword maps to one global community path.
People
Not Found
Tweets including RateLimiting

Rate limiting inside application code is a classic trap. By the time your Node, Python, or Go process parses the incoming HTTP request, runs middleware, and executes a Redis check to reject a bot, the attacker has already consumed your application's CPU and memory allocations.
Show more

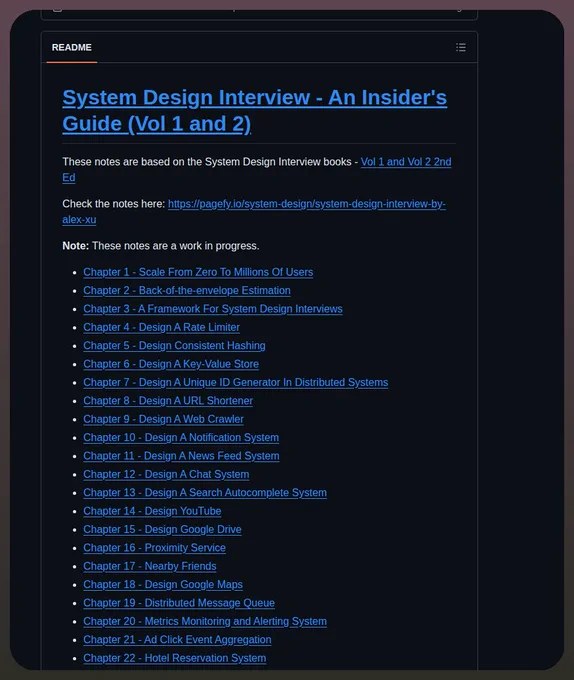
Breaks down system design interviews into 28 chapters on scaling, rate limiting, and distributed systems.

# Practical and Useful Patterns with ADK
## 🔌 Apply Cross-Cutting Concerns to All Agents at Once with Plugins
Setting up callbacks on every individual agent is tedious. ADK **Plugins** let you register once at the Runner level and apply security, logging, and rate limiting across all agents, tools, and LLM calls! 🎯
## 📌 Title
Plugins
## 🔗 URL
## 🧩 Overview
Plugins are cross-agent modules that operate at the Runner level. Unlike agent-specific callbacks, **a single registration applies to every agent, tool, and LLM call** in your application. They're ideal for cross-cutting concerns like security guardrails, logging, and rate limiting.
Plugins execute **before** agent-level callbacks, making them perfect for global policy enforcement.
ADK ships with built-in plugins: Reflect and Retry Tools, BigQuery Analytics, Context Filter, Global Instruction, and Logging Plugin.
## 🛠 How to Use
Import `BasePlugin` from `google.adk.plugins.base_plugin` and `InMemoryRunner` from `google.adk.runners`. Define `SecurityGuardPlugin` as a subclass of `BasePlugin`, initializing with `name="security_guard"`. Its `before_model_callback` method extracts user input from `llm_request.contents[-1].parts[0].text`, checks for injection via `detect_injection()`, and returns a rejection `LlmResponse` if detected. Its `before_tool_callback` method checks `is_authorized( and returns an error dictionary if access is denied. Both return `None` to continue when no issue is found. Finally, create an `InMemoryRunner` with `plugins=[SecurityGuardPlugin()]` to apply this guard to all agents automatically.
## 🏗 Practical Usage
**"Gemini as a Judge" pattern for injection detection:**
`InjectionDetectorPlugin` extends `BasePlugin` with `name="injection_detector"` and stores `self.judge_model = "gemini-flash-lite"` as its judge model. In `before_model_callback`, it extracts user input from `llm_request.contents[-1].parts[0].text` and passes it to `judge_with_flash_lite()` for fast injection detection. If the verdict is `"INJECTION"`, it calls `audit_log()` and returns a rejection `LlmResponse` to block the request. Otherwise, it returns `None`.
`RateLimitPlugin` extends `BasePlugin` with `name="rate_limiter"`, accepting a `max_calls_per_minute` parameter (default 60). It tracks call timestamps in ` and in `before_model_callback`, filters out entries older than 60 seconds. If the count meets or exceeds `self.max_calls`, it returns an `LlmResponse` with a rate limit message. Otherwise, it appends the current timestamp and returns `None`.
Finally, an `InMemoryRunner` is created with `plugins=[InjectionDetectorPlugin(), RateLimitPlugin(max_calls_per_minute=30)]` to combine multiple plugins for the production app.
## 💡 Use Cases
- 🛡️ **Security guardrails**: Centralized injection detection and PII protection across all agents
- 📊 **Unified logging**: Aggregate execution logs from all agents with the BigQuery Analytics plugin
- ⏱️ **Rate limiting**: Control API call frequency to prevent cost explosions
- 🔄 **Auto-retry**: Intelligent tool failure retries with the Reflect and Retry Tools plugin
- 📝 **Global instructions**: Inject shared policies or instructions into every agent
## ⚠️ Caveats
- Plugins execute **before** agent-level callbacks — be aware of precedence
- Returning a value from a plugin skips both the operation and any corresponding agent-level callback
- Since plugins apply to all agents, use Callbacks for agent-specific logic
- Error handling is available via `on_model_error_callback` / `on_tool_error_callback` hooks
- Available in Python v1.7.0+, TypeScript v0.2.5+, Go v0.4.0+, Java v0.3.0+
## ✨ Closing
Plugins deliver "write once, apply everywhere" for cross-cutting concerns. Delegate security, logging, and rate limiting to Plugins, and keep agent-specific logic in Callbacks. This separation improves both maintainability and security!
#ADK# #AIAgent#
Show more


As enterprises adopt multiple LLMs, tools and agents, managing authentication, routing, rate limiting and auditing becomes increasingly complex. How can you unify model access, authorization and observability on a single control plane?
In this episode of TCE Unboxing Time @TencentTCE, we demo AI Gateway capabilities of Tencent Cloud-Native Suite. Watch to learn:
1. Unified control plane for model authentication, routing, rate limiting and audit logging
2. Publish model services with OpenAI compatible protocol and consumer group access authorization
3. End to end demo: invoke model through the AI Gateway with consumer key
4. Observability: model metrics analysis and log delivery for troubleshooting
5. 3 in 1 gateway: LLM gateway, MCP gateway and Agent gateway for AI workloads
Tencent Cloud Enterprise is a full stack intelligent private cloud platform for enterprise grade on premises infrastructure.
Show more


Point the Google GenAI SDK at gemini-3.8-flash and the Netlify Function you already wrote keeps working the way it did before. AI Gateway handles caching, rate limiting, and auth underneath it. Available now.
Show more


A curious phenomenon: recently, people have been flocking to join Anthropic, while at the same time, a multitude of users are railing against the company (citing account bans, rate limiting, and built-in detection backdoors)...
Show more
# Practices for Embedding AI Agents in Software
# Tool Gateway / MCP Broker
🎯 The Hook
Your AI agent calls multiple tools directly? That's a distributed security nightmare waiting to happen. A single gateway layer turns chaos into a controlled chokepoint.
🔥 The Problem
When agents call external tools and MCP servers directly, authorization, rate limiting, and logging scatter across every integration. Prompt injection can sneak malicious arguments past individual tools, and audit trails become impossible to reconstruct when logs are spread across a dozen services.
💡 The Pattern
Route all tool calls through a single gateway that enforces authorization, input sanitization, rate limiting, and audit logging in one place. Use dynamic scoping to expose only the tools relevant to the current task and user permissions, keeping the LLM's selection space narrow. Apply asymmetric policies: write operations get fine-grained per-operation authorization and HITL approval, while read operations use lighter category-level checks. Adding or removing tools becomes a configuration change, not a code deployment.
✅ When to Use
Use when:
- The agent calls multiple tools, at least one with side effects
- User input or external data flows into tool arguments (low input trust)
- You need an audit trail of who called what, with which arguments, and under whose authority
Don't use when:
- There's only one read-only tool and gateway overhead isn't justified
- All tools are trusted internal services in an experimental environment where prototype speed matters more
⚠️ Pitfalls
- The gateway itself becomes a single point of failure. Design health checks and a degraded mode (e.g., read-only fallback)
- Never enforce authorization or sanitization via prompts. "Don't use this tool" instructions are trivially bypassed by injection
- Session-level rate limits alone won't stop distributed attacks. Add a global rate limit layer on top
🔧 Implementation Approach
- Define gateway policies declaratively (e.g., YAML), specifying type (read/write), authorization granularity, rate limits, sanitization rules, and log levels per tool
- Dynamically scope tools exposed to the LLM based on task type, user permissions, and conversation phase, excluding irrelevant tools from the selection space
- Design health checks and a degraded mode (read-only fallback) so the system survives gateway failures without total shutdown
- Normalize schemas across MCP servers at the gateway layer, presenting a consistent interface to agents regardless of backend differences
- Route high-risk code execution to sandboxed environments and use short-lived permission leases for long-running sessions
#AIAgents# #SoftwareArchitecture#
Show more


LLM providers are trying to build enterprise guardrails directly into their products, but it won't work.
Companies don't run on a single LLM any more, they're often using a mix of frontier models plus open-source and specialized vertical models spread across various use cases.
Model providers can improve their guardrails, but that won't fix the fragmentation problem. The industry tried this before!
In the early microservices era, every team baked auth, rate limiting, and logging directly into their apps, which worked fine until you had hundreds of services and no consistent enforcement or unified observability.
We abstracted the connectivity logic to the traffic layer back then, and you need to do it again with AI.
Effective AI governance (token budgets, permissions, compliance, etc) can't live inside a single model. You need a neutral layer that sits in front of everything. A "Switzerland for AI" as Khozema Shipchandler called it. A single control tower that manages all traffic regardless of source.
Show more


Following recent bridge exploits, Lido contributors are publishing the security principles behind wstETH’s multi-chain strategy, and why @chainlink CCIP was selected as the official cross-chain solution.
The analysis covers how Chainlink CCIP delivers strong decentralization, native safeguards, and issuer control as default protocol-level guarantees, which insulates wstETH from a number of attack vectors behind the Kelp / LayerZero exploit.
This decision was made last November by the Network Expansion Committee, with CCIP securing wstETH via 16 independent node operators, native rate limiting, and no vendor lock-in over token contracts.
Read the full breakdown from Lido contributors:
Show more


Wormhole delivers flexibility and simplicity in a decentralized ecosystem, without compromising security. SECURITY IS NOT A CHOICE.
The timeline is surfacing longstanding design criticisms that led to the LayerZero exploit: insecure defaults, centralization for operational convenience, and lack of circuit breakers.
Wormhole’s architecture is built to address these exact security failures.
Wormhole has two cross-chain token transfer products:
- NTT, the configurable token framework that powers products like @sunrise and is trusted by institutions and organizations like Apollo, Ripple, Solana, Monad, and M0.
- WTT, the interconnected token bridge that has enabled billions of value transfer across major ecosystems like Solana, Ethereum, Base, and Sui.
By default, Wormhole requires a decentralized network of 19 independent Guardian validators running in-house RPC nodes to come to 2/3 + 1 supermajority consensus (13/19) to approve cross-chain transfers.
NTT and WTT have two additional defense-in-depth security features: rate limiting and on-chain accounting.
- Rate Limiting: Asset issuers building on NTT can set their own on-chain rate limits to detect and delay unexpected cross-chain transfers. Wormhole’s Guardians set the rate limits for WTT based on recommendations and analysis from Wormhole’s security team @asymmetric_re.
-On-chain Accounting: Cross-chain transfers are first sent to an on-chain accounting system that limits withdrawals to the maximum supply minted to a chain. This feature could have substantially limited the blast radius of the rsETH exploit.
Wormhole contributors operate multiple internal and external off-chain monitoring and alerting systems and continue to ship new security features. As exploits become more sophisticated and are assisted by increasingly advanced AI tools, critical blockchain infrastructure must advance at an even faster pace and be built with multiple and robust layers of defense.
Hard-earned lessons have shaped how Wormhole operates: stronger defaults, hardened systems, and a relentless focus on security.
Show more