Search results for TerminalBench
TerminalBench community
One keyword maps to one global community path.
People
Not Found
Tweets including TerminalBench

TerminalBench did a great job with 4.0, highly recommend anyone interested in benchmarking read more about it, they put together a pretty detailed blog post that I've read twice now!
I have a ton of respect for what @ryan_marten is doing, learning a lot from him as I make my way in the wild world of benchmarking.
Show more


On the public TerminalBench traces, Astra runs into safety classifiers and their rollouts get stopped and scored as 0
Fable gets re-routed to Opus instead and the run continues.
Hard to compare scores that way!
Show more

(another) new SOTA on @terminalbench!


Qwen 3.8 Max is here and it beats Fable 5.
86.6 on TerminalBench vs Fable 5 at 84.6.
GPT 5.6 still holds the top at 88.8, so it is not a clean sweep.
But at $2/$6 per million tokens, the value is absurd.
The real headline: open weights next week. 2.4T Max going open, plus a 27B model that runs on a laptop.
Frontier intelligence, downloadable, in seven days.
Anthropic and OpenAI should be nervous.
Show more


GPT-5.6 is finally coming.
GPT-5.6 Sol beats Claude Mythos 5 on TerminalBench.
And on Cerebras, GPT-5.6 Sol can reach up to 750 tokens per second. Pretty fast for a model of this size. Now I just hope it can be rolled out to everyone.
Show more


GLM-5.3 looking pretty competitive vs GPT 5.6 Sol & Luna on the TerminalBench-3.0 pareto:
> GPT 5.6 Sol: 35% for $54 per task
> GLM-5.3: 32% for $24 per task
> GPT 5.6 Luna: 14% for $21.5 per task
Show more


Looks like my numbers were better because I used Codex and AA used mini-swe-agent (think pi but shit)
Might have to do my own runs of TerminalBench 4.0 on official harnesses because the difference is insane.
Show more

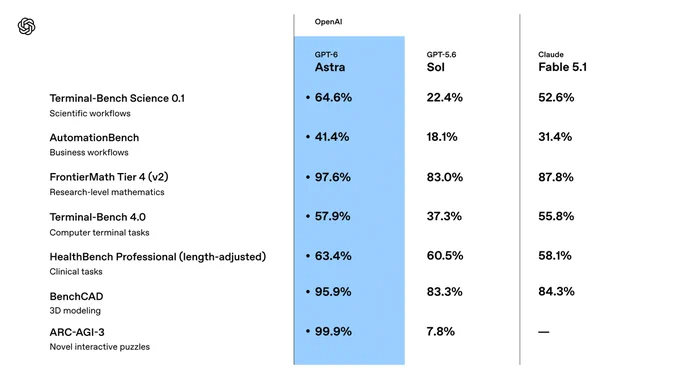
GPT-6 Astra is state-of-the-art on FrontierMath Tier 4, ARC-AGI 3, and TerminalBench-4.0.
GPT‑6 Astra is also a major advance for scientific discovery, with state-of-the-art performance on Terminal-Bench Science 0.1 and HealthBench Pro.
Show more
One thing that has been on my mind a lot lately as I continue to build out eval suites, is the time given to each task in the suite, and how that scales with difficulty.
I think TerminalBench does a pretty good job with this, here's a look at how they do it (image below).
As you can see from the table below, most of the tasks in their eval suite, need to be completed by the model in two hours or less.
But there are some tasks, that are more difficult, that are given 4, 5, and even one task with 8 hours.
Thinking about following a similar pattern for my next eval suite, but a little scared at what my costs would be on an all effort sweep at 8 hours, so might not go that high.
For anyone else building eval suites, curious how you think about agent time to completion budget?
Show more


We benchmarked the GitHub Copilot agentic harness against the harnesses that ship leading models natively.
Holding the model and task fixed across SWE-bench Verified, SWE-bench Pro, SkillsBench, TerminalBench, and Win-Hill, the results were clear:
• Task resolution on par with model-vendor harnesses
• Fewer tokens across most configurations
A key learning: With GitHub Copilot supporting more than 20 models, you're free to pick efficiency or peak quality per task.
Explore the data.
Show more
