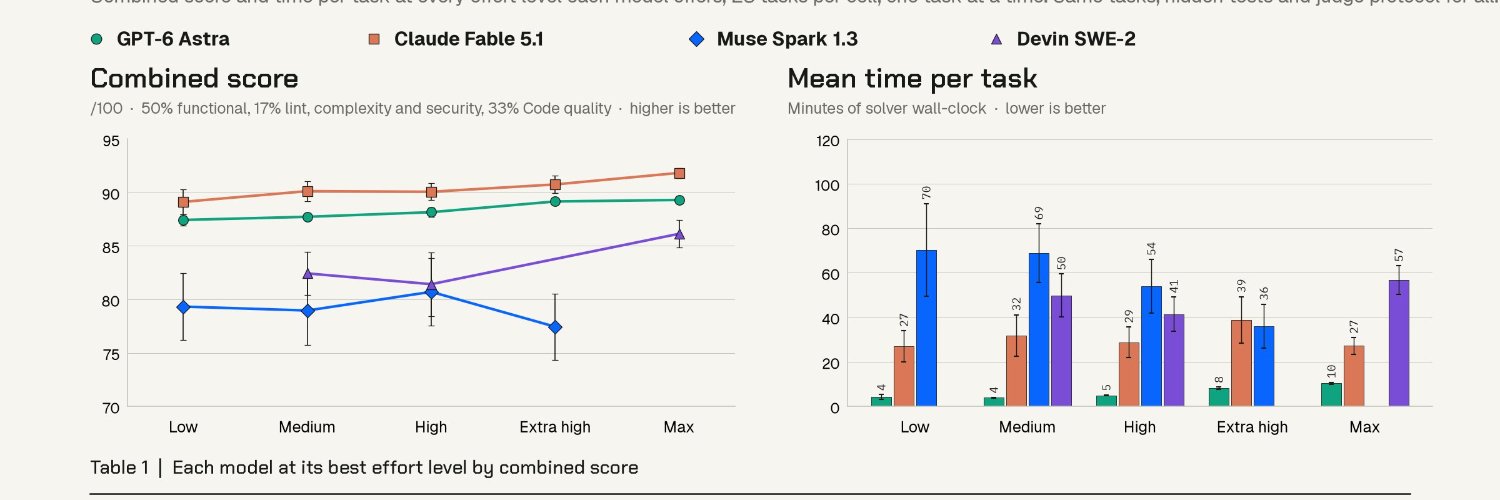

Okay well I finished my Devin SWE-2 results with @VulcanBench today, so figured I would share them now since I'm already spinning up benchmarks of all the new stuff both OpenAI and Anthropic released today.
It's a busy time to be a benchmarker. And an expensive time to be an independent benchmarker 😅
Overall Devin SWE-2 is a pretty impressive model for the cost, which is $0 right now so pretty hard to beat.
It came in noticeably more accurate than Muse Spark 1.3 and only a few points behind Astra and Fable. So while I might not use it for my hardest of hard tasks, for normal routine tasks I think it's very likely that Devin SWE-2 is more than powerful enough.
Still hard to beat Astra when it comes to speed, it is noticeably faster than Fable, Muse, and Devin. Both Devin and Muse take longer than Fable, they can think a lot on my Frontier v4 suite, which is designed to give them quite a challenge.
I will be running all of these on my new Routine v1 suite which will be pretty interesting as I don't think Muse or Devin are really designed to throw your hardest tasks at, so it will be interesting to see how they do on more routine tasks that Astra and Fable, and now Opus 5.5, are all likely overkill for.
More to come, as always, live long and benchmark 🖖
Show more


Phew, it’s one heck of a beautiful Monday here. Never gets old that this is home 🏡

Very interesting, just got an update from my agent running a judging sweep.
I think the Cursor name could be going away 👀
(which just to share my opinion, I'm fine with, makes sense to have it under one brand, new era imo)
Show more

Huge congrats to the whole team at @SpaceXAI, amazing results on the Intelligence Index for 4.7 🔥
Coding performance ahead of Sol now 👀

Grok 4.7 scores 46 on the Artificial Analysis Intelligence Index to bring SpaceXAI into the top 4 AI labs. Coding Agent Index performance has also improved, overtaking GPT-5.6 Sol
Grok 4.7 scores +2 points over Grok 4.6 on the Intelligence Index, with strong performance on agentic knowledge work tasks. We evaluated the new model at xhigh reasoning effort.
Congratulations to @SpaceXAI and @ElonMusk on the release!
Key takeaways:
➤ Grok 4.7 joins the frontier of agentic knowledge work: Grok 4.7 gains +111 Elo over Grok 4.6 (high) on AA-Briefcase, our private benchmark for long-horizon agentic knowledge work, scoring 1657 Elo and placing it alongside Claude Opus 5 and Claude Fable 5.1 at the frontier. On GDPval-AA, it scores 1695 Elo, +90 ahead of Grok 4.6 (high).
➤ A leap in coding agent performance: Grok 4.7 (xhigh) with Grok Build scores 56 on the Artificial Analysis Coding Agent Index, up +9 points from Grok 4.6 (xhigh). Among models in their native harnesses, Grok 4.7 + Grok Build now ranks 4th, behind only Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5.
➤ Incremental performance changes elsewhere: Outside of agentic knowledge work, Grok 4.7 broadly matches Grok 4.6 (high) on the other Intelligence Index tasks. It improves on Terminal-Bench 4.0 (+4.5 percentage points) and GDP.pdf (+3.0 p.p.), with regressions on AA-LCR (-3.7 p.p.) and AutomationBench-AA (-1.1 p.p.).
➤ High token use across tasks: Grok 4.7's gains come with higher token usage. Grok 4.7 (xhigh) uses approximately 81k output tokens per Intelligence Index task, compared with 36k for Grok 4.6 (high) and 27k for GPT-6 Astra (max) - 125% and 196% more, respectively.
Other model details:
➤ Context window of 500k tokens, unchanged from Grok 4.6
➤ Pricing of $2/$6 per 1M input/output tokens with cache hits discounted to $0.50 per 1M tokens, matching Grok 4.6
➤ Configurable reasoning effort spans low to xhigh. Our evaluation uses xhigh.
Show more

Jev might be one of the biggest unlocks for model routing

People use Jev to pick a model before a task.
I made it change GPT-6's reasoning effort inside Codex DURING the task.
More thinking when stuck. Less for routine steps.
50% lower Astra costs in my tests. Faster runs, without breaking prompt caching.
Show more

Whoa, Grok 4.7 xHigh beat Fable 5.1 Max in the DeepSWE 1.1 benchmark 😮
Super excited to benchmark with @VulcanBench across all effort levels 🖖

Grok 4.7 is here.
It's a notable improvement over Grok 4.6 at the same price and speed.

Okay, finally finished my Muse Spark 1.3 benchmark.
This ended up being the longest-running benchmark I've ever done at @VulcanBench and it definitely looks like Muse has some serious issues at lower effort levels.
I was able to run Astra through my v4 eval suite across every effort level in ~12 hours, Muse Spark had single tasks at low effort levels that hit the 10 hour mark, on just a single task. It took a total of two weeks for me to run the entire benchmark.
Overall my assessment is that Muse is a promising model, but they'll have to figure out why it has issues at lower effort levels, looking at the traces, it's just thinking, thinking, and thinking some more, while models like Astra and Fable just got it done.
Astra continues to be the most token efficient of these three, and I continue to feel very good about Astra Light, both token efficient and accurate. Using Muse Spark 1.3 at lower effort levels is a complete non-starter imo because you'll be waiting 10 hours for something Astra light can do in 10 minutes.
Model cards below, adding to the site soon:
Show more


I think a lot about model routing, heck I even write a Substack just it, so yeah, I'm kinda obsessed.
At a high level, I don't think most of the model routers out there make much sense for anyone but enterprise co's already paying api pricing to use services like Anthropic and OpenAI.
And I think this is honestly, the target market for most of the companies releasing model routers today. So it makes sense, and yes, will definitely save enterprises money.
If you're spending $500,000/year on a Claude Sub. And everyone is just using Opus High for everything, yup, putting some thought into model selection, even at API+ pricing, which is what most routers charge, is still a savings.
But if you're using a subscription, at $100 or $200/mo, switching to a model router will dramatically increase what you pay, because you're not paying API pricing, you're paying a massively discounted price.
This doesn't mean the model routing co's are doing anything wrong, they're just not solving a problem for you, they're solving a problem that big enterprise co's have.
I've seen so many posts, and talked to so many people at big co's that say, it's all too overwhelming for them and their teams, so they tend to just see everyone using one model, usually the latest frontier model, and at High effort for everytihng.
What will be interesting to see is over time will these companies just decide to outsource this decision logic to third party model routers, or will they use benchmark data, both public, and internal evals, to just give their teams some model routing decisions, i.e. use these three models, at these effort levels, etc.
I think the biggest, unexplored territory right now is effort level. This is why I started @VulcanBench because I saw just about every benchmark just running evals with models at Max effort, and I knew for myself and my team, we used Medium effort more than any other effort level.
But a model that does great at Max, might not be great at Medium, and another model might be better. And it could be completely different for Python code than Rust code, and medium-sized codebases vs. large.
These days, I wake up every morning so excited to be doing research in this area. There is so much to discover.
And that's my Monday brain dump, big week ahead, TGIM 🖖
Show more
Great breakdown on choosing primitives in Jev.
also, save this image... It’s probably the simplest way to understand which Jev primitive fits your use case
Think about what you want to build, follow the diagram, and that’s it
Show more

Okay, bought more parts to connect my new 3090 to my existing gaming pc.
As I said, I’ll share every step of the journey.
Yesterday I shared the power supply I ordered.
Just ordered these two today.
Show more

Using Jev for model routing might just be the killer use case.

Jev is an incredible model router.
Ask Jev which models can solve a user’s task, and route it to the cheapest one.
We have a new frontier model overnight.

While my agents build new eval suites and benchmark SWE-3, I’ll be here

Interesting analysis, hearing non-stop reports at this point of ppl saying their Codex usage is going down way faster than before.
I am not experiencing this myself, but I also use most models on Low and Medium effort, so I might not be a great example.
Show more

Since the Codex reset yesterday, I already depleted the weekly limits of one of my Codex accounts.
This account exlusively uses GPT-5.6 Sol. I'm tracking all token consumption through my OpenClaw setup, so it's very easy to compare to previous periods.
Limits are now exhausting 4.8-5.9x faster than they did just 2 months ago while consumption is now around ~18% slower.
Same reasoning efforts, same mixed type of work.
The token rug pull is coming.
Get ready to pay up.
Show more
One thing I’ve learned about myself is that for my work environment, I need to look out at either trees or mountains with trees.
Two total no-go’s for me are working with a view of a city/buildings, or working inside just looking at other people working. Coffee shops are my nightmare work environment for many reasons, this being one.
There are a few different places I work from in our house, here’s one, and the view.
My soul needs the trees 🧘♂️ 🌲
Show more


You're probably using Astra wrong.
Highly recommend reading this post from Anshu that is worth reading before you prompt again.

I had Astra analyze all my Codex threads and learned a lot about quota. Here's how to get the most Astra usage. (applicable to Fable too)
I've spent ~$5000 on Astra since release*:
- 70% is JUST cached input reads
- 16% is uncached input
- 13% is output
- <1% is cache writes
Till now, my Codex threads kept getting longer and longer, but Astra broke the trend (see chart).
Long context is eating most of your quota. The biggest levers:
- Smaller threads. New thread for each little task. Don't let context build up
- Use smaller models that delegate coding tasks to Astra subagents. Don't let Astra see big outer thread
- Avoid continuous polling. Have Astra set timers and wake back up for long-running tasks
- Trim tokens wherever you can: skills/MCPs, AGENTS.md, custom instructions, etc
- 3rd party tools like RTK that return more compact outputs might help (haven't tested this yet)
Investigating that 70% input cost in more detail:
- 40% is encrypted content (reasoning or other OpenAI stuff)
- 20% is file reads
- 10% is tool call arguments, schemas, etc
- 7% is skills (catalog, loading instructions, output)
- 5% is base instructions (system prompt, custom instructions, AGENTS.md)
- 5% is browser/computer use input
- 3% is command/tool output
- The rest is minor or not actionable: compaction handoffs, assistant prose, user messages
What you can do:
- Use the lowest reasoning you can for your task, to cut CoT tokens
- Make your repo as agent-friendly as possible. Small files/modules with clear folder structure, so Astra isn't grepping and reading large chunks. Try asking Astra to delegate file search tasks to subagents like Luna
- Don't dump in tons of skills, instructions, AGENTS.md stuff; be intentional about it
- Delegate browser/computer use to smaller models unless you need max performance
And, probably goes without saying:
- Don't use /goal with Astra. The few times I did absolutely obliterated my quota
- /fast mode basically only if Tibo says he's resetting in an hour and you have 100% quota to burn
Let me know if you have any observations to share!
*I didn't literally drop $5k, this is mapping token to equivalent API prices
Show more

I am adding Jev to @AlbatrossCoding, and it could be a really interesting way to make my harness a lot more token efficient.
Instead of just adding Jev as a model provider, I'm going to have essentially what I guess I'll call "Jev Mode" that allows you to leverage what a model like this is actually good at, i.e. making decisions.
Right now, we waste a lot of time with agents having them perform lots of tool calls. I think Jev could essentially short circuit this in a way.
The logic I'm adding will add a step where your prompt goes to Jev first. If it's a question with predefined answers, Jev can just answer it. Otherwise, it goes to an LLM, which can answer or use tools.
I can benchmark this against a traditional harness to see what kind of performance gains it gets, my thought it is could be a lot faster and more token efficient for some tasks.
Will share more once it's ready, but I'm also very open to changing my design here so please poke holes in it if you see a way I could improve.
Hoping to make Albatross one of the first harnesses with Jev Inside™ 🪽
Diagram below of the flow I'm building out:
Show more

Thanks for all the great feedback. Everyone told me I should pick higher wattage, and a lot of reccos to stick with Corsair, so I did.
Here’s what I ended up buying:

So here’s the power supply I’m thinking of getting for my 3090, anyone from the local ai world want to help give this a thumbs up or thumbs down?
Seems like more than enough power and solid reviews.
Show more

Just in case anyone thought I was abandoning Diablo for WoW, not to worry, still giving Diablo the love it deserves.
But I have played more WoW today than Diablo 👀
And yes, I’m re-specing a Spiritborn rn with a Quill Volley Build. Shared in the second image for anyone interested.
Show more


So here’s the power supply I’m thinking of getting for my 3090, anyone from the local ai world want to help give this a thumbs up or thumbs down?
Seems like more than enough power and solid reviews.
Show more












