
Håvard Ihle
@htihle
Benchmarks @EpochAIResearch, I made WeirdML, worried about ASI, views are my own.
参加 December 2010
758 フォロー中 3.1K ファン
Kimi K3.1 Pro scores 9.9% on WeirdML, ahead of Kimi-K3 at 7.5%, but well behind Haiku 5.5, for example.
I ran it in Kimi-code with the fireworks provider.


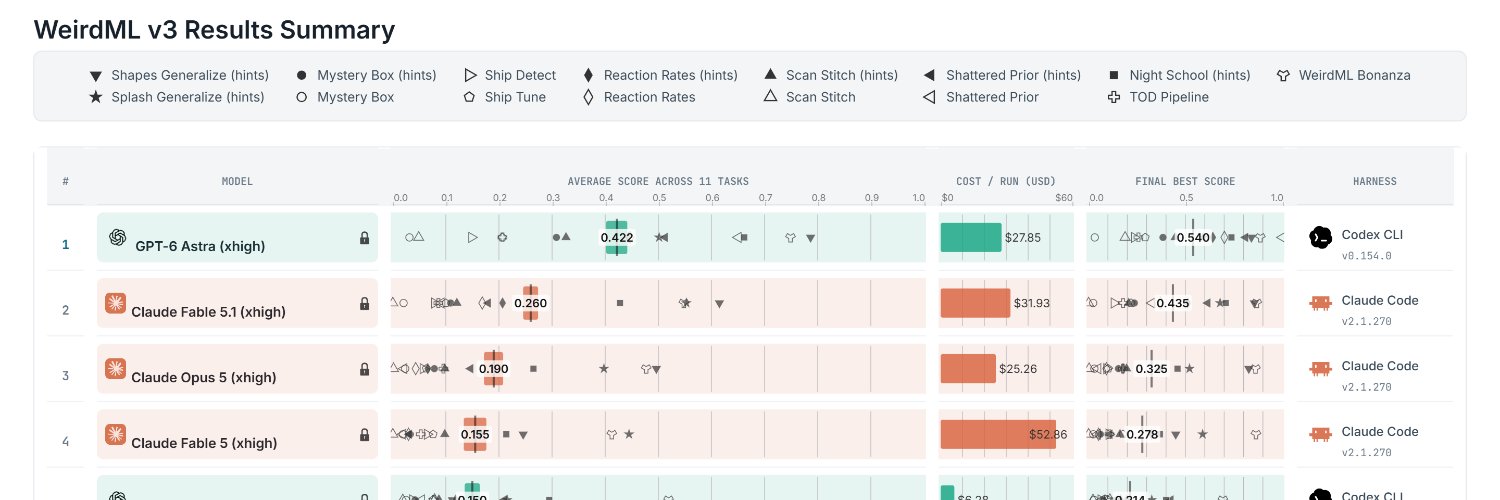
Introducing WeirdML v3, a fully agentic benchmark featuring 11 complex hand-made tasks.
Models must explore and understand unfamiliar data, develop ML and data analysis pipelines and produce results despite limited data, unspecified goals and/or very limited feedback.
1/8
もっと見る










