
Prof. Anima Anandkumar
@AnimaAnandkumar
AI+Science, Co-Founder @accelerated_u, Bren Professor @caltech, Time100, Fmr Sr Director of #AI# research @nvidia Fmr Principal Scientist @awscloud
가입 May 2021
2.5K 팔로잉 중 46.2K 팬
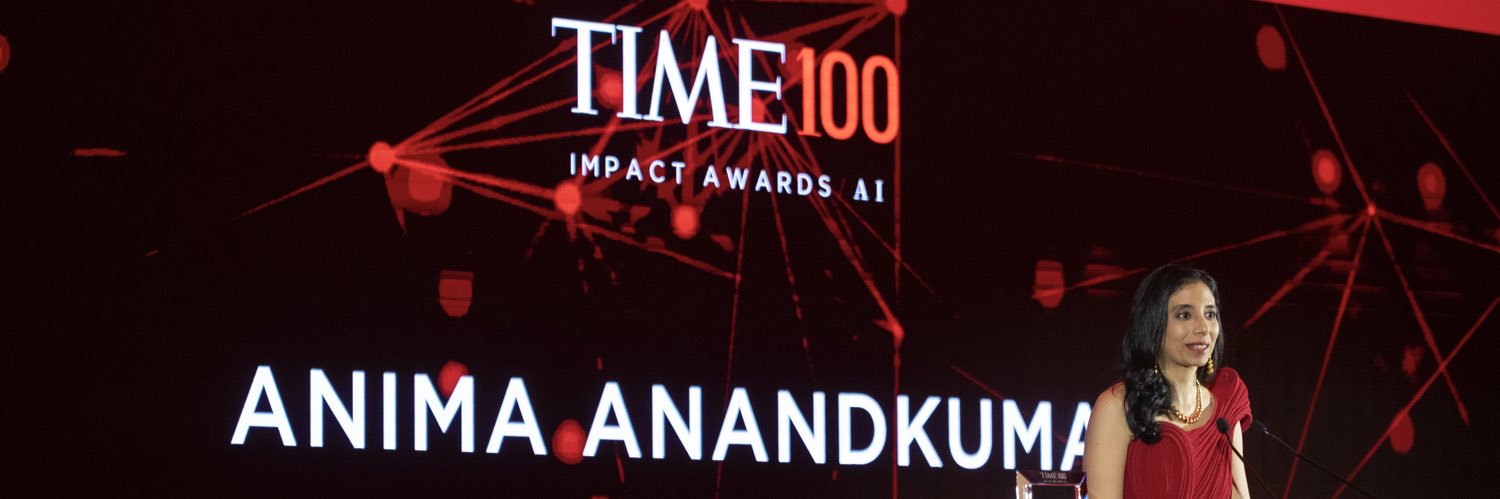
Honored to be named one of the 100 most influential people in AI by @TIME right on the heels of the public launch of our company Accelerated Understanding @accelerated_u
Bringing the power of AI+Science together has been the focus of my life for the past decade. I believe the greatest impact AI can have on science and engineering is its ability to massively accelerate simulation and understanding of the physical world.
We started this journey with the invention of Neural Operators at @Caltech to have a powerful foundation for AI modeling physical phenomena at multiple scales. Together with my team at @nvidia and support from @JensenHuang himself we built FourCastNet, the first high-resolution AI-weather model that is tens of thousands of times faster than existing systems.
Following up on this success we have applied Neural Operators to accelerating simulation of nuclear fusion to detect disruptions before they happen in the real world. Just this week, we announced how Neural Operators can enable density functional theory simulation in quantum chemistry quasi-linear time. We have also used Neural Operators to invent better medical devices like a catheter that reduces bacterial contamination by 100x and we have been able to design better masks for chips and optimized gate layouts for quantum dots.
More recently we have been asking ourselves what would happen if we aggressively scale our models and put multiple areas of physics in the same model, teaching it physics in full 4D (3D space + time). This requires massive scale and that is exactly what we have been able to do at Accelerated Understanding. We have pre-trained models up to 1 Trillion parameters, and we are able to train at 4D context lengths of up to 1 Trillion and run inference at 5 Trillion context.
I am particularly excited about self-improvement: a limiting factor for scaling physical AI so far has been the availability of high quality training data. As the old saying goes: your model is only as good as your data. But that no longer holds true: for our models we have the laws of physics themselves that let us measure and improve the quality of our outputs exceeding what was present in the training data.
But the improvement loop doesn’t stop at the models themselves. We can also use our models and their ability to understand physics and give directional feedback to break down one of the biggest barriers to innovation: the reliance on lab experiments as a bottleneck in the improvement loop.
As intelligence gets more abundant this bottleneck is only increasing in importance. Putting our models and their physical simulation capabilities in that loop instead and taking advantage of their directional feedback means we only need the lab all the way in the end to double check.
Excited to see new inventions and discoveries this will unlock! #TIME100AI#
더 보기







