Alvaro Cintas
@dr_cintas
Educating about AI, Cybersecurity and Technology | Professor | PhD in Computer Science & Engineering
가입 July 2019
195 팔로잉 중 132.7K 팬
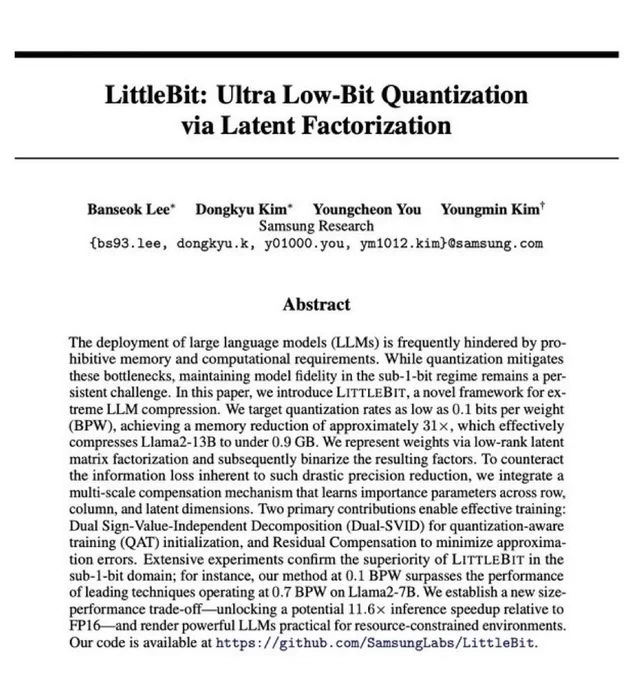
Samsung open-sourced a method that shrinks 13B parameter LLM into less than 1 GB.
The method is named "LittleBit"
Normally, AI weights are stored as regular numbers. LittleBit instead uses latent factorization to compress them below 1 bit each.
Some setups get all the way down to 0.1 bits per weight.
The architecture is where it gets wild.
Once a model is compressed this far, most of the math goes away.
LittleBit doesn't make the hardware grind through expensive floating-point multiplications. It runs the core computation with a simple bitwise XOR.
Heavy matrix math becomes simple sign flips.
What this means for deploying models:
• Up to 11.6x faster inference than standard FP16 models.
• Much less memory needed, and much less bandwidth to load the model.
• Holds up even below 0.5 bits, where older compression methods completely break down.
This is more than a smart optimization.
It's a roadmap for running huge, advanced AI locally on cheap, low-power hardware.
더 보기