Search results for DistributedSystems
DistributedSystems community
One keyword maps to one global community path.
People
Not Found
Tweets including DistributedSystems

When a service fails and everyone upstream retries at once, a small outage can balloon into a stack-wide incident. Here's how Uber tamed that "retry storm" problem.
Title: How Uber Protects Against Retry Storms
URL:
To stop retry storms — where traffic amplifies exponentially as every upstream service retries simultaneously against a degraded downstream — Uber built a system that distinguishes who actually owns an error.
Highlights
🔍 Only the error-owning service claims the error
A service "claims" an error only when its downstream call succeeded but it still returned an error itself; if the downstream is at fault, it "unclaims" instead. Only the actual owner of the problem retries.
🔁 Retry budgets and propagation cap further amplification
Retry budgets cap retries at each hop to a fixed percentage, turning exponential growth into multiplicative growth. When a retry fails, the "unclaimed" status propagates upstream to prevent further amplification higher in the chain.
📊 Stopped 9.5 million requests during a real outage
In a November 18, 2025 incident, traffic to a degraded service would have jumped 46–135% without this system. Instead, it blocked 9.5 million spurious requests plus up to 200,000 more from immediate callers, and cut the max retry-storm radius across all user-facing APIs from 25 hops to 3.
What stands out is how this runs as automatic, shared infrastructure with no per-service tuning needed — that's exactly what makes it practical at Uber's scale.
#ReliabilityEngineering# #DistributedSystems#
Show more


“Bitcoin was the first distributed systems paper I read with an economic layer built into it — and that changed everything.”
@kenzi_mori catches up with @averyching, Co-Founder & CTO of @Aptos, to trace his journey from high-performance computing and supercomputers, to scaling data infrastructure at Meta, to discovering Bitcoin and realizing that crypto was distributed systems with incentives natively embedded — the insight that ultimately led him to co-found Aptos Labs.
Show more


Building AI is a huge distributed systems challenge.
To post-train NVIDIA Nemotron, we bring data generation, inference, reinforcement learning, and evaluation into one loop across CPUs and GPUs.
I’ll be speaking about how we do this using Ray during the Ray Summit. August 26 at 9:50 AM PT.
👉
Show more


Pierre Computer Company is hiring for a Distributed Systems Engineer and Infrastructure Engineer. Come work with us on Code Storage, open source primitives, and other dope shit.
Show more

From scaling supercomputers to scaling Facebook to scaling Aptos.
One thread runs through them: making distributed systems work at massive scale—the backbone of today's AI systems.
@AptosLabs' @AveryChing with @theindexshow's @afkehaya
Show more

Sometimes I really wish there was a global clock I could manipulate so that I can test expiration behavior on distributed systems I do not control.

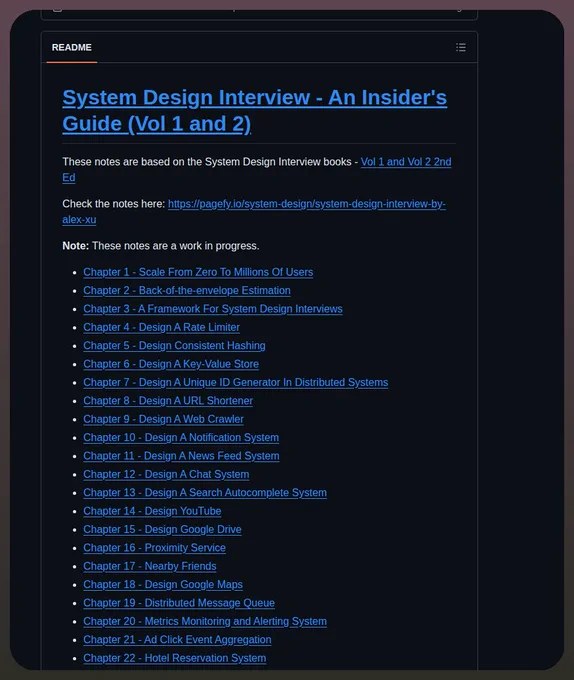
Breaks down system design interviews into 28 chapters on scaling, rate limiting, and distributed systems.

One thing MCP work has hammered home for me:
“The server is healthy” tells you surprisingly little.
Server can be up. Auth can work. API can return the right version. And the AI can STILL be operating from an old tool definition.
Distributed systems were apparently not complicated enough, so now the AI can have an outdated copy of what the server can do😂
Show more

Sometimes the things I do / say sound so ambitious and far-fetched enough that it's hard to believe we can even do it.
And then we do it. again and again.
In the AI and information age, truly anything can be done.
You can just go out and learn distributed systems, post training, inference engineering, databases, find the people, have a mission and build whatever you want to build.
It's all about operational excellence now, which is a skill I'm trying to learn
i dont know why most companies stop at B2B AI SaaS when there's so much to build.
Show more

Great article from @googledevs on Stateless MCP. Sessions were a big bottleneck, which is way x402 has chosen the stateless route.
Maintaining session state across distributed systems introduces coordination overhead that scales linearly with concurrency.
Payment authorization is per-request state. A protocol that needs a session has bound settlement to connection lifetime.
TLDR, the best way to do a 402 payment protocol is not with sessions.
Show more
