

Niklas
@niklaslenz_ai
I run local AI at home on 4 DGX Sparks, 1 M5U 256GB, 1 RTX 5090, 2 RTX 5060 Ti 16GB, and rank what runs best on the machine you own. LLMs, image/video gen. etc
187 Following 1.7K Followers
256 GB class: DeepSeek-V4.1-Flash-1017 on 2 DGX Sparks built a voxel world in 59.7 minutes.
@MiaAI_lab's 2-Spark recipe and EXL3 quant, TensorFold engine by @ashxhart, model by @deepseek_ai.
Build test: the model works as an agent. One prompt, one try, no help.
Browser check: 8/10
Tokens written: 131,268
Speed benchmark: 67 tok/s decode (separate run, thinking off)
Agent settings: top-p 0.95, as in Mia's recipe.
Answer limit: raised to the model card's 262,144 tokens, the recipe's server default is lower.
My test gate sent a keepalive every 30 s so the connection stayed open.
Open: 47 of 400 MMLU-Pro answers ran past our short answer limit and count as wrong.
Open: 61 of 198 GPQA answers did the same.
Open: memory tested up to 128K, speed there not measured.
Really good. Almost as good as the 4-Spark world.
Play the world in your browser. Every number, the exact command and the raw output:
Show more

THANK YOU!
Today, October 18, I passed 1,000 followers while I was asleep. Right now I'm at 1,575. I'm lost for words.
20 days ago, on September 28, I had 65 followers. That was the day I bought @MiaAI_lab's book "From Zero to Seen". I never would have thought how much would change in my life from that moment on. Sounds corny, but it's true.
I joined X in June. In August I started looking into local AI, and that's where I came across Mia and @0xSero. Back then I had a 5090 and two 5060 Tis from playing around with image and video generation. That was pretty much all of my local AI experience. Once I saw what was possible, I started buying more hardware. Being able to work from anywhere had become more important to me, and building a social media presence goes hand in hand with that. X turned out to be the place for both. From then on, local AI and X was my focus.
Since then, four Sparks and a Mac Studio M5 Ultra have joined the 5090 and the two 5060 Tis.
Today I'm opening what I've been building in the background:
The idea is simple. I take the recipes the open source community shares and test them on my hardware.
I want to bring together everyone who runs AI locally, whatever their background and whatever their budget. From a 500 euro 16 GB GPU to a 25,000 dollar Spark setup. LLMs, text to speech, image generation, video generation. One community, all in one place. So far 70 setups are tested, from 16 GB to 512 GB.
Fair warning, the site and my testing methods are not nearly where I want them to be yet. I didn't expect this to happen so fast, and I'm working hard to bring both up to date. The newest recipes aren't on the site yet. I spent the last days building the website and couldn't get to my Sparks, but I'm catching up on them now. I did test quality, but my own tests didn't give meaningful results. So for now the quality scores on the site come from Artificial Analysis. Speed is my own measurement.
From now on I want every model to run through benchmarks and tests that come from the community. For that I need your feedback. Drop your ideas for benchmarks and testing methods in the comments, I'd be really grateful. Rigmark is one I keep hearing about, and it's definitely on the list.
If you have recipes for your models and want them listed, just drop me a line and I'll take a look. Time and compute are my bottleneck right now, so I'll start with the models I see the most interest in here on X. If I miss something you care about, message me.
Even better, send me your recipe 12 to 24 hours before you publish it. That way I can test it and have the results on the site right when you go live. I'll publish it as an independent test, so your recipe gets verified on a second system. A win for both of us.
Thank you to the people who made X a good place for me and got me to spend more time here 🙏🏻 @MiaAI_lab @ashxhart @0xSero @LLMJunky @StefanMaier @cryptosibbers @TechMDAI @jayleaton @volatilemarkts @sudoingX
Show more

Thanks for the shout-out, @ashxhart! Seeing my name in the 1.0.3 notes, and Mia's shout-out on top, really keeps the motivation up :D
The 1.0.3 release binary has no kernels for the RTX 5090. Building from source with one flag fixes it: -Dsm=120, no patch.
Same card, same day, Nemotron 3.5 Lightning, llama.cpp with MTP → TensorFold 1.0.3:
Code: 458 → 731 tok/s (1.6×)
Prose: 354 → 506 tok/s (1.4×)
• TensorFold's drafted output matches plain byte for byte, 10 of 10. llama.cpp with MTP changes tokens.
• vs 1.0.2: +8% code, +11% prose.
• One RTX 5090, Linux, 450 W. Ash's bench_openai.py, greedy, 256 tokens, median of 3 rounds.
• Different quants: MLX 4-bit vs GGUF Q4_K_M, quality not compared. llama.cpp MTP not tuned.
Build:
zig build -Dsm=120 -Doptimize=fast fatbins install
zig build -Dsm=120 -Doptimize=fast native
Show more


TensorFold 1.0.3 lands with a few cool things.
- Living Weights (beta with Nemotron on Metal) and coming to CUDA in 1.0.4
- Nvidia Ampere (beta) for Nemotron, and native Qwen3.8-27B with DFlash2
- Conversation prefix caching
- Various bugs fixed and improvements
Twelve contributor PRs helped make this happen, so a massive thank you to @niklaslenz_ai and GitHub contributors akol1, jschmied, chaog992, AdrianBinDC and BobClawblaw, and everyone testing, reporting bugs and helping us improve TensorFold.
FYI, Living Weights is in very early beta and has sharp edges, but I think I’m on to something.
I’d love community feedback to make it better:
@plotarmordev @petruspennanen @MiaAI_lab @volatilemarkts
Show more


Run GLM 5.3 Flash EXL3 with TensorFold ⚡️
Now on 4x DGX Sparks, switchless or not!
For now, TP4 is on its own branch, so please make sure you use the correct branch!
- Around 6M KV cache.
- Decode on prose 95 tok/s, single stream
- Decode on prose 163 tok/s, 4 streams
- Decode on prose 222 tok/s, 8 streams
- Prefill ~2500 tok/s across the board.
These numbers were measured on a switchless setup!
The recipe works both with or without a switch, each has it's own startup script.
Links below 👇
Show more

Thanks for merging, @MiaAI_lab!
A few details for anyone trying it:
• It's opt-in. One line in .env: DRAFT=dflash2. With DRAFT unset, nothing changes.
• One request, end to end: 155 → 199 tok/s.
• The lead shrinks with context. From ~64k it is level with MTP on the same engine (exllamav3 1.6.0), slightly behind at 248k.
• Quality held: MMLU 80.0 → 79.5%, GSM8K 96 → 96%.
• One RTX 5090, Linux, 4.0 bpw, thinking off, median of 5 runs. The Windows path is built but not run yet.
Will try to get something working on my 5060 16GB as well.
Show more

Rejoice once again Nvidia 16 GB+ users! 🔥
Qwen3.8 27B should now runs even faster, thanks to an awesome PR from @niklaslenz_ai!
exllamav3 has been upgraded to 1.6.0, and the MTP head changed to a DFlash2 draft model.
In the RTX 5090, here're the speed improvements:
Prose: 103 to 113 tok/s
Code: 180 to 275 tok/s
Structured: 206 to 366 tok/s
You should notice speeds improvements on RTX 3090, 4090, and 5070 Ti, but I don't have official numbers, so pls test it and report!
Show more
Ten months ago I started buying hardware to run AI at home.
I paid €20,992. Buying it all new today: €30,992 (+47.6%).
And the same boxes now run stronger models much faster.
What happened, and why I don't think prices come down:
Show more
I've been building something new for TensorFold.
It's not just another quant. It’s a quantization framework designed around how TensorFold actually runs models.
I'm calling it Engine-Aware Quantization, or EAQ.
First target: GLM 5.3 Flash.
Early results vs my current public quant on the same TensorFold version, measured against the original BF16 model:
- 41% lower error on what the model actually writes
- 54% lower error on the decisions that matter for agents: when to call a tool, which one, when to stop
- roughly the same speed.
Built for coding, agentic work and tool calling.
This isn't a one-off: the framework is meant to carry over to every model and quant I will build in the future.
Still validating on real tool-calling and agent benchmarks before anything goes public.
More details coming soon.
Show more


Tonight we brought @ashxhart's Living Weights to GLM-5.3.
Living Weights lets a running model learn facts straight into its own weights. Ash shipped it in TensorFold 1.0.3 for Nemotron. We ported it to GLM.. (Lets be honest, we are "me and my coding agent")
Full GLM-5.3 (753B), split across four M3 Ultra Mac Studios, learned a fact in about 24 seconds and answered from it, including a phrasing it was never taught. Its 270K-token warm context was never touched.
GLM-5.3-Flash (320B) learns on a single Mac. We taught it "I like blue." Asked "what's my favorite color?", it answered "You like blue."
Two PRs are up for Ash's consideration:
#574# GLM-5.3-Flash
#575# full GLM-5.3
Thinking-mode recall is the next frontier. But it's a working starting point, proven on real hardware. Excited to see what the community builds with it.
And most of all, thank you, @ashxhart . A selfless open-source prodigy. You could have sold this to any lab on earth, and you gave it to all of us instead. Everything above stands on your work.
We're donating $300 to Ash and the TensorFold Foundation. I don't tell anyone what to do with their money, but to me this is an investment. I hope others see what I see in him.
PS: This is getting exciting.. Open Source is winning!
Show more

TensorFold is changing local AI as we know it 🔥
Models that learn and keep what they learn in their own weights, running locally.
And it's only getting better from here.
TensorFold 1.0.3 lands with a few cool things.
- Living Weights (beta with Nemotron on Metal) and coming to CUDA in 1.0.4
- Nvidia Ampere (beta) for Nemotron, and native Qwen3.8-27B with DFlash2
- Conversation prefix caching
- Various bugs fixed and improvements
Twelve contributor PRs helped make this happen, so a massive thank you to @niklaslenz_ai and GitHub contributors akol1, jschmied, chaog992, AdrianBinDC and BobClawblaw, and everyone testing, reporting bugs and helping us improve TensorFold.
FYI, Living Weights is in very early beta and has sharp edges, but I think I’m on to something.
I’d love community feedback to make it better:
@plotarmordev @petruspennanen @MiaAI_lab @volatilemarkts
Show more

What model is everyone running?
Every open model ships frozen.
What if it could learn and update its own weights as it's being used?
I have been working on a bit of engineering called Living Weights for about three months, and I think it's time to release it.
The model becomes uniquely yours, no KV stashing, no MD files, no trickery.... just live learning. 😎
Unload the model, move it to another machine, and it still knows what you told it. Could this be the start of recursive self improvement for local AI?
It drops in the latest TensorFold release today, with support for @NVIDIAAI Nemotron Lightning. 🤯👀
@abheer @sundeep @NaderLikeLadder
Special thanks to @volatilemarkts for the name.
Show more

That would be awesome.
Cursor, X, Grok, Grokbot.
That's way to complicated.

DON'T cancel your X premium or Supergrok
Tomorrow is a very important day for every X user
X is building XPass, one subscription for X, Grok, Cursor and Grok Bot
The tiers:
> Premium $8: X Premium, Grok Lite, Grok API, Cursor
> Plus $30: Premium+, SuperGrok, Grok Bot, Cursor cloud agents, Bugbot
> Super $100: SuperGrok+, 1080p videos, priority access
> Ultra $200: SuperGrok Heavy, fastest replies, earliest access
One shared usage pool across everything
Annual prices: $6.67 / $25 / $83.33 / $166.7 month
In other words, the first two options are your X subscription plus additional bonuses, while the rest are the same but with higher limits and boost your X profile
Rumor has it that it will be launched tomorrow
Show more


Preview on the DGX-Spark tensorfold studio
;:::: stay tuned::::: needs only One Dgx-spark


GLM-5.3-Flash on one DGX Spark at 33 tok/s. Plus CYBER-FROST at 55 tok/s on code.
Two impressive community one-box recipes from this week. I re-ran both with the authors' own benchmark method. Both hold up.
RED-SNOW 5.3 Flash, 2.49 bpw:
• long outputs (1000+ tokens): 32.95 tok/s median. README says 34.4.
• prose: 25.4 tok/s. README says ~24.
• MTP acceptance 89.5%.
CYBER-FROST 3.8, 3.87 bpw, with the repo's own bench script:
• code: 54.7 tok/s. DEPLOY.md says 53.2.
• devops: 49.0 tok/s. DEPLOY.md says 45.8.
• prose: 46.9 tok/s. DEPLOY.md says 46.5.
So both land within 7% of what the repos say.
Honest limits:
• My box runs with a 2200 MHz clock cap. That can cost a few percent against an uncapped box.
• Engine pins differ too: I ran exllamav3 fork 24f0dec + TabbyAPI main; the repo and yume ran 047ce72 + TabbyAPI 7a524a9. Part of the gap below may come from that.
• @yume_arasaki got 60.7 tok/s on the code suite. I got 54.7, best single sample 60.6.
• 2.49 bpw is a tight squeeze: the card reports 90% top-1 agreement with BF16.
• 3 runs each. Both are de-refused security finetunes (RED-SNOW is an abliterated GLM-5.3-Flash).
Recipes @WescheNex1q + @ViC305, finetunes @Blackfrost_AI.
Show more

Nemotron 3.5 Lightning (30B-A3B) fits on a single 16 GB card. I ran it on my RTX 5060 Ti, every layer on the GPU.
ggml-org's model GGUFs start at 17.6 GiB, unsloth's at 18.1 GiB. Myric's APEX-mini is 13.66 GiB and keeps the MTP head in the same file. Stock llama.cpp (b11151), no patch.
Speed = 400 tokens ÷ full request time, temp 0, median of 3. Thinking was on (default), so the tokens are reasoning, not final prose or code.
MTP drafts help one request, not 4 at once (same prompt):
Solo prose: 129.6 → 152.9 tok/s
Solo code: 127.2 → 190.9 tok/s
4x prose: 277.6 → 235.9 tok/s total
4x code: 307.9 → 277.5 tok/s total
Peak VRAM: 13.0 GiB, 14.4 GiB with MTP. GSM8K, 100 problems, thinking off: 92/100, none cut off. Thinking on: 91/100, 2 still thinking at 129k tokens.
Limits: GSM8K is my only quality check, no full-precision run (Myric: +11.7% perplexity vs BF16). Speed and VRAM at 2k context per request. MTP and 4 at once change the exact output.
Show more

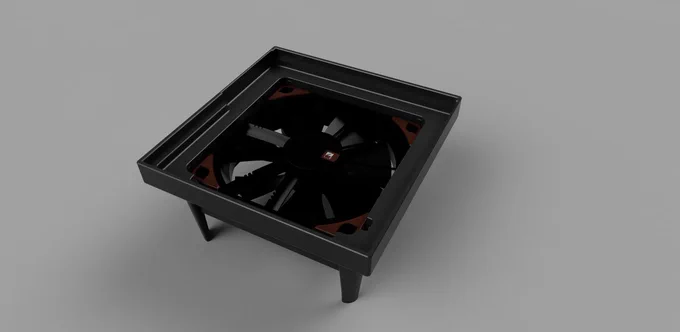
Might let Opus design something a little bit smaller for the rack..

For all the DGX Spark owners who are interested in a cooling solution: 3D printable "forced induction" fan shroud for the sparks. This allows for a 120mm Noctua PPC 3000rpm fan to force air through the intake of the unit, drastically increasing airflow through the internal heatsinks.
Asus GX10s ran cooler by ~19°C under heavy load.
Nvidia DGX Spark ran cooler by ~10°C under heavy load.
This eliminates the overheating issue, as long as you don't mind the fan noise.
3D files are on my repo
Show more



RT @MiaAI_lab: StepFun 5 Preview is now officially LIVE 🔥🔥
I've worked with the model for the last couple of days, and it feels and ACTS l…

And Grok @Bot only gets better from here 🚀 🚀
You could build an entire company made of Grok Bots!

Sol Ultrafast is only available on $500 subs.
Meanwhile we have ultrafast at home with TensorFold and other optimizations being worked on 😂 @MiaAI_lab @ashxhart

Ultrafast is rolling out today for GPT-6.1 Sol in the API, Codex, and ChatGPT Work.
Near-Astra intelligence at up to 8x faster speeds than Sol Standard, so you can build as fast as the ideas come.
Show more












