
Mathematica
@mathemetica
Math isn't escape. It's the map through the madness.
加入 October 2024
204 正在关注 76.5K 粉丝
Every useful model begins by measuring how far its guess sits from reality.
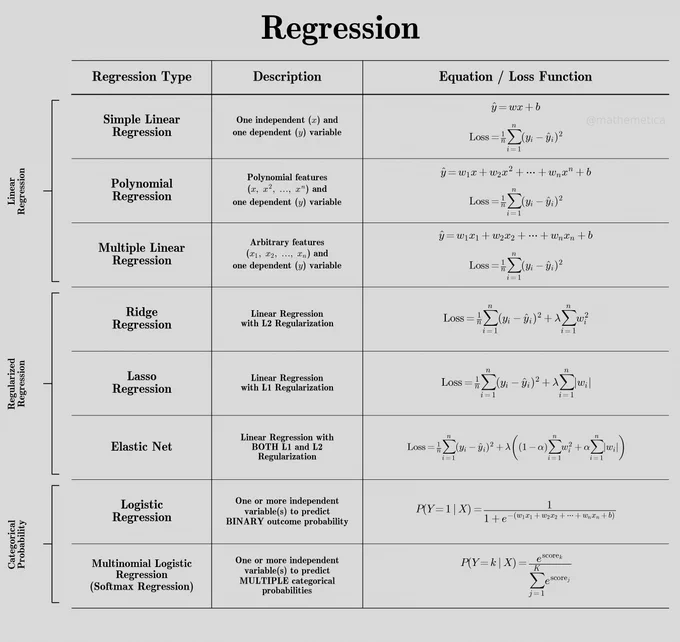
Simple linear regression draws the straight line ŷ = wx + b and shrinks the average squared gap (1/n) ∑ (y_i − ŷ_i)². Polynomial and multiple versions keep the same loss while letting the features curve or multiply, so one equation still captures richer structure.
Ridge, Lasso, and Elastic Net add penalties on the weights—λ ∑ w_i², λ ∑ |w_i|, or a blend—so the fit stays honest outside the training points. Logistic and softmax then convert the linear score into probabilities, mapping continuous inputs onto binary or multi-class chances.
Regression is the disciplined act of turning error into a usable pattern.
显示更多