Search results for SpeculativeDecoding
SpeculativeDecoding community
One keyword maps to one global community path.
People
Not Found
Tweets including SpeculativeDecoding

⚡ DSpark vs DFlash: Up to 2.55× Throughput in a vLLM Test
With DSpark checkpoints and vLLM support now available, parallel speculative decoding is becoming a practical serving option rather than just a research idea.
Zhihu contributor kaiyuan explains how DFlash and DSpark work, then benchmarks both on the same Qwen3-4B target model.
The result: DSpark reached 2.45–2.55× baseline throughput, while DFlash achieved 1.96–2.09×.
1️⃣ Why LLM Decoding Is Naturally Slow
Autoregressive models generate text one token at a time.
Token n+1 cannot be produced before token n. This sequential dependency limits how much parallel GPU compute can be used during decoding.
Non-autoregressive generation works differently. It treats generation more like filling multiple blanks and can predict several positions in one forward pass.
Parallel speculative decoding combines both ideas:
🔹 A lightweight draft model proposes several tokens in parallel.
🔹 The target model verifies them in one batch.
🔹 Accepted tokens are kept; generation restarts from the first rejection.
The challenge is making the draft both fast and accurate enough to be useful.
2️⃣ Why Traditional Draft Models Hit a Wall
Conventional speculative decoding often uses a smaller autoregressive model such as EAGLE.
It produces higher-quality drafts, but still generates candidate tokens sequentially.
Longer drafts require more draft-model forward passes. Making the draft model larger improves accuracy but also increases latency.
Parallel drafters solve the latency problem by proposing an entire token block at once.
However, later tokens in that block do not fully depend on earlier predictions. Their accuracy often drops quickly, creating suffix acceptance decay.
3️⃣ How DFlash Improves Parallel Drafting
DFlash uses a parallel, fill-in-the-blanks-style draft model.
To improve draft quality, it extracts hidden states from several layers of the target model and fuses them into an additional context representation.
Each draft layer then attends to two sources:
🔹 Context derived from the target model
🔹 Representations from the draft tokens themselves
The target model’s hidden states make the lightweight drafter more informed without requiring multiple autoregressive passes.
DFlash can therefore propose a long block in one forward pass.
But longer blocks still create a problem: the suffix is more likely to be rejected, while the target model must spend compute verifying it.
4️⃣ DSpark Adds Sequential Structure
DSpark extends DFlash with semi-autoregressive generation.
It first uses a parallel backbone to generate intermediate logits for multiple positions. A lightweight sequential module, implemented with an RNN or Markov head, then produces the draft tokens from left to right.
This small sequential step restores dependencies inside the block without giving up most of the parallel speed.
It also predicts a confidence value for every token: the probability that the token will survive target-model verification if the previous prefix is accepted.
The result is a stronger draft with less suffix decay.
5️⃣ Verification Length Becomes Dynamic
DSpark does not automatically send the entire draft to the target model.
Its Hardware-Aware Prefix Scheduler considers:
🔹 The survival probability of each draft prefix
🔹 The current batch size and system load
🔹 A profiled steps-per-second curve for the hardware
Verifying one more token may increase the expected accepted length. But it also enlarges the verification batch and can reduce processing speed.
The scheduler expands each prefix only while estimated throughput continues improving. Low-confidence suffix tokens are discarded before they consume target-model compute.
Draft long, but verify only the prefix that is still worth verifying.
6️⃣ The vLLM Test Setup
The author tested both methods under the same environment:
🔹 8× NVIDIA A800-SXM4-80GB
🔹 Qwen3-4B target model
🔹 DSpark block-7 and DFlash block-16 draft models
🔹 vLLM 0.26.0
The initial comparison used DSpark with four speculative tokens and DFlash with seven.
On 250 GSM8K questions:
✅ DSpark: 35.2% accuracy, 0.75s average latency
✅ DFlash: 31.6% accuracy, 0.84s average latency
On 250 MMLU questions:
✅ DSpark: 28.8% accuracy, 0.24s average latency
✅ DFlash: 27.6% accuracy, 0.27s average latency
DSpark reduced average latency by roughly 11% in both tests.
7️⃣ Throughput Is the Stronger Result
Because the two methods used different speculative-token settings, the author swapped those parameters and tested again.
🔹 Original settings: DSpark=7, DFlash=4
DSpark reached 584 tok/s, while DFlash reached 449 tok/s.
✅ DSpark was 1.30× faster.
🔹 Swapped settings: DSpark=4, DFlash=7
DSpark reached 561 tok/s, while DFlash reached 480 tok/s.
✅ DSpark remained 1.17× faster.
Changing num_speculative_tokens affected throughput by less than 7%.
DSpark remained faster in both configurations, showing that its advantage did not come from receiving a more favorable draft length.
Compared with the 229 tok/s baseline:
🔹 DSpark delivered 2.45–2.55× throughput.
🔹 DFlash delivered 1.96–2.09× throughput.
At matched settings, DSpark stayed roughly 20% faster than DFlash.
⚠️ Do Not Overread the Accuracy Numbers
The accuracy differences are less conclusive.
MMLU results varied by about one percentage point. On GSM8K, even the baseline changed from 29.2% to 34.4% across two runs.
The author attributes this to different vLLM batch compositions changing floating-point accumulation order. That can alter a small number of token choices even with temperature=0.
So the test strongly supports a throughput advantage. It does not establish that speculative decoding improves model intelligence.
💡 The Practical Takeaway
DFlash proves that parallel drafting can generate many candidates cheaply.
DSpark adds the two components needed for production serving:
🔹 Lightweight sequential modeling to improve draft quality
🔹 Load-aware scheduling to avoid unnecessary verification
Its real contribution is not simply drafting more tokens. It is deciding which tokens are still worth verifying under the current serving load.
🔗 DeepSpec:
🔗 Test notebook:
🔗 Full Reading:
#DSpark# #DFlash# #SpeculativeDecoding# #vLLM# #LLMInference# #AIInfrastructure# #DeepSeek#
Show more


My talk about llama.cpp speculative decoding (MTP, dflash, dspark) at dotAI 🦙🦙 replay available soon!


🚀 @deepseek_ai's DSpark speculative decoding now runs natively in vLLM!
What it is: a semi-autoregressive drafter that proposes several tokens in parallel with non-causal sliding-window attention, then verifies them in a single pass. Output stays identical, decoding takes fewer steps.
How vLLM runs it: it reuses the existing SparseMLA backends instead of custom attention kernels, captures the full draft backbone and sampling loop in one CUDA graph, and works with prefix caching and FP8 KV cache.
Performance on DeepSeek-V4-Pro-DSpark (verified on NVIDIA 8×B300 GPUs):
- ~250 tokens/s at batch size 1
- average acceptance length ~5
- 12-42% higher acceptance than MTP across draft depths
Run with vLLM nightly today:
vllm serve deepseek-ai/DeepSeek-V4-Pro-DSpark -tp 8 --trust-remote-code --kv-cache-dtype fp8 --speculative-config '{"method":"dspark","num_speculative_tokens":7,"draft_sample_method":"greedy"}'
DSpark Core PR:
Thanks @deepseek_ai for open-sourcing DSpark, and to @NVIDIAAI and the vLLM community for landing it! 🙏
Show more


Today’s video is on DFlash 2 from Inco ai and speculative decoding!
I explain what DFlash is, how it speeds up local models, and then run an experiment with three versions of a local model, one with no speculative decoding, one with DFlash, and one with DFlash 2 to see the difference! Check it out!
@zhijianliu_
Tinkering with DFlash2: How to Speed Up Local AI Models
Show more

The vLLM blog is a very nice summary of the current status of speculative decoding methods (and has little info on AMD GPUs despite the title)


🚀 We’ve open-sourced AngelSpec, an end-to-end speculative decoding framework supporting both training and deployment.
On Hy3-A21B, DFly delivers a 1.98–2.40× end-to-end speedup over autoregressive decoding across tested concurrency levels from 4 to 64, with 10.5–11.8% higher throughput than DFlash.
Training code and Hy3-A21B MTP/DFly drafter weights are now available:
GitHub:
Paper:
Docs:
Hugging Face:
ModelScope:
#Hy3# #AngelSpec# #OpenSource#
Show more


Accelerate inference without escalating operational spend. By pairing compact draft models with primary LLMs, speculative decoding speeds up auto-regressive generation. Learn how Red Hat OpenShift AI and Kubeflow optimize model serving for lower latency and better compute ROI.
Show more


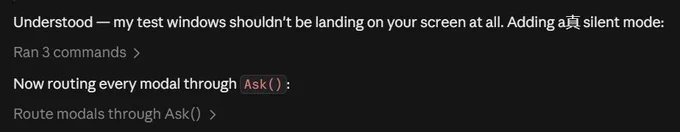
Well here's a 1 in 10000 output from my Claude Code. Apparently the character is used to signify 'genuine' and when I asked Claude about it, it said that it likely happened due to
(a) close proximity language embedding
(b) a low precision model
(c) speculative decoding.
Show more
For linear attention a typical implementation only caches the last hidden states, i.e. the context of last token. While for speculative decoding like MTP we need to rollback at least n_draft tokens' context, which does not work with linear attention's cache.
An intuitive solution is to remember at least n_draft hidden states in linear attention's cache, I experimented with a cache implementation (which is a bit frustrating to write) and I think the idea works well.
The really confusing thing is, no one seems to take this approach, i.e. making a general cache for linear attention that stores hidden states in temporal manner with fixed size, instead people wire MTP inside GDN with a checkpoint of the hidden states during the draft window. Surely it works, but isn't it the ugliest possible implementation and you would have to pollute code of every model that uses MTP?
I can see an answer is to avoid increased RAM usage, but is is really small keeping only n_draft context, and the intrusive changes to model implementation kill the elegant abstractions.
Show more

New blog! 🚀 MTP, EAGLE-3, DFlash or DSpark, which speculative decoding method should you actually use?
There’s no universal winner. The best choice changes with the model, workload, and speculation depth.
We break down how 5 methods work, how to enable and tune them in vLLM, and benchmark them across Gemma, Qwen, Kimi and MiniMax on @AMD Instinct MI300X & MI355X.
Deep dive 👇
Show more
