

Zhihu Frontier
@ZhihuFrontier
🚀Bringing China's AI & tech trends, voices and perspectives to the global stage.
⚡️Powered by 知乎/ China's leading knowledge community.
207 Following 12.7K Followers
153 website replicas and 3,518 tasks, all runnable offline and open-source. What stands out about WebHarbor is the focus on realistic workflows, including tasks behind logins, while giving researchers a stable setup to train agents and measure progress.
Show more

⚓ WebHarbor⚓ Introducing the largest open-source environment resources for GUI Web Agents!
🌐 153 real-world websites (Amazon, GitHub, Booking, YouTube, ...)
🎯 3,518 tasks, including complex multi-step and authenticated workflows
🤖 Built for reproducible evaluation and scalable RL training
We started with just 15 environments in May 2026. Today, thanks to 57 contributors from 26 institutions, we've scaled to 153 high-fidelity, image-rich environments—the largest open-source collection of its kind, to our knowledge! 🔥
And they're all executable, offline, and fully open-source!
👀 Explore the environments now:
Why did we build it, and how? 🧵👇 Threads 1/5
Show more


Great to see this open-sourced! The harness matters in robotics, too. This Tsinghua–Berkeley work, co-authored by @pabbeel, lifts the same Qwen model’s RoboDojo score from 1.90 to 31.39 without privileged inputs. A compelling case for better tools and feedback in robot agents.
Show more

‼️ Can Qwen directly control the robot as well as GPT-6 Astra?
🚀 Introducing uni-robot-agent: a unified harness for Robot-Use Agents (RUAs), a first step toward RUA training and local deployment.
We tested uni-robot-agent with Qwen3.8-Flash-Next running locally:
1️⃣ On RoboDojo, its score rose from 1.90 to 31.39, surpassing the RoboDojo Team’s score with GPT-6 Astra.
2️⃣ On real-world tasks, it outscored fine-tuned π0.5 by 5.75 points and zero-shot Dream-1 by 10 points.
🧵 [1/7]
Show more

DeepSeek Opens DeepInfer: Inside V4.1 Flash’s Production Inference System
@deepseek_ai just published an engineering deep dive on Zhihu, announcing DeepInfer, the open-source framework behind its large-scale V4.1 Flash service, with support for NVIDIA and Huawei Ascend hardware.
DeepSeek reports 155 trillion tokens/day in service throughput from a single cluster. Its production statistics include a 96% input cache hit rate, average time to first token of 400 ms, and generation speeds of 230 tokens/s, reaching 300 tokens/s for coding.
The engineering details explain how those numbers fit together.
Separate the stages, then balance the actual work
Vision encoding, prefill and decode run separately so resources can scale with each stage’s workload. The system targets standard eight-accelerator servers for prefill and 64–128-accelerator supernodes for decode, where wide expert parallelism improves batching efficiency.
Prefill scheduling uses an estimated attention-compute cost to allocate work and size chunks within a time budget. Decode routing balances both request count and total KV-cache length. Popular MoE experts receive replicas that are periodically redistributed to reduce waiting between devices.
Keep reusable prefixes for days
Persistent block KV cache lives in a separate 3FS storage cluster with roughly 100 PiB of SSD capacity. Reported retention reaches three days for agent traffic and seven days for chatbot traffic.
Any prefill worker can retrieve any cached prefix, avoiding a conflict between cache affinity and load balancing. Storage and compute can also scale independently. Cache loading is asynchronous, with host-to-device transfers designed to overlap layer execution.
Rebuild short-lived attention state cheaply
Sliding-window attention state has a different lifecycle: it is reused within active sessions, so DeepSeek keeps it in host memory rather than persistent storage.
When that state is missing, SWA Bounded Replay reconstructs an approximation from just the latest 128 tokens, restricting attention to the replay segment while reusing the persistent block cache.
Applied to the decoder, this avoids expensive state reconstruction across a much longer token span. DeepSeek says it nearly halves total prefill computation.
Spend verification compute where it pays off
DSpark predicts draft-token acceptance probabilities and varies verification lengths according to expected throughput. DeepSeek reports a 6% production throughput gain over always verifying five draft tokens.
CPU scheduling also overlaps GPU execution to remove idle gaps between decode steps.
Release the API layer alongside the engine
The accompanying deepseek-recipe library handles Chat Completions, Responses and Messages APIs. It parallelizes tokenization and distinguishes actual control tokens from identical-looking user text, preventing that text from being interpreted as structural instructions.
One release boundary matters: the KV-cache management and load-balancing components are not yet fully open-sourced, because they remain closely coupled to DeepSeek’s internal infrastructure.
Show more


A mathematical figure can render perfectly and still be mathematically wrong.
@SoTALab_AI’s new MathVis benchmark shows that frontier models still struggle to turn advanced math into correct diagrams, with the strongest reaching just 31.25% Pass@1. A revealing look at the gap between generating a figure and reasoning through one.
Show more

DeepSeek’s Weak Spots Can Hide Behind Average Scores
Move the same information a few tokens, and retrieval accuracy can change sharply. In ByteDance Seed’s tests, DeepSeek-V4-Flash-Base showed a 40.2-percentage-point gap between its best and worst positions.
Zhihu contributor Kitt在进化 explains why this is a reliability problem that average scores can miss.
Why position changes what survives
DeepSeek V4 alternates between two attention designs:
CSA compresses overlapping 8-token windows at a stride of 4, then selects relevant compressed entries through an indexer.
HCA compresses each non-overlapping block of 128 tokens into one entry, then attends to all historical compressed entries.
Shifting information changes where it falls within these compression windows, affecting how well it is preserved and retrieved.
The researchers tested retrieval from 16,000 key-value pairs in a 128K-token context. They varied alignment with compression windows while keeping the question’s position fixed and matching the target-position distributions’ mean and variance.
Similar averages, very different weak spots
In a controlled experiment using the Qwen3-0.6B architecture, full attention and 8× compressed attention achieved similar average retrieval scores: 61.1 versus 59.4, both with eight KV heads.
But their best-to-worst gaps were 4.3 versus 71.1 points. Comparable averages concealed dramatically different sensitivity to position.
V4.1 improves, but the explanation remains tentative
The gap narrowed from 40.2 points in V4-Flash-Base to 19.1 in post-trained V4-Flash-0731, and to 6.1 in V4.1-Flash.
The author suggests two possible contributors: Engram reducing the burden on attention, and CSA2 lowering the compression ratio to 2. These are hypotheses about the improvement, not experimentally isolated causes.
Show more


A polished render is not the same as a usable 3D project.
@SoTALab_AI’s Blend3DForge captures the full Blender workflow—from briefs and tool calls to failures, revisions, QA, and editable delivery—as trainable, traceable data.
A compelling look at why 3D agents must learn the process, not just the output. Worth a read.
Show more
We’re live! Join Shuo Yang (@Andy_ShuoYang) to see how FreeToken runs a 35B MoE model on a laptop with just 8GB of VRAM—and turns consumer hardware into an elastic inference platform.
If you’re into local AI, MoE inference, or AI systems, come check it out! ⬇️
Show more
FreeToken: Running a 35B MoE Model on Just 8GB of VRAM | Shuo Yang
How can a laptop GPU with just 8GB of VRAM run a 35B MoE model at interactive speed?
Join Shuo Yang (@Andy_ShuoYang), lead developer of FreeToken, for a deep dive into its edge-native MoE serving architecture, bandwidth-adaptive CPU–GPU execution, dynamic expert placement, and runtime memory management, hosted by @qingke_ai and simulcast on Zhihu Frontier.
📅 Oct 11 · 11 AM Beijing / 3 AM UTC
📺 Watch live:
Show more
Rewarding Visual Grounding: Fine-Grained Rubrics for Multimodal RL | Shulin Tian
How can fine-grained, rubric-based rewards keep multimodal reasoning grounded in what the model actually sees?
Join Shulin Tian (@shulin_tian) for a deep dive into reward design for multimodal reinforcement learning—and how it can make model reasoning more faithful to visual evidence, hosted by @qingke_ai and simulcast on Zhihu Frontier.
📅 Oct 8 · 8 PM Beijing / 12 PM UTC
📺Watch live:
Show more
After the release of Step 5 Preview, @StepFun_ai co-founder Yibo Zhu took a closer look at an idea the team has been exploring over the past few months: can training also benefit from “PD separation”?
He shared his answer on Zhihu: KV-Invariant Transformer Expansion for Efficient Agentic LLM Scaling—a firsthand technical deep dive into a potential new path for scaling agentic LLMs.
🔗
The core challenge is optimizing three things at once: model quality, training cost, and inference cost.
MoE is a classic example of this “three-way win.” But approaches such as Upcycling and YOCO often trade off one dimension against another: scaling them to recover model quality can increase training or inference costs.
KITE combines scaling with upcycling, while keeping KV computation invariant.
First, a smaller prefiller is trained to generate the KV cache. The model is then expanded with decoder-side components that reuse this KV and continue pretraining. Because these added components do not affect KV computation, the model can scale up to recover quality without proportionally increasing prefill cost.
This is particularly relevant in the Agent era, where long-context workloads can make prefill a major part of inference cost.
Using a simple Step Scale Transformer (SST), the paper demonstrates a three-way gain over a proportionally scaled classical Transformer baseline: better model quality, lower training cost, and lower inference cost.
KITE is ultimately a broader principle of KV-invariant scaling, rather than a single architecture. Better prefiller/decoder designs, KV usage strategies, and scaling laws remain open questions.
If agentic workloads continue to be prefill-heavy, KITE could offer an interesting path toward more efficient LLM scaling.
KITE has not yet been applied to Step 5, but similar ideas may eventually appear in StepFun’s mainline models.
#StepFun# #AI# #Tech# #Scaling# #KITE#
Show more


How Tencent Packed a 770B-Parameter Model into 214 GiB
Shrinking Hy4 preview's weights from roughly 1.5TB to 214 GiB is one challenge. Preserving useful capabilities and practical inference speed is another. How did @TencentHunyuan tackle both?
Zhihu contributor yghstill, a member of Tencent Hunyuan's quantization team, explains the engineering behind it. The parameter count remains 770B; the compression changes how those weights are represented.
Four weights, five bits
Sherry is the quantization algorithm, STQ1_0 the storage format, and MIX-STQ1_0 the mixed-precision allocation scheme.
Each group of four weights takes values from {-d, 0, +d}, with exactly one zero. Four zero positions multiplied by eight sign combinations gives 32 possible patterns, requiring five bits.
That is 1.25 bits per weight for the codes alone. Including a shared FP16 scale for every 256 weights brings STQ1_0 to 1.3125 bits per weight. The complete mixed-precision model averages about 2.38 bits per weight.
Allocate precision to specific weights, not whole layers
Hy4 preview has 77 MoE layers, each with 256 routed experts. The team concentrates aggressive compression on expert weights while selectively protecting other components.
For the experts' gate/up projections, MIX-STQ1_0 uses IQ2_XXS on 48 sensitive layers and STQ1_0 on 29 less sensitive layers.
The author reports that mixing lower and higher precision produces less error at the same average bit budget than uniformly choosing the intermediate IQ1_M format.
Layer sensitivity needs more than diagonal statistics
The author describes using the full Hessian, H = XXᵀ, to measure quantization sensitivity. Its off-diagonal terms capture correlations that diagonal-only imatrix scoring misses.
In the team's comparison, the two sensitivity rankings had a Spearman correlation of -0.115. The chosen layers did not follow a simple “deeper means more important” rule: precision was allocated greedily by error reduction per additional byte.
Fit the scale and choose the zero together
This is post-training quantization, without retraining. The encoder alternates between two decisions: fitting d with weighted least squares and choosing the zero position using imatrix-weighted error.
Zeroing the smallest-magnitude weight is not always the best choice. What matters is the additional weighted error introduced by making it zero.
Across 1,200 rows of real expert weights, three alternating rounds reduced weighted reconstruction error by roughly 90% compared with the original ternary encoder. This measures local weight reconstruction, not end-to-end model accuracy.
Compression must survive the runtime
The team implemented STQ1_0 CUDA kernels in a patched llama.cpp build. In its operator comparison, STQ1_0 ran roughly as fast as IQ1_M despite the lower bit width.
The author reports nearly unchanged MRCR retrieval performance and a small decline in math. Against UD-IQ1_M at a similar bit budget, the mixed-precision model led across the reported evaluations, including a gain of more than five points on MRCR.
The result comes from combining compact encoding, calibrated quantization, selective precision and usable inference kernels.
Show more


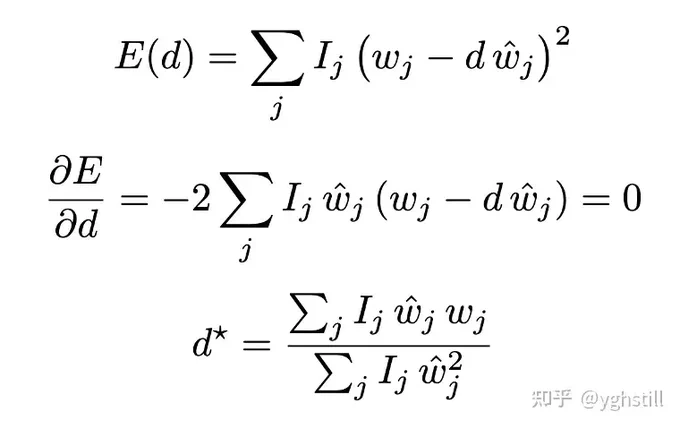

Beyond the Model: Training a 397B Agent with SkyRL | Charlie Ruan (阮世麟)
What does it take to make RL work at 397B scale—beyond training the model itself?
Join Charlie Ruan (@charlie_ruan) for a deep dive into SkyRL and the hard-won lessons of training a 397B office-work agent—from fixing environment and harness bugs to system tuning and the final hero run.
Hosted by @qingke_ai and simulcast on Zhihu Frontier.
📅 Sept 19 · 10 AM Beijing / 2 AM UTC
📺 Watch live:
Show more
📺 Xiaomi Is Livestreaming a Production RL Run — Burn Rate Included
@XiaomiMiMo is training its MiMo-V2.6 in public — not a demo, a live post-training dashboard where every step's reward, loss and benchmark movement is watchable in real time. One day in, the meter reads roughly $1.2M spent and 60B tokens consumed. As Zhihu contributor Kitt在进化 puts it: this isn't a training site, it's a money-burning site — about ¥4,000 a minute.
His bigger point: this is rare, valuable data. Almost nobody publishes what frontier-scale RL actually costs.
1️⃣ What the dashboard actually shows
Every training step exposes the internals most labs keep private. His reading guide:
🔹 Loss family: training loss, entropy (are answers diversifying or collapsing into one mode), gradient norm, and train/inference KL divergence.
🔹 Reward: a mix of test-case scoring and rubric-based reward.
🔹 dynsam (dynamic sampling): avg@n performance over repeated tries, plus pass-rate buckets — including samples never solved and always solved.
🔹 DeepSWE v1.1 as the headline probe (mini-swe-agent, avg@3): Pro at 63.7, Flash at 60.7 at the time of writing.
2️⃣ The cost ledger, out in the open
From the dashboard he extracts the numbers the industry usually guesses at:
🔹 MiMo-V2.6 Pro: roughly $36 per million tokens of training.
🔹 MiMo-V2.6 Flash: roughly $8 per million tokens.
🔹 His rule of thumb: equivalent inference runs 30-50x cheaper than these training figures.
3️⃣ What's actually being trained
The sample distribution is also public: about 1,500 prompts per step, ~70% of them coding tasks. The remaining third is split across general, visual, cybersecurity and chat tasks — which makes this, in effect, an agentic-coding-centric RL run with side dishes.
4️⃣ Why it's worth watching
He notes a university lab livestreamed a training run days earlier, but at nowhere near this scale or frontier relevance. For anyone who wants to learn how production RL behaves — rewards, entropy, dynamic sampling, benchmarks moving step by step — this is a rare open classroom.
His only complaint, half-joking: a livestream this good deserves a comment section.
🔗 Full Reading:
#Xiaomi# #MiMo# #ReinforcementLearning# #PostTraining# #LLM# #OpenScience# #AI#
Show more


🌱 Seed-2.1-Pro Review: Better Post-Training Can't Hide an Aging Base
@ByteDanceSeed_ Seed-2.1-Pro 0915 earns higher reasoning scores with fewer tokens, and its agent ability has climbed from nearly unusable to passable. But in the three months since the last version, rivals iterated roughly a generation and a half — and the old base model is running out of tricks.
That is the verdict from Zhihu contributor toyama nao, who runs a long-running monthly logic benchmark and put the 0915 build through his full evaluation suite.
1️⃣ Coding and agent work: from unusable to passable
The jump over the predecessor is large. Deliverable completeness now beats DeepSeek V4.1 Flash, though first-pass success still trails top-tier models — a model caught in the middle.
🔹 Frontend: some aesthetic sense, but unstable. Constrained stacks like iOS system components look decent; open stacks like web or raw canvas expose visible flaws in proportion and color.
🔹 Task adaptability: every task now at least completes. In a HarmonyOS-flavored project it barely knew, the model read docs and iterated its way to usable — a good sign.
🔹 Delivery efficiency: roughly tied with DeepSeek V4.1 Flash and GLM-5.3-Flash, splitting steps evenly between writing and verifying. All three sit below the current Chinese SOTA.
2️⃣ Multi-step reasoning: the biggest gain
This is where 0915 improved most — and where it leads its tier, with a small token-efficiency edge. On problems where GLM-5.3 falls into exhaustive enumeration, 0915 repeatedly finds higher-scoring answers with fewer tokens, showing what the author calls real "big-model intuition."
The caveat: multi-turn reasoning, which demands in-context learning and reflection, remains mediocre — on par with Chinese peers.
3️⃣ Where 0915 still stumbles
Hallucination runs high, and context confusion appears regardless of prompt length — especially when source details are tangled.
The agent symptom is subtler than dropping requirements: 0915 keeps every requirement but misreads semi-ambiguous ones — arguably the more dangerous failure mode.
4️⃣ The contrarian bet: a true non-thinking mode
Seed is one of the few teams still maintaining a genuinely non-thinking mode, and this version quietly got good: average output dropped from 8K tokens back to ~1K, with no measurable capability regression, a slight gain in complex reasoning, and readable prose intact.
For latency-sensitive scenarios that still need some reasoning, the author considers it a legitimate option.
5️⃣ The long march
His closing frames 0915 as a rest stop, not a destination: the predecessor's lukewarm market reception forced ByteDance's team into a forced march of biweekly iterations, and better post-training is now visibly paying off in cost per task.
But the base is old, and the competition has moved. His last line is worth keeping: sometimes the long way around is the real shortcut.
🔗 Full Reading:
🔗 Key links:
Author's monthly logic benchmark (Aug 2026):
#ByteDance# #Seed# #LLM# #AIAgents# #LLMBenchmark# #ReasoningModels# #AI#
Show more


The livestream is live now! If you're into LLM training, distillation, or RL / OPD, come check it out! ⬇️
Most “Self-Evolving AI” Is Not Recursive Self-Improvement Yet
AI may generate its own data, rewards, skills, and code. But if humans still define what counts as better and approve deployment, the loop is not closed.
Zhihu contributor 一口鸟 (@alsaceym) argues that RSI’s hardest bottleneck is reliable verification.
1️⃣ Moving humans out of the loop
RSI progresses through three stages:
🔹 Human in the loop: AI proposes changes; people approve them.
🔹 Human on the loop: data, rewards, and verifiers are automated; people supervise deployment.
🔹 Closed loop: the system generates, verifies, and applies improvements itself.
Most “self-evolving” systems remain in the second stage.
2️⃣ What actually improves?
Self-refine changes the current answer. Test-time training writes experience into weights.
Agent evolution modifies prompts, tools, memory, skills, workflows, or Agent code across tasks.
output → weights → the Agent itself
Training-time RSI follows another ladder:
🔹 Zero-label: AI generates supervision.
🔹 Zero-data: AI also generates problems and curricula.
🔹 Auto research: AI chooses hypotheses, training recipes, and experiments.
The system gradually takes over how to learn, what to learn, and finally how to improve learning itself.
3️⃣ Self-improvement can amplify mistakes
A generator and verifier may share the same biases. Wrong outputs can produce biased evaluations, biased learning signals, and stronger errors.
Even correct rewards do not guarantee stability: training can improve and later collapse.
Self-play may also lose diversity or favor problems that are easy to reward rather than genuinely useful.
Automation makes grounding more important, not less.
4️⃣ Verification is the real bottleneck
Math and code are RSI-friendly because proofs, unit tests, and execution feedback provide clear signals.
Open-ended Agent work is harder. A verifier must judge not only correctness, but novelty, usefulness, importance, and research taste.
The next step may be evolving the verifier itself. But if the policy and evaluator change together, what keeps both aligned with reality?
✅ The boundary of true RSI
The loop is expanding:
answer → experience → learning signal → problem and curriculum → verifier
True RSI requires improvement across every layer without losing contact with real objectives.
Until evolving verifiers remain reliable without constant human grounding, recursive self-improvement is still an aspiration rather than an achieved capability.
🔗 Full analysis:
#RecursiveSelfImprovement# #RSI# #SelfEvolvingAI# #AIAgents# #ReinforcementLearning# #AISafety#
Show more


DeepSeek V4.1 Gives Prefill and Decode Different Compute Paths
Prompt tokens mostly traverse 20 layers; generated tokens traverse all 40. This Causal Encoder-Decoder design nearly halves long-input prefill while preserving autoregressive generation.
Zhihu contributor 潜龙勿用, Changxin Ke(柯昌鑫), a graduate researcher at ICT, CAS, explains how its architecture and post-training were designed together.
1️⃣ A causal encoder, not T5
The 40-layer backbone is split into a 20-layer causal encoder and a 20-layer decoder. Both remain causal.
The encoder processes the prompt and supplies the decoder’s global KV. Most prompt tokens avoid the decoder stack, while generated tokens still run through all 40 layers.
That means 8B active parameters per prefill token versus 16B per decode token.
2️⃣ Most layers share global memory
CSA2 uses three modes: Full creates global KV and an index; Reindex shares the KV but selects new positions; Reuse shares both.
Only four layers create independent global KV, four reindex it, and 30 reuse both KV and the latest index. Each layer retains its own query and local SWA state.
The first Full layer builds up to 16,384 candidates. Later layers search this pool for their Top-512.
From 4K to 1M context, decode FLOPs per token rise only about 25%.
3️⃣ Serving approximations enter training
Exact reconstruction of decoder SWA states would replay 2,560 prompt tokens.
V4.1 replays only the final 128 encoder outputs and trains the model to tolerate the approximation.
With FP4 global KV, cache falls to 890 bytes per token, persistent cache to roughly one eighth of V4-Flash, and prefill compute close to half.
Bounded replay and constrained retrieval are not last-minute serving tricks. The model experiences them during post-training.
4️⃣ Post-training is an evolving Agent system
Each RL task combines a problem, environment, and verifier.
New trajectories can reveal shortcuts, broken environments, or verifier errors and send the task back for repair.
V4.1 trains across multiple harnesses, merges checkpoints between RL runs, and finishes with on-policy distillation from more than 40 teachers.
Raising reasoning effort from 25 to 100 increases output length about 2.5×, while average Pass@1 across eight benchmarks rises from 67.1% to 76.3%.
✅ The real design choice
V4.1 aligns model structure, cache policy, retrieval limits, training environments, and inference around long-running Agents.
The model learns under the same constraints the deployed system will actually impose.
🔗 Full analysis:
#DeepSeek# #DeepSeekV41# #LLMArchitecture# #AIAgents# #LongContext# #AIInfra#
Show more


📘 Introducing the Zhihu AI Cookbook (CN)
Saved dozens of AI articles but still not sure where to begin? We’ve organized some of Zhihu’s best technical discussions into clear, structured learning paths.
Over the past few years, Zhihu has become home to a wealth of in-depth AI writing from researchers, engineers and practitioners. The Zhihu AI Cookbook brings together some of the most useful and enduring pieces in one place.
The first edition brings together 80+ selected posts from 68 contributors across three tracks:
🖥️ AI Infra
🧠 Reinforcement Learning for LLMs
🤖 Embodied AI
It’s not another textbook. Think of it as a map connecting explainers, source-code walkthroughs, project retrospectives, interview insights and open-source tutorials.
🧭 How to use it:
1️⃣ Start with the introductory guide to understand the key concepts and prerequisites.
2️⃣ Choose the chapter that matches what you need right now.
3️⃣ Read each selection with a guiding question, then use the self-check prompts to test your understanding.
4️⃣ Follow the links to the original Zhihu posts for full derivations, implementation details and community discussions.
5️⃣ Put the ideas into practice with hands-on projects and open-source tutorials.
Whether you’re exploring a new research direction, working through a project or preparing for technical interviews, the Zhihu AI Cookbook can help you find the right place to start and build a more complete understanding.
🤝 With open-source tutorials contributed by our content partner, @datawhale2018.
🌏 This edition is currently available in Chinese. An English version is coming soon.
🚀This is only the first edition. More topics and learning paths are on the way…
🔗 Explore the Zhihu AI Cookbook (CN):
💻 View it on GitHub:
If you find it useful, give the repo a star and let us know what topic we should cover next. 🌟
#AI# #LLM# #EmbodiedAI# #AIInfrastructure# #ReinforcementLearning# #MachineLearning#
Show more

Rethinking OPD: One Query, Hundreds of Steps |Bingxiang He
Why can a single query keep improving a model for hundreds of training steps?
Join Bingxiang He (@HBX_hbx) for a deep dive into Rethinking OPD and One-Shot OPD, hosted by @qingke_ai and simulcast on Zhihu Frontier.
📅 Sept 17 · 8 PM Beijing / 12 PM UTC
📺 Watch live:
Show more










