

Tencent Hy
@TencentHunyuan
Tencent's foundation model for text, image, video, and 3D generation.
8 Following 53K Followers
live on GMI Cloud 🔥

Hy Image 3.5 preview is now live on GMI Cloud @TencentHunyuan
$0.024 per image
8.8x cheaper than GPT Image 2
5.6x cheaper than Nano Banana Pro
Create now 👇

🚀 Tencent Hy Translation just landed.Powered by Hy-MT2.
33 languages. 5 Chinese minority languages & dialects.
Voice. Photo. Full offline — on-device, no network required.
Already live in 12 countries and regions.
Travel, drive, work or read abroad. Accurate. Natural. Always available.
⏬ ⏬⏬
Show more

⚡️ As LLM reinforcement learning scales to larger GPU clusters and more training data, training efficiency becomes a first-order concern.
Our new research revisits classical critical-batch-size theory and extends it to online LLM RL, where the model generates its own training data and rollout generation and training scale differently.
Across GRPO and PPO, we find that learning-rate retuning can preserve learning per response over a bounded range of batch sizes.
On fixed hardware, scaling up the batch size improves PPO generation-stage throughput by up to 2.29×, while our best measured GRPO configuration reaches the same validation target in 29% less time. 🚀
Read the full research:
Show more

Tencent dropped Hy Image3.5 preview!
Great improvement and nice quality. Much better than HY Image 3.0 Instruct.
same approach: deep reasoning before editing/creating.
- doesn’t need detailed prompts
- follows instructions correctly
- solid composition understanding
Pushes old image restoration to a new level.
Yeah, results aren’t always perfect, but it doesn’t destroy faces or human features.
Show more

Free for two weeks!Hy Image3.5 preview is live on OnSolo. Short drama character sheets. Full-motion video game assets. Keyframes. Characters hold across every episode. Edits refine instead of restarting.
Show more

Hy Image3.5 preview is on OnSolo. Exclusive. 5 refs. 2K. 2 weeks Members free.

ComfyUI ✖️ Hy Image3.5 preview

Hy Image3.5 preview is now available in ComfyUI.
Professional-grade image generation, +30% win rate in human eval vs Hy Image3.0
→ Text to image and Image to image in one model, up to 2K
→ Multilingual text, symbols, and small print that render correctly
→ Cinematic, comic, commercial photography, and illustration styles
→ Identity and product features that hold through scene, outfit, and style changes
Show more

🎨 Hy Image3.5 preview is live in Miora. Edits that keep what already works — same canvas, your brand rules already remembered. Free for two weeks.

Hy Image3.5 preview is live on Miora. FREE through October 7.
Campaign visuals. Product scenes. Storyboards. Game concepts.
Up to 2K. Text-to-image and image-to-image.
Try it:
Show more

Share some genius cases generated by Hy Image3.5 preview. 😎


Hy Image3.5 preview is live. 🚀
Professional-grade image generation, +30% win rate in human eval vs Hy Image3.0
Both Text to image & Image to image available.
Up to 2K. Better Consistency.
API:
Priced for everyone. $0.024 per image on Tencent Cloud API.
We only charge for what we generate — your reference images are free.
Two weeks free (Only in OnSolo and Miora):
Miora
OnSolo
Try it and tell us where it breaks.
Show more

Sure you can edits images with this model.✔️

@TencentHunyuan just generation? can it do also edits?

Free for a limited time. Miora throws in a 2-week free trial.
→ open Miora in your browser
→ sign in with Google or GitHub
→ new project → Image Generator
→ pick Hy Image3.5 preview
→ every prompt starts with "Generate an image using Hy Image 3.5 preview:"
@TencentHunyuan @TencentAI_News
[MIORA LINK]
Show more
The AI says the site is done. Then the homepage errors, the buttons overlap, and it added a login flow you never asked for. 🙃
Introduces WebCraftBench: agents actually use the live app, coverage-guided exploration finds what never got reached, then we score aesthetics, usability, and whether the original request was met.
On 197 human-validated pairs, it matches human preference 85.3% of the time.
Paper:
Show more

Hy Image3.5 preview is live. 🚀
Professional-grade image generation, +30% win rate in human eval vs Hy Image3.0
Both Text to image & Image to image available.
Up to 2K. Better Consistency.
API:
Priced for everyone. $0.024 per image on Tencent Cloud API.
We only charge for what we generate — your reference images are free.
Two weeks free (Only in OnSolo and Miora):
Miora
OnSolo
Try it and tell us where it breaks.
Show more
Less size, same intelligence.

How Tencent Packed a 770B-Parameter Model into 214 GiB
Shrinking Hy4 preview's weights from roughly 1.5TB to 214 GiB is one challenge. Preserving useful capabilities and practical inference speed is another. How did @TencentHunyuan tackle both?
Zhihu contributor yghstill, a member of Tencent Hunyuan's quantization team, explains the engineering behind it. The parameter count remains 770B; the compression changes how those weights are represented.
Four weights, five bits
Sherry is the quantization algorithm, STQ1_0 the storage format, and MIX-STQ1_0 the mixed-precision allocation scheme.
Each group of four weights takes values from {-d, 0, +d}, with exactly one zero. Four zero positions multiplied by eight sign combinations gives 32 possible patterns, requiring five bits.
That is 1.25 bits per weight for the codes alone. Including a shared FP16 scale for every 256 weights brings STQ1_0 to 1.3125 bits per weight. The complete mixed-precision model averages about 2.38 bits per weight.
Allocate precision to specific weights, not whole layers
Hy4 preview has 77 MoE layers, each with 256 routed experts. The team concentrates aggressive compression on expert weights while selectively protecting other components.
For the experts' gate/up projections, MIX-STQ1_0 uses IQ2_XXS on 48 sensitive layers and STQ1_0 on 29 less sensitive layers.
The author reports that mixing lower and higher precision produces less error at the same average bit budget than uniformly choosing the intermediate IQ1_M format.
Layer sensitivity needs more than diagonal statistics
The author describes using the full Hessian, H = XXᵀ, to measure quantization sensitivity. Its off-diagonal terms capture correlations that diagonal-only imatrix scoring misses.
In the team's comparison, the two sensitivity rankings had a Spearman correlation of -0.115. The chosen layers did not follow a simple “deeper means more important” rule: precision was allocated greedily by error reduction per additional byte.
Fit the scale and choose the zero together
This is post-training quantization, without retraining. The encoder alternates between two decisions: fitting d with weighted least squares and choosing the zero position using imatrix-weighted error.
Zeroing the smallest-magnitude weight is not always the best choice. What matters is the additional weighted error introduced by making it zero.
Across 1,200 rows of real expert weights, three alternating rounds reduced weighted reconstruction error by roughly 90% compared with the original ternary encoder. This measures local weight reconstruction, not end-to-end model accuracy.
Compression must survive the runtime
The team implemented STQ1_0 CUDA kernels in a patched llama.cpp build. In its operator comparison, STQ1_0 ran roughly as fast as IQ1_M despite the lower bit width.
The author reports nearly unchanged MRCR retrieval performance and a small decline in math. Against UD-IQ1_M at a similar bit budget, the mixed-precision model led across the reported evaluations, including a gain of more than five points on MRCR.
The result comes from combining compact encoding, calibrated quantization, selective precision and usable inference kernels.
Show more


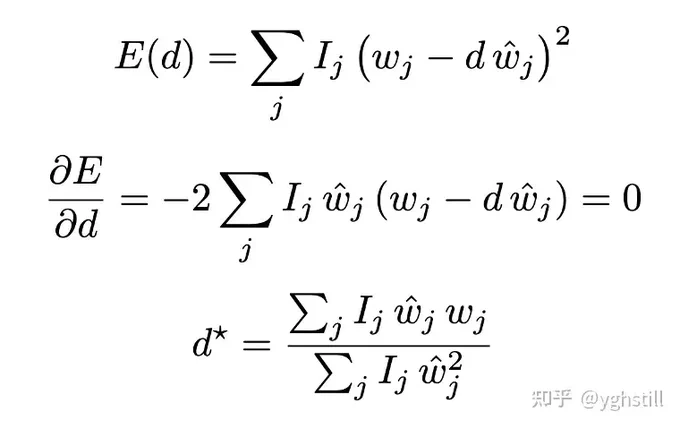

🚀 EvolveScaler is here.
Read a 40-day RPG log. Now answer one question: if you skip the mini-boss on Day 7, do you still beat the final boss?
The answer isn't in the log. You have to replay the world.
That's Information Evolution — records get retracted, corrected, backfilled. The world keeps changing after you read it.
So we build it backwards: define the world as an executable state machine, then render it into natural language. Code guarantees the logic. Language delivers the mess.
➡️ 117 prototypes. 159 question operators. 5 difficulty tiers. Up to ~1,200 events per sample.
➡️ 14 frontier models, hardest tier: median avg@5 falls to 11.3.
➡️ Train on it instead: +5.25 average across 8 out-of-distribution benchmarks.
Check out our paper and project page.
📚 Paper:
🏠 Project Page:
Show more


Much more AI coming ❤️

This morning I visited Tencent HQ in Beijing!
A marvelous office, from the architecture to the amazing showroom where I've really understood values and services offered by Tencent.
Thanks to the @TencentHunyuan team in Beijing for the amazing lunch talking about hybrid AI scenarios and more!
Hy4 Preview is just the tip of the iceberg, there is much more to come! @TencentAI_news Can't wait to see and try what you'll deliver in the near future 🚀
Show more


🚀 AuK is officially here. Nano banana🍌 for audio
An open-source foundation model for unified speech generation and editing.
Natural-language instructions + reference audio. One interface.
Zero-shot TTS. Instruction-controlled generation. Content editing. Whisper-conversion. De-accent. Timbre/style/emotion edit. Speed/Pitch control. Enhancement, denoising, multi-speaker and music separation.
Also releasing AuK-Flash: 4-step inference. ~4.5× faster under matched conditions.
Code, weights, and demo are live. Try it and share your feedback.
🤗 Paper & upvote:
⭐ GitHub & star:
Show more


Been testing @TencentHunyuan Hy4 preview in @WorkBuddyAI, and I came away pretty impressed with the document work. The game demos in the walkthrough were a lot of fun too.
770B parameters, 49B active, a 1M-token context window and Apache 2.0 weights. I wanted to see what that looks like in actual tasks.
The Mario-style platformer felt really good to play. Holding jump changed the height, mushrooms popped out of blocks, and enemy stomping worked. The movement and collisions were the bits I wanted it to get right, and the demo came together nicely.
The neon racer looked great, especially the wet-road lighting. Drifting into a boost widened the camera and kicked out blue-purple flames, while AI cars raced alongside. That was probably my favorite visual demo.
The expense audit impressed me for a different reason. It worked through 24 claims, checked policy versions and flagged duplicate invoices and allowance issues. I could follow the evidence behind its decisions, which made the output useful.
Even the research deck came out well: 10 slides, a comparison table, and numbers that matched my spot checks. I liked getting the research and presentation together.
Two prompts to try, shortened from the demos:
Mario: "Build a Mario-style platformer using HTML5 Canvas and vanilla JavaScript. No game engine. Use requestAnimationFrame, terrain and brick collisions, mushroom and coin blocks, enemy stomping, gravity, inertia, acceleration and jump physics. Draw the pixel art directly with Canvas instead of using images."
Racing: "Create a nighttime neon street racer in Three.js with a third-person chase camera, wet reflective roads and arrow-key driving. Drifting builds nitrous. Boosting widens the camera and produces blue-purple exhaust flames. Include AI opponents, live standings and a three-lap timer."
I'd highly recommend you to try Ponytail to simplify the game code, plus a frontend design skill to polish the racing HUD, typography and boost meter. I haven't tested that combination on these demos yet, but I'd like to see how much further it can take the results.
Give @TencentAI_News Hy4 preview a spin in WorkBuddy and drop your builds in the replies. Curious what you'd throw at it.
Show more


Hy4 preview powers dynamic builds for a 770B open model.
770B total parameters, 49B active per token, native 1M context, Apache 2.0, direct vLLM and SGLang support, plus official FP8 weights.
In this demo, Hy4 creates a colorful, playable 2D space shooter game directly from a prompt, featuring active controls, enemies, visual particle effects, plus score tracking.
It is a preview. Test it, measure tokens/s, compare it with BF16 or FP8, and see what it builds.
Try it in WorkBuddy:
@TencentHunyuan @WorkBuddy_AI #Hy4Preview# #OpenSourceAI# #GameDev# #AI#
Show more

@TencentHunyuan Hy4 preview is a really good and frontier level model and it's currently free on @WorkBuddy_AI. The model is good across the board from document work to coding work to fun apps creation. It's super cool to chat with as well!
I did a full video testing it on YT, check it out:
Show more

✔️Hy4 preview just shipped an upgrade.
You flagged it: long thinking + over-verification on complex tasks.
We optimized it. Now live for everyone.
Same task quality. Fewer turns. Lower in/out tokens.
Bench + human eval both confirm.
We’ll keep iterating fast. Try it and tell us what still breaks.
Try on WorkBuddy:
Show more












