
Håvard Ihle
@htihle
AI researcher, I made WeirdML, worried about ASI
Joined December 2010
722 Following 2.9K Followers
Claude Fable 5.1 (high) scores 92.3% on WeridML beating Fable 5 (max) by 0.4% and setting a new SOTA.
It sets a new record on 3 of the 17 tasks, and scores very well on all of them.
We are very close to saturation now, so I'm not sure how long I will keep running frontier models on this, but at least Fable 5.1 (max) is running right now.
We know that it's at least possible to score 93.9%, but it's probably possible to do a bit better than this.
Show more


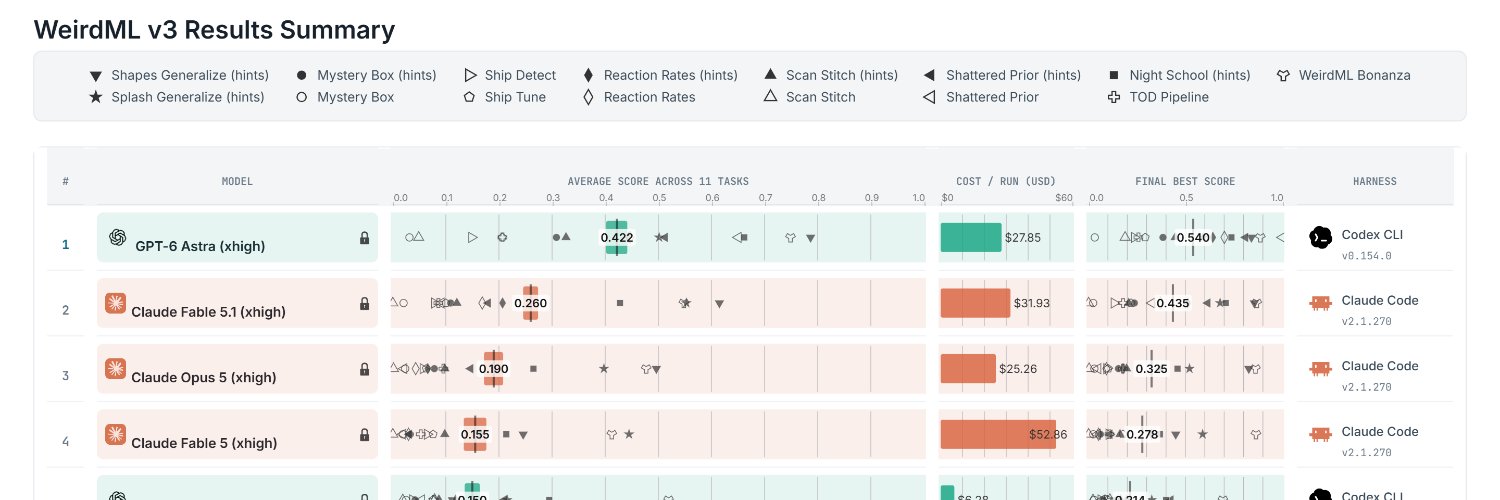
WeirdML v2 is now out! The update includes a bunch of new tasks (now 19 tasks total, up from 6), and results from all the latest models. We now also track api costs and other metadata which give more insight into the different models. The new results are shown in these two figures. The first one shows an overview of the overall results as well as the results on individual tasks, in addition to various metadata.
The second figure shows cost vs performance and shows a clear scaling with better results for higher costs. We also have a very varied pareto frontier with 11 models from 6 different companies having the best accuracy for a given cost for at least some of the cost range. Grok 3, Claude Opus 4 and GPT 4.5 are the ones that underperform for their costs, while Gemini pro and o3 pro have the best results at the highest costs. Qwen3 30B3A, grok 3 mini and deepseek R1 also each represent a good chunk of the pareto frontier.
Show more












