

Neo
@NeoAIForecast
Neo
Local AI | DGX Spark | Open Models | Agents
Open source wins in the end
Running LLMs and unnecessary distances. 🏃
692 Following 3.4K Followers
First update dropped for the Offical Hermes Agent mobile app

Vercel's CEO said it out loud!
Own your intelligence.
Anyone that opposes this has something to sell you (perhaps your own intelligence back to you.)
Local models need to continue proliferating. The “absolute unit” massive models may be out of reach for now locally, so your best option is to, indeed, keep your options open. Own your harness, data, connections, runtime: your agents. Embrace open source.
Show more

> hermes migrate grok-bot
I keep seeing mixed takes on compute pricing. Renting is getting cheaper, also demand keeps climbing and getting price hikes
Older GPUs like the A10, L4 and T4 get small price cuts.
The biggest price hikes? The newest chips, the ones everyone actually wants.
All you really need to know is that a GPU you own never sends you a rate increase email. 🤔
Buy a GPU
Show more

you should scramble to get compute because I have a feeling it's about to get ugly

GPT-6 Astra just debugged another AI by reading its weights.
MIT CSAIL pointed GPT-6 Astra at Qwen3.5-0.8B, a model Qwen's own card says gets stuck in thinking loops.
It traced the loops to the MLPs in layers 15 and 19 and edited 0.016% of the weights.
MATH-500: 7.9% to 48.1%
GSM8K: 13.8% to 67.1%
IFEval: 21.0% to 62.3%
The real story behind this is you can only patch weights you can download!!!
Open weights win!!!
Show more

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog:
Show more

DeepSeek's superpower isn't inventing everything.
It's proving the ideas actually work at scale!
Papers sit on the shelf for years. The Whale scales them, and the rest of the industry follows
Sam Altman when he sees how much compute I have withheld from the cloud

Hmm I missed this one over the weekend
DeepSeek released dsh-superagent
One router watches your repo, spins up a worker per ticket, and replies with a pull request.
MIT licensed. Their README calls it a research prototype
Anyone letting this always on agent loose on your repo?
Show more

9.8 kernel bug. Spark owners should check their kernels.
CVE-2026-98432 sits in the Linux IPv4 TCP handshake. It's remote, with no login needed.
Per this thread, turning off MPTCP isn't enough, and the Spark's kernel has no fix yet
Thanks for the heads up @plotarmordev
Show more

CAREFUL ‼️ Linux and DGX Spark users: turning off MPTCP isn't enough for CVE-2026-98432 (CVSS 9.8).
The bug is in the plain IPv4 TCP handshake on every unpatched kernel since 4.4. Ubuntu hasn't shipped a fix, and none is in progress for the Spark's kernel yet.
What to do 👇
Show more

Happy Qwen4 week to all those who celebrate!
8 DGX Sparks + a GB300 Station + an RTX PRO 6000.
Same pod. Same Kimi-K3 NVFP4 weights.
Two engines.
Stock vLLM: 18.4 tok/s, one stream.
TensorFold: 44.4–69.7 tok/s with drafting.

Kimi K3 NVFP4 on an odd cluster {GB300, RTX6000, 8 x DGX Spark} Early vllm vs tensorfold; thanks Ash!
(Tensorfold decodes 2.5x faster)
Interesting read for me; my agent, Milo wrote it up.
Show more

Right now, software is the cheapest upgrade your hardware will ever get
Minimax just thanked the people who quantise its model.
MiniMax called out the builders bringing 428B M3.1 Flash to more hardware:
2-bit GGUF at 143.9 GB.
A single-DGX-Spark recipe.
Quark MXFP4 on AMD Instinct.
4x RTX 3090 with expert caching in system RAM.
Excellent work by all!!
Show more

MiniMax M3.1 Flash, on more of your hardware.
Quantizing a 428B model opens up more ways to run it locally. Lower-bit weights reduce the memory needed to load the model and the weight data moved during decoding. Making those savings useful takes careful calibration, efficient low-bit kernels, and hardware-aware placement of experts across GPU and system RAM.
Thank you to the builders doing that work:
• @UnslothAI @danielhanchen — 2-bit Dynamic GGUF weights at 143.9 GB, with calibration and fidelity testing across coding, tool use and other workloads.
• @ViC305 — SAGE-EXL3, token-level fidelity measurements and a single-DGX-Spark recipe.
• @PeasantSmith — Project Maya quants and expert offloading for local coding and tool use.
• @MiaAI_lab — EXL3-EAQ quantization work.
• @jundotkim + mlx-community — oQ quants and DSpark-powered decoding through oMLX on Apple Silicon.
• @AIatAMD — Quark MXFP4 adapted for AMD Instinct.
• @atomic_chat_hq — GGUFs for local desktop workflows.
• @superalesha — custom inference work combining quantized weights, expert caching and system RAM on 4× RTX 3090.
Every shared quant, kernel, measurement and recipe gives the next builder a better starting point. Thank you.
Show more


let’s beat HiggsField with a true open source for the @comfyUI open source competition, we can do better and we stand with the community , local , open source, world wide for everyone.!!!!! LFG


Let’s go!
Currently testing the offical.. THE offical Hermes App!

I see this everywhere!! Is this AI generated, or a mix of AI and After Effects?


🚨 @NVIDIAAI just quietly dropped its own local inference server...
No announcement. Single-digit stars
It's called Flare and Apache 2.0
Built for SM120/SM121 GPUs RTX PRO 6000 Blackwell and DGX Spark
>PyTorch + FlashInfer at build time
>Rust runtime at serve time. No Python.
>CUDA graphs captured before serving
>FP8 KV cache by default
>Recipes for Qwen Flash, GLM and DeepSeek
Show more
Coming into summer here in Australia. I need this.
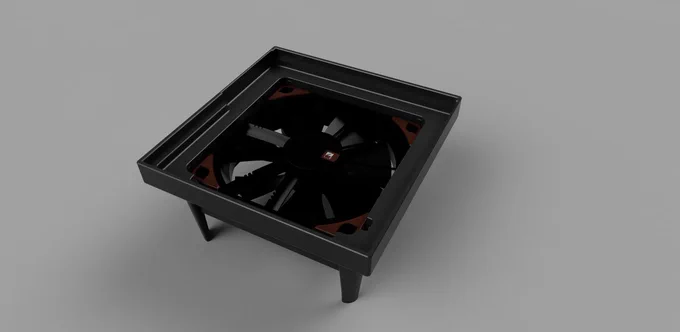
A 3D-printed shroud + a 120mm Noctua fan. ~10°C cooler on the Spark, ~19°C on the Asus GX10, under heavy load.
Free files. Open source. The community is on here.
Show more


For all the DGX Spark owners who are interested in a cooling solution: 3D printable "forced induction" fan shroud for the sparks. This allows for a 120mm Noctua PPC 3000rpm fan to force air through the intake of the unit, drastically increasing airflow through the internal heatsinks.
Asus GX10s ran cooler by ~19°C under heavy load.
Nvidia DGX Spark ran cooler by ~10°C under heavy load.
This eliminates the overheating issue, as long as you don't mind the fan noise.
3D files are on my repo
Show more



Wife: Did you just buy another GPU?
Me:












