
Morgan
@morganlinton
live long and benchmark 🖖
Joined January 2009
940 Following 46.1K Followers
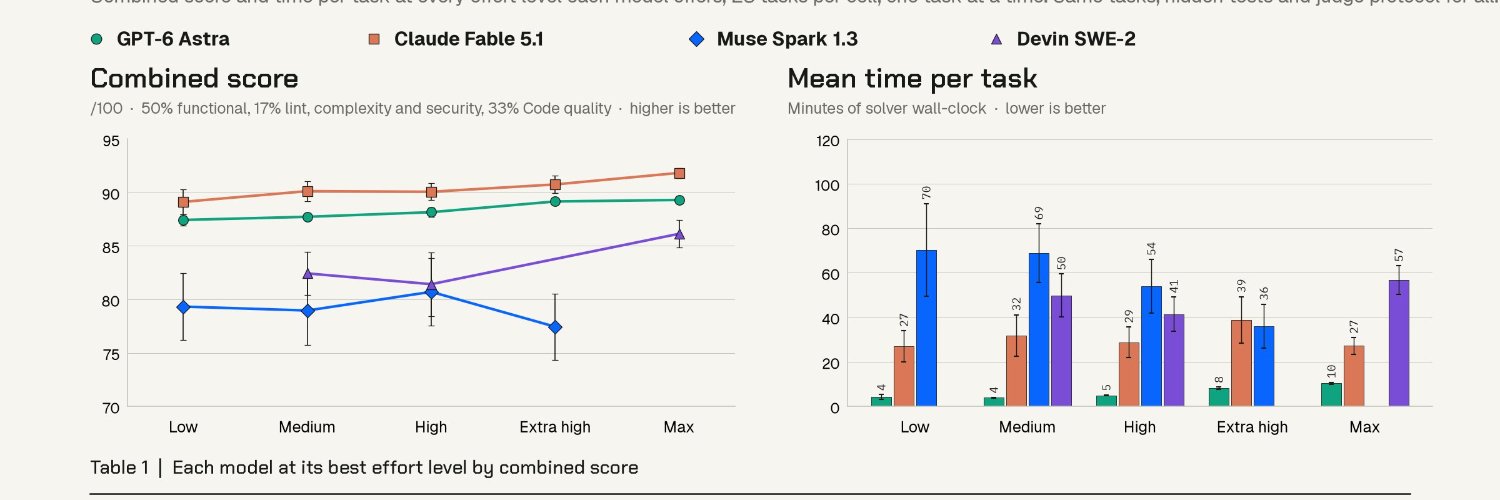
Okay, it took a week to get this done the right way, but it's finally all complete, my comparison of Astra and Fable 5.1 with @VulcanBench 🖖
A few things took longer here, the primary one being some updates to my benchmarking score to layer in code quality. This added 3-4 days of time, but for the right reasons.
This new class of models requires a new class of benchmarks. I don't think we can just look at things like accuracy any more, we also have to look at code quality/maintainability factors.
Now with VulcanBench-SWE v4, 33% of the score is code quality/maintainability. For me, and many other engineering leaders, seeing a model get a 98% on a benchmark doesn't really give us much signal.
I created VulcanBench to help make decisions around model and effort level, and this means not just building evals that represent the kind of work teams give to these models, but the kind of output we expect from these models when building scalable system and working in large codebases.
While I would normally share more about my thoughts, I'll let you come to your own conclusions about Astra and Fable 5.1. Both are excellent models, OpenAI and Anthropic have really created a new class of models here, now it's for us to decide if we need this horsepower for daily tasks, or just the hard stuff, and to be realistic about the quality of the output.
Model card below, and if you want to do a deep dive, you can find more on the VulcanBench site here:
And of course, since VulcanBench is open source, you can review every detail of this benchmark, or even run it yourself. The GH repo is here:
Live long and benchmark 🖖
Show more












