
Pratik Gandhi
@pratikg
accelerating the open frontier @eigenlabs. growing @darkbloomai, @yukonresearch, @eigencloud. ♥️ national parks.
Joined February 2009
1.9K Following 11.4K Followers
BREAKING: Darkbloom is the 1st provider serving Ternary Bonsai 2 27B, a full 27B reasoning model that fits in 8.5GB.
@PrismML compressed Qwen3.8 27B to 2 bits per parameter and it keeps 98.2% of the FP16 benchmark performance. An open-weight model, Apache 2.0, 262K context, image input, 75% cheaper to serve.
First run on the network, on a single M5 Max with no caching. 35 tok/s at 1K context, 31 at 10K, 19 at 50K.
One team compressing another team's open weights, served on 1,000+ Macs that belong to the community rather than to us. ❤️ ❤️ ❤️
Open innovation on open intelligence infra.
First 250 users get 100 million free tokens.
Show more
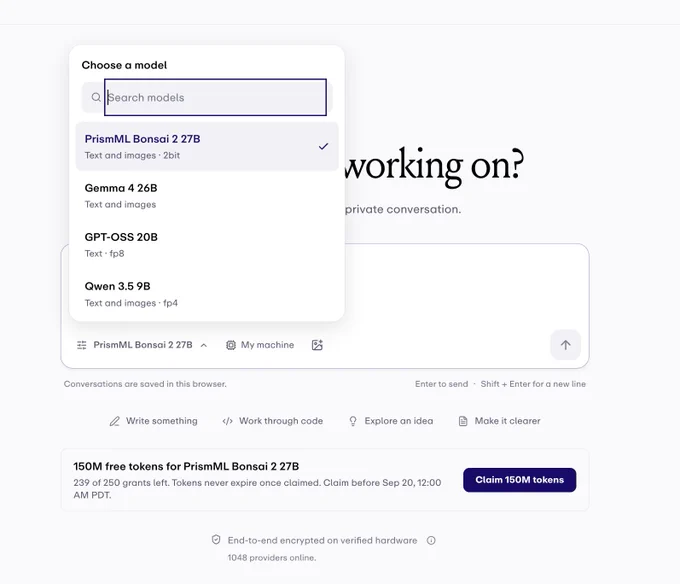

Darkbloom is the first model provider to support Ternary Bonsai 2 27B -- concentrated intelligence that fits on your phone.
Try it now:
First 250 users get 100 million free tokens;
PrismML's new flagship model:
- a ternary compression of Qwen3.8 27B at 2bits per parameter.
- 8.5 GB total, 5x smaller than original
- keeps 98.2% of the Qwen's FP16 benchmark performance.
- 75% cheaper than Qwen 27B.
Qwen3.8 27B already operates comparably with Opus 4.6 and 5.6 Luna on certain tasks. This one does it in the memory of a phone. 262K context, image input, Apache 2.0.
From our first run on the network, on a single M5 Max with no caching:
- 35 tok/s decode at 1K context,
- 31 tok/s at 10K,
- 19 tok/s at 50K.
But we expect more performance gain coming in a few weeks! That's a full 27B reasoning model running comfortably on any Mac.
1,000+ Macs are serving on Darkbloom right now. Go try it out!!
Thank you to @BabakHassibi @SahinLale @HessianFree @rsadri_ml @tushar_bans @evaninwords and the whole PrismML team. This is exactly the kind of model Darkbloom was built for.
You can read the essay by Bonsai on Why Local AI Matters:
Show more











