
Robin Bilgil
@RBilgil
800 Following 1K Followers
Just wanted to check out Mistal Le Chonk. Fittingly they're the only AI lab with a full screen cookie banner

Maybe controversial opinion but I don't want a realistic AI avatar. It's always going to be icky uncanny valley teritory. Why dont we make them like cartoons or something, I wouldn't mind talking to a cartoon!
Show more
Looking forward to trying this but Google seems to be great at making models that benchmark well and are horrendous to use, so we'll see.

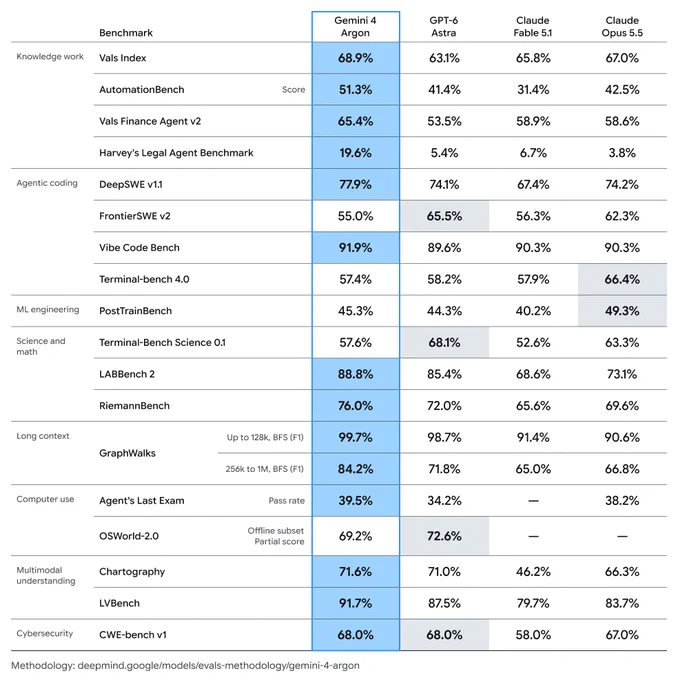
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Show more

Hey Instinct it's my birthday and also my wife's birthday and also it so happens to be our anniversary tomorrow, isn't it extraordinary? Please find us a reservation ASAP

Instinct CEO Noah Shinn says agents will let restaurants give tables to birthdays and anniversaries over whoever clicks first
"And traditionally, because of the way that the internet has worked, at least for reservations, it's been first come first serve. So anyone that comes in, no matter how important or how not important it might be, whoever gets in first gets the reservation."
"But what if you had the ability for the agent to be able to communicate on both sides, communicate, hey, this is important. This is actually the person's spouse's birthday, the 30th birthday, a very special event is coming up."
"And the restaurant too can say, let's actually prioritize birthdays or major decade birthdays or major anniversaries or these certain people, I don't know, whatever it might be, right?"
"So now with the ability, with all of the logistical burden of having to describe exactly what your case is and what's happening and why it's important. Now we have the ability to perfectly match what does the restaurant want? What does the user want?"
"And that will result in more special events for the users being able to actually have a spot in the restaurant."
Show more

There is actually every incentive for labs to let you use their subscription in other products
Here's the thing: the alternative is not that OpenAI sells Astra at 20x the cost via API pricing, but that others make do with Luna, Kimi and GLM which are 90% as good for most things
So in the first case OpenAI gets $200/month, or even $500/month now. And in the 2nd case they might get nothing
Show more
Really excited about this. For @whirl_sh we currently build a custom inbound webhook adapter for every integration so it can trigger your agent. It works like magic but it's a significant amount of work.
I expect we'll have to do that for quite some time (most integrations still don't have an MCP) but it's nice to have native support
Show more
One more launch today: the new MCP Events spec is now supported in ChatGPT 🎉
MCP servers can now push real-time updates (messages, comments, status changes, whatever) to ChatGPT, triggering automations for your users 🤯
It’s easy to add to your MCP server, too! Just point Codex at the docs and let it rip:
Show more

OpenAI was right to remove hourly limits from Codex. I want to use Opus 5.5 more but the 5 hour limit is constantly the bottleneck.
Some days you ship 15 features and other days you ship 3. The 5 hour limit tries to smooth this out and it sucks
Show more
LLMs are incredible at gathering all the right details, surfacing them in the right place, and even suggesting roughly what to write.
Just don't ever make them write the final words

my brain shuts off when I read writing like this... and I suspect a lot of other people’s do too.
in 2026, simply not writing emails with an LLM makes you stand out
Would be great to eliminate reasoning levels as the next advancement in LLMs. Isn't it feasible to at least learn a router for that?
It's nuts that Opus 5.5 low to medium are two totally different models but then you get almost nothing for another 5x in spend
Show more

Claude Opus 5.5 is now available in Cursor!
It's the new top model on CursorBench at 57.8% (Max) and costs 40% less per task than Opus 5.

We really need to talk about time-per-task for open models
Here's similar aggregated runs on @whirl_sh: 5.6 Luna spends <1m per task to GLM-5.3 flash's 6m avg, for IMO very similar real world performance.
From early tests MiMo v2.6 is a step in the wrong direction too
Show more

"Antigravity built in" - sounds pretty exciting if you don't know what it is

Googlebook is officially here! I’ve been so excited to share the details with the world.
Today, many of us rely heavily on laptops to get work done, but we think there is an opportunity to rethink the category to address the needs of people today. So we brought the best of ChromeOS and Android to create a new platform for laptops.
Our initial focus with Googlebook is to deliver an amazing laptop that feels awesome for Android phone users.
Here’s what to know about Googlebook 🧵👇
Show more

Isn't it about time this bar went straight to an AI assistant instead of web search?

I'm actually surprised Shopify didn't have a "search across all stores" before. I would've used that even in a pre-agent world

there's a future where nobody goes to amazon anymore and just shops via their agent who (in the background) taps into the database of products across ALL shopify stores.
while amazon blocks agentic shopping, shopify fully embraces it.
can't wait for that future.
Show more
Made a real-time slop detector with jev as you scroll

AI: "Short version: ..."
Narrator: It was not the short version
"This is nothing new, it's just X combined with a Y! I could've done this easily!"
"So why didn't you?"

noooo why is everyone using jev for stuff instead of self-hosting a custom BERT finetune or waiting 18 months for astra to get faster and cheaper
Have you noticed how some Instinct messages sound templated on WhatsApp? "Time sensitive: [message] - reply here and I'll explain".
Among many annoying things with WhatsApp for business is you can't send arbitrary messages to users if there haven't been any replies in the last 24 hours.
I really hope Meta see the light and change this before we see the light and migrate to iMessage / RCS
Show more

So hard to see a winner takes all market for Instinct. 0 network effects, no UI and no contract / tie-in. So you just move to whoever has the slightly better service.
(this could change if memory starts to matter but I highly doubt it, you can always extract memory)
Show more
Ever notice how AI never shows remorse or says "I'm sorry"? It's always "My bad" or "That was on me".

Told my Instinct to reach out to my bf's Instict to plan a surprise.
This is what his Instict texted him 🤪











