
Alex Cheema
@alexocheema
building @exolabs | prev @UniOfOxford We're hiring:
2.9K Following 54.8K Followers
My GTM lead asked me to share this. For serious business people pls.
Apple's AI strategy is Apple Silicon.
The iPhone, iPad, MacBook, Mac Mini and Mac Studio all use the same hardware architecture.
Apple Silicon is energy efficient, quiet, and the memory unit economics are incredible.
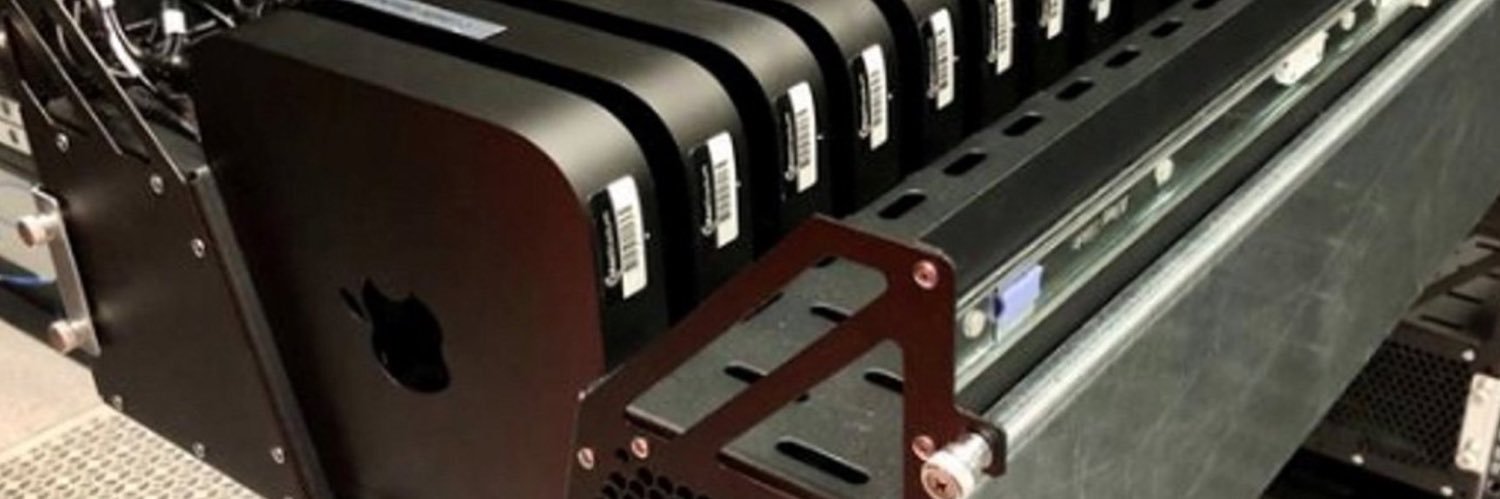
Apple has leaned hard into Local AI, now serving every segment of Local AI, from SLMs running on an iPhone/iPad to 2T models running on a cluster of 4 x 512GB M5 Ultra with RDMA using @exolabs (the cluster has 2TB memory @ 4.8TB/s).
Most inference will run locally, and Apple wants it to run on their silicon.
The main issue I see right now is the software. We need a stable, canonical inference engine rather than 10 unstable, incomplete ones. Who is solving this?
Show more

why did everyone suddenly decide specialized inference engines are a good idea?
i've seen at least 5 of these released in the last month.
what's wrong with vLLM/sgLang?
sure you can generate a slop inference engine quickly now but why fragment the ecosystem? it's harmful.
Show more
Crazy stuff. This caught my eye in the technical report...
Disaggregated inference between Thermodynamic Sampling Units (TSUs) and XPUs / FPGAs.
As I understand it, the TSU is extremely energy efficient at the sparse neural computations this new sparse transformer they've built does so running all of those on the TSU and everything else on an XPU or FPGA is much more energy efficient. It's also faster.
Show more

hiring a founding designer for @exolabs
in-person in SF
$20k referral fee
Interesting article in @theinformation.
Macs are Apple's fastest growing business right now, driven by massive AI demand.
Apple's AI strategy IS the Mac.
Trillion dollar opportunity imho.
Show more

Someone posted this on reddit and now it’s #1# on r/LocalLLM!
Answering questions about exo and local AI in the thread.

exo is currently top of r/LocalLLM (in response to this tweet).
answering questions there in detail on my alt: Longjumping_Crow_597.
feel free to ask any questions, exo or local AI related. link:
Show more

@RayFernando1337 @hnshah @exolabs We couldn't have done it without you. You believed in us at the very start, and went out of your way to HAND DELIVER weights to us in-person with your SSD. So clutch.
Show more
2 years ago, we achieved the first big milestone with @exolabs.
We clustered 2 MacBooks to run Llama 405B.
It felt like magic.
The consensus was running this model was only possible in a data center.
We ran it on consumer hardware, on 2 M3 Max MacBook Pros.
Most people thought it was a gimmick. It only ran at 2 tok/sec!
But, we believed that improvements to the software, hardware, and models would all compound.
So that maybe in a few years, we thought, this would improve 10x in software, 10x in hardware, 10x models = 1000x.
That was the vision.
We imagined a world where you would have frontier intelligence running quietly on your desk.
Today is the day that vision became reality.
The M5 Ultra is a 10x step-change improvement vs the M3 Max we originally clustered.
That, compounded with software improvements like RDMA over Thunderbolt, MTP and better kernels, and high intelligence density models like Qwen 3.8 27B, means we now have 1,000x better Local AI than when we started.
I am so grateful to the small group of people at Apple (including @doogie69 @awnihannun @angeloskath @DiganiJagrit @doogie69) who believed in this vision and had the foresight as well as the courage to take a swing at this early on. I'm confident they're just getting warmed up (looking forward to 4-bit / 8-bit compute units in M7 Ultra🤞).
With the M5 Ultra Mac Studio, we are going to have unmetered tokens running at API speeds at effectively zero marginal cost, running on your desk, so quietly and consuming so little power you won't even notice it.
Local AI is good now.
Show more

The 512GB M5 Ultra will ship in October with a massive 1.2TB/s memory bandwidth.
50% more memory bandwidth than M3 Ultra, 4.4x more than DGX Spark and M4 Pro.
Stacking 4 x M5 Ultra, I expect you'll be able to run Kimi K3 / GLM 5.3 faster than the API (>100 tok/sec).
Show more


Local AI is how we escape the marginal cost of intelligence.
It's the harness, guys! It's the harness!

Our general-purpose coding agent just scored 100% on the ARC-AGI-3 interactive reasoning benchmark.
NVIDIA AVO completed all 183 levels across all 25 public environments, figuring out what to do with no instructions, explicit rules, or stated goals.
Show more

With cloud inference, you're sharing a machine with 1,000 other users.
You are a retention/ROI data point on someone's analytics dashboard.
Locally, you own the hardware - it's all yours. You can tune it however you like.
There's no throughput/interactivity tradeoff and no competing incentives.
Show more

Cloud on the left
Local on the right
Amazing times, look at that speed.

about time we got on @ashbyhq

A year ago the consensus was everyone would be using one or two frontier models, running entirely on NVIDIA GPUs.
The reality now is we have hundreds of models each with different cost/speed/intelligence tradeoffs for different tasks, running on dozens of different local / data center chips (even older hardware).
Ironically the frontier models that were trained on NVIDIA GPUs have made it faster and easier to port kernels from CUDA to other hardware targets (AMD, Apple Silicon, Intel, ...).
There are people with no experience writing kernels using relatively cheap AI agents to implement efficient kernels for Apple Silicon, synthesizing all the tricks from existing CUDA implementations that were meticulously hand written by experts.
Funnily enough, since the performance of these kernels can be quickly and objectively evaluated by an agent by actually running the kernel on the hardware, it's an unreasonably tractable task for agents. They can continuously improve them in a fairly simple autoresearch loop. Kernel interoperability is solved ("The unreasonable effectiveness of AI agents").
The next continuation of this trend is to have millions of small, specialized models for each use case, tuned for each user based on how they use the models / their SLAs (e.g. maybe you're fine running a job overnight so it can run on cheaper hardware). They will run efficiently on any hardware, so then it's a choice of which hardware is the best for that specific thing. For this we need better infrastructure to evaluate models and map out the tradeoff space so we can give the optimal point in the tradeoff space of Model x Quant x Harness x Inference Engine x Config x Hardware.
Show more

anyone know any cracked designers?

Don't forget to claim your permanent username on LocalAI
- Use 'MZTACAT' as ref.
- Ends in few weeks
Reward still stands once we scale through ,,🕯️

Don't forget to claim your permanent username on LocalAI
Two Steps: (takes 50 seconds)
Visit:
- Sign in with HuggingFace (create if you don't have)
- Use Referral [ YOUTHEARCHANGEL]
- Pick a username and DONE
Show more

Old hardware is still useful for AI
V100 came out in 2017

My fastest @localdotai Qwen 3.8 27B result with NVFP4 isn't on Blackwell (5090 or GB10). It's a Volta V100⚡️ It can go up to 230 tok/s with MTP. Already faster than my 5090 on GGUF
Show more












