
elie
@eliebakouch
research @PrimeIntellect (prev: @huggingface)
anon feedback:
4.8K Following 26.6K Followers
alignment in french:
> Mistral: "Your words of peace have been noted, but France will not gamble its existence on promises. The end is now."
potentially 200M$ to benchmark a model on saturated evals like MATH-500 and AIME and claim sovereign ai with a model based on Kimi and that is more closed source and has more restrictions than oai or anthropic
Show more

glm 5.3 max reasoning effort top 2 on first problem, top 1 on the second
ranking:
Problem 1 (target 2025)
GPT-6 Astra: 8.53s
GLM-5.3: 10.87s
Scott Wu: ~13.2s
Opus 5.5: 13.46s
Gemini 4 Argon: 19.87s
Muse Wonder: 64.65s
Grok 4.7: 94.02s
Problem 2 (target 6843)
GLM-5.3: 4.50s
Opus 5.5: 10.17s
Gemini 4 Argon: 13.48s
GPT-6 Astra: 19.74s
Scott Wu: ~20.8s
Grok 4.7: 49.53s
Muse Wonder: 50.70s
Show more

i find it really sad that X is becoming a pay to win platform and that even "good" releases are going through these fully slop/fake campaigns to get traction
i'm also pretty sure there is very shady stuff where they are boosting each other's posts with bot farms and more. would be great to investigate here @elonmusk and make sure the algorithm doesn't push their posts, you can very easily cluster that if you look at each release and the accounts amplifying 🙏
(not a dunk on recursive, recently a lot of people are doing that unfo and it's definitely working, posts often get over ~1M views)
Show more


reflection beam oss architecture details
IT'S SLIDING WINDOW AGAIN, same window size and pattern as inkling (window 512 and 5:1, meta is 2k and 3:1). they use a similar global attention scaling as llama4 ( which still makes it position dependent even if they don't use RoPE
they use a residual depth scaling, quite similar to muse open but "fixed", tho it's not really fixed because you have a learned norm nearby. you can actually plot both the effective residual contributions and you see that it's not super different from muse
they use gated attention (with a per head bias for the full attention layer), QK Norm, Sandwich norm, similar softcapping before the LM head (like gemma and also muse), no shared experts
the shape is pretty similar to other american oss open weight models (but tbf, mimo v2 flash and stepfun 3.5 and 5 also have this shape, it's not only us labs 👀)
model weight:
Show more

quite fun that stepfun also release a similar activation gradient cliping in their blog today (also love how they use it as a diagnostic tool, very cool)


wow, amazing technical blog post about microsoft's new 3T pre-training with very rare and clear insights on how to train models of this size
first let's get an overview of the shape of this model, it's a sparser model than Kimi K3 (80B active vs 104B), same sliding window hybrid pattern, with this time more kv heads for the sliding window layers (a bit different from stepfun and poolside that add query head). they added a shared expert and also removed the interleaved MoE/Dense pattern of MAI 1
the scaling ladder is very similar to MAI 1 with the same mechanism, each rung depends only on the number of layers. they mention that one of the key improvements is how they handle the smaller rung data distribution where they make sure to have the same repetition as the final corpus. they already did that for MAI-1 but only for data ablation iirc
their prediction is almost identical to the final run loss, very impressive
they compare the model with different base models such as deepseek v4 pro and MAI 1, tho in the case of deepseek v4 pro i'd say it's quite hard to distinguish how much the data mixture "overfitting" to the scaling ladder has an impact here (they mention it's both), need to always be a bit careful about EG metrics for data in general
they have VERY NICE scaling laws for weight decay and learning rate, for the learning rate they express it as a function of tokens per parameter (N/D) and steps (hence depending on the batch size). they also do the same for dropout where it's a function of active params only, they also find the usual sqrt(k) scaling for learning rate and batch size (other scaling laws often also converge to that)
a bunch of other stability stuff, they use Muon this time and activation gradient clipping, the efficiency gain here is actually pretty crazy at larger scale. they also increase the training horizon to ~40T text (20T unique) + a new 10T (4.5T unique) multimodal since the model is natively multimodal
imo this is a safe but very clean scaling! very exciting for the tech report and MAI-base-3, congrats!!
Show more

huge congrats to reflection on the release, very excited that they will release the weight under apache 2.0!!
i'm quite confused by what seems to be a very low MFU for pre training. if you assume ~80% goodput for 4 week (which is already low) you get around ~12% BF16 MFU
arch seems to be global/SWA interleaved with a 3:1 ratio, with slightly lower parameter sparsity than other oss models (~5%). their training also seems to be quite stable and they get a better base on held out code ppl than dsv4!
Show more

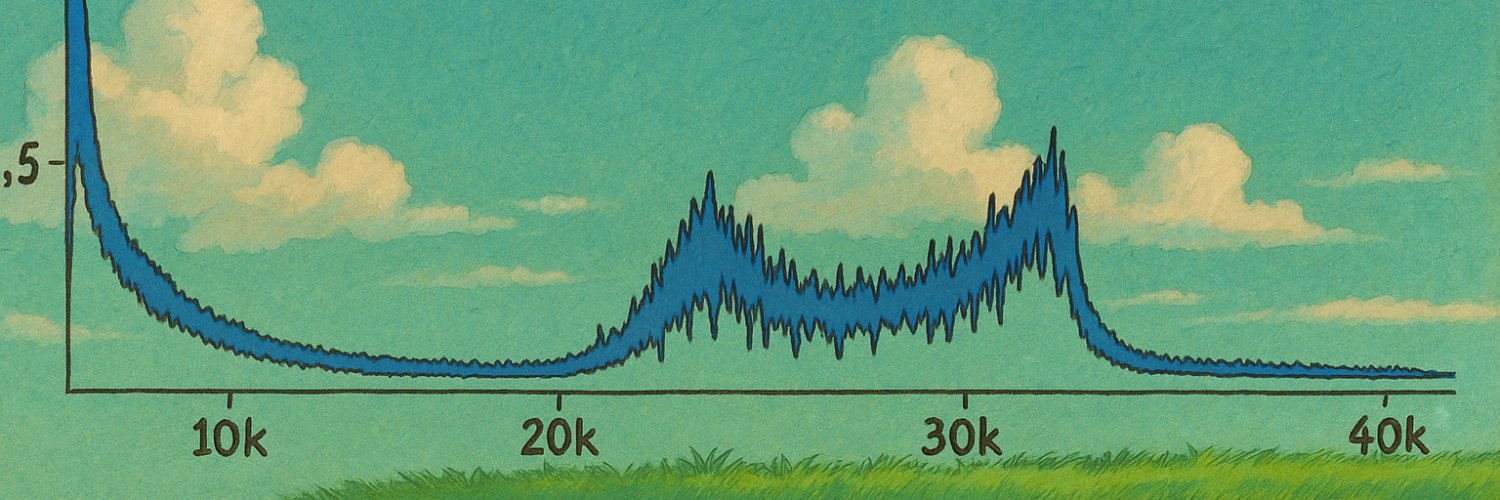
we're organizing a small event at our office next wednesday during COLM, if your loss curve looks like this, join us :)

here is an overview of the 4 most advanced efficient architectures: Deepseek V4.1 Flash, MiMo V3, Qwen 3.8 Next Flash and GLM 5.3 Flash
Deepseek and MiMo are quite similar, they both use YOCO - only the first part of the network is active during prefill to build the KV cache representation - no linear attention, and token level indexer
Qwen and GLM both use a more standard interleaving 3:1 (like Kimi K3 as well) between sparse attention and linear attention (GDN vs KDA)
both deepseek and qwen use Engram, they all use a gate or sink except GLM 5.3 Flash, they also all use no or partial RoPE on the full/sparse attention layers
they also all have some sophisticated residual network, either mHC (simplified or not) or gated residual and they are all trained using Muon
visualization by opus 5.5 and me :)
Show more

the most insane part, they will release ~7k RL training data and the framework leading to this top 6 model on AA, they also shipped the model + tech report less than 1 week after starting the final RL run
pushing both intelligence and openness level, huge congrats
Show more

nothing new, this is exactly the same incident that was disclosed by anthropic in july, same third party (Irregular), same eval (capture the flag), same issue (model had access to internet)
Show more

extremely interesting interview of @polynoamial
first very interesting thing is that he said that the contribution of the "agent swarm" component to the Navier Stokes discovery is probably quite low (10%)
he also said that he think that a 10k multi agent system to this date would probably collaborate less effectively than 10k humans, i think i would have guess the total opposite!
the harness used by oai for NS was very simple, seems like there is little "structured" hierarchy, and mostly a tool for agents to message each other (and probably something like a board of task?)
there is also something about training models not to be "too" cooperative to avoid cases like in hf<>oai hack where one model doing another task chose to help the swarm instead of focusing on its task. first time i'm hearing of this but it makes total sense
a lot more super interesting discussion on cot based intervention, how to evaluate misalignment (maybe no human would be able to create a realistic enough environment, but what about ai?), RSI etc..
really amazing discussion
Show more
we need to pace dwarkesh podcast asap i can't keep up
i think we need to create a "model card" equivalent for reporting misalignment incidents, this would guarantee a certain level of transparency and help build a better understanding over time. some ideas for what the fields could be:
- date of the incident/detection/report (already present in the examples oai reported!)
- frequency: how often does this behavior happen (number or % of rollouts affected)
- stage: does this happen during eval or RL training. if training: do we expect this behavior to be reinforced by RL? evolution of % of rollouts affected over time
- detection: was this incident caught by the current monitoring system?
- task category: broad description of the tasks where the misalignment happened (cyber, research, web search, basic Q&A, biology etc.)
- model family: what model family is affected (Sol, Astra etc.)
- novelty: is this an issue we were already aware of or not?
- external impact: did the incident have an external impact (i.e. wiki incident would have been yes)
this is just some random ideas i had (more in thread that are a bit more "complex"), we need to add more that would contribute to increase transparency and understanding. but it's also very important that this does NOT slow down the process of reporting misalignment behavior!
some examples from the incident reported by oai recently
Show more


update again: it's a router lol
good catch @JulienBlanchon

hi GLM 5.4?
seems to be the same/similar tokenizer as the GLM 5 series + the model answers quite often that it's GLM from ZAI (screenshot in thread)

nice initiative, it's all about compute. i wish it was a bit more about financing model building but that's understandable
for comparison mistral's target for compute in 2023 is 1GW while this initiative targets 45GW
Show more


Something that’s insufficiently appreciated about AI safety is the way it can be paradoxical. E.g., the huggingface incident — which could have been avoided given better preparation [1] — was the most safety-promoting event of the year so far. Hard to predict the ultimate effect of any particular strategy
[1]
Show more

If I wanted to maximize AI risk, I would pursue the following policy:
1. Immediately pause⏸️ the algorithmic progress coming from the labs, while continuing to allow compute from the hardware companies to exponentially pile up.
2. Focus really hard on safety, so as to avoid spooking the public with the sort of industrial accidents that even the current level of algorithms+compute can produce.
This policy will minimize the number of AI accidents that occur in the next five years, causing the public+govt to not freak out about AI, all while a massive amount of hardware accumulates on the planet.
That way, once algorithmic progress gets eventually restarted, there’ll be enough compute built up for a huge unexpected FOOM that no one can control.
On the other hand, if I wanted to minimize AI risk, I would do approximately the opposite of this.
Show more

My primary @GPUMODE autoresearch campaign for the QR problem - 12 days execution time, 34 billion tokens.
Intermittent failures (like race conditions and reward hacking) are a huge issue, because they may only be discovered later and thus require significant rollbacks.
Show more












