
vitalik.eth
@VitalikButerin
I choose balance. First-level balance.
mi pinxe lo crino tcati
551 Following 7.9M Followers
Expanding on why I believe "ETH as store of value (SoV)" makes much more sense to focus on than "ETH as fee-burning token".
Three primary reasons:
1. ETH as fee-burning token never was as strong as it seemed
2. Optimizing for ETH as fee-burning token would demand Ethereum and ETH function in ways that are very hard to make compatible with decentralization and capture resistance.
3. Meanwhile, optimizing for ETH as SoV is aligned with Ethereum focusing on its unique strengths (decentralization and CROPS)
EIP-1559 (including its burn) is fine and good, we should keep them. But we should not feel sad if fee burn is < 10% of breakeven indefinitely; the value of ETH comes from elsewhere.
The core idea: the big thing that people appreciate about Ethereum is decentralization and CROPS. The main pragmatic benefit that these things translate into is stability. SoV is the category where that is not an unneeded extra we merely put effort into for ideological reasons, but rather a pragmatic strength from the perspective of people putting in their assets. And in the era of AI disruption, stability will be highly valued.
Show more
@pcaversaccio they were on to something


@pcaversaccio they were on to something

Working on the vaccines part of this @PopVaxIndia supported in large part by Vitalik and Balvi, and would strongly recommend others jump in and work in all of these areas as well!

Last week, core devs had to delay forking the Hoodi testnet to Glamsterdam to study a report by @chain_security which revealed some problems with how EIP-8037 interacts with a few contracts.
Over the weekend, ppl tried to get a better picture of the impact and by now it's quite well understood. So here's what you need to know:
What's been known is that contracts which hardcode forwarded gas are affected by repricings, e.g. making state writes (SSTORE) more expensive.
What's new is that some coding patterns rely on specific invariant which were broken with EIP-8037.
Gas already spent can come back mid-tx, so gasleft() can go up. This causes two problems:
(1) a before / after gas counter underflows and reverts
(2) a failed sub-call hands gas back, so a path that should've been unreachable runs, and the tx looks like it succeeded
Related but different: (3) measuring the gas usage of a call using GAS - before and after the call - might undercount because the state gas reservoir is not visible during execution (e.g. gas_left).
It's now about deciding how to proceed. Delaying hoodi bought time but won't resolve the issue. This week, we have to dig deep into contracts and make sure nothing is missed. Eventually, this might just need some coordination among the involved parties (dapps, core devs, auditors, people running nodes, etc.), or worst-case, spec changes.
If you're an app dev or auditor, check your contracts for issues with EIP-8037/EIP-8038, and report them.
Also, share this with your favorite app dev to spread awareness.
Show more

⚠️ It has just been decided to delay the Glamsterdam hard fork on the Hoodi testnet because of security impacts we identified in this blog post:
We already found 13 real-world examples and are in responsible disclosure with the affected projects.
Please check your contracts as soon as possible, as the EF is determining how many contracts are impacted in which way.
Feel free to reach out to us with questions via glamsterdam@chainsecurity.com.
Show more

For anyone getting into biology, please consider taking airborne disease resistance more seriously.
It's a super important area of medicine that is a huge cause of death and sickness but easily gets forgotten. We're likely to get many more airborne plagues in the future due to the combination of not just extremely dense and interconnected society (including city and farm animals), but also accidents from bio research and offensive biotech (both from random people and from secret government programs that can easily get themselves exempted from safety restrictions), all enhanced by powerful AI.
Right now, this area is getting way less love than longevity research (which continues to be super important!), but it's an area where there are lots of unclaimed wins that we know exactly how to do (but are not yet doing) with present-day tech:
* early detection
* passive universal testing
* filtration/ventilation/UVC
* better vaccines (including making them open source and open science)
* cryptography to make all of the above privacy-preserving
We can have China-level pandemic resistance with Sweden-level limited intrusion into people's lives, and then go even further. We just have to actually do the work for it.
Show more
I am okay with Kimi 3.1 deliberately leaving out top-end offensive cyber capabilities from their training data.
Discriminating against use cases is MUCH less bad than discriminating against users. And the world does need all the time it can get to prepare, harden, check old code, (properly) formally verify new code, etc before the full weight of very powerful cyber attacks is upon us.
And if this first big wave of AI risk is not handled well, then we may well get a dystopia of highly locked down models, KYC gating on everything, highly intrusive surveillance on everything, a society where you may be a second or third or fourth-class citizen in terms of model access based on your credentials and nationality.
Show more
Ultimately, precompiles and EVM are both the wrong place to put most cryptography support into Ethereum. The reason is that precompiles and EVM both operate on data that has to be included into the ethereum chain somehow, which realistically means included in a block as calldata. That space is limited - even with PeerDAS and blocks-in-blobs, there's a practical cap of ~8 MB/s before it starts getting uncomfortable.
Remember: it's not a blockchain. It's a cryptographic world computer. Any data/computation that does not need to be in the "main thread" of data/execution should not be put into the main thread.
Instead, the correct solution is... EIP-8288 maximalism.
If you have any heavy computation that's self-contained, compute it and STARK it client-side (this is quickly getting faster and faster, even on phones), and push the STARK through the EIP-8288 recursive aggregation mechanism. The chain sees the fact that the computation was done and what the result is; it never needs to see the actual data and computation.
This way everyone can use whatever cryptography they want, the Ethereum chain can be lean, and we never need to add more precompiles again.
Show more
> we could still ultimately do Lattice stuff for accounts, wallets, etc. through a precompile if it is proved to be AI-secure
The ideal route to support everyone's cryptography is imo through 8288. You make whatever signature you want locally, then STARK it, and then it gets included through the stark aggregator machine. Don't need any calldata onchain. Ethereum can then never add a new precompile again.
Show more
Fun fact of the day: Bitcoin mining cost is split about 50/50 between compute capex and electricity. Meanwhile, AI inference is almost completely dominated by compute capex.


Wrapped zkAPI + Tor + extra cover traffic + local LLM prompt rewriting in an open-AI compatible daemon, and made a "paranoid mode" wrapper for my agent harness (pi):
Each conversation gets assigned a separate Tor circuit, your requests are masked with random cover traffic, zkAPI ensures you don't leak your identity through payments, and all prompts are locally rewritten (bring-your-own-local-model; I'm using qwen3.8-flash-next)
My agent harness is wrapped with a bwrap sandbox (also experimenting with MicroVM) and wrapped again with torsocks, so everything it does goes through Tor.
Here's what me asking it to do a simple research task looks like.
It's getting quite usable! Though you definitely still pay quite a bit in increased latency, especially when starting a new conversation.
Also, Tor is far from optimal here for privacy; the cover traffic mechanism is okay against passive adversaries but much weaker if the LLM provider is colluding with the guard and actively manipulating timing. This kind of task really requires a more specialized mixnet, probably take the tradeoff of a higher bandwidth multiplier and built-in constant cover traffic.
Also also, much cheaper zkAPI deposit and withdraw gas costs are coming to mainnet soon.
Show more


20 SIGNATURES. ONE PROOF.
Daisugi v0.3 aggregates 20 transaction signatures using LeanSPHINCS and LeanVM.
20 SPHINCS signatures are verified through a single aggregate proof.
For EL clients, verification requires the LeanVM verifier plus the LeanSPHINCS guest program.
Post quantum signature aggregation is live on Daisugi. Kudos to @Nethermind @Gianluca_Felli
Show more


Big congratulations to the @zksync airbender team for this milestone.
At this point, I consider the battle for speed to be definitively won, and the top priority for zkEVMs should shift fully to security.
To me that means formally verifying
(i) equivalence of the arithmetization to the ethereum spec
(ii) a hard maximum bound on (prover cost) / (amount of gas in block)
(iii) security of the proof system itself
Show more

For anyone who is either a fan of vaccines, or a critic of vaccines but open-minded to the idea that vaccines *could* be great if they were made with a more open-source open-science and public-spirited approach, I highly recommend checking out PopVax.
Show more

Correction: for multisigs the ideal "safe" rule is that you want each signer to change their key after each operation.
(This is making an implicit assumption that ECDSA might become weak, but not to the point where any crack of it would be literally instant so you would literally have to worry about eg. in-mempool frontrunning)
You definitely still want to gather sigs offchain if possible, to minimize the number of hours between "sig revealed" and "key no longer active"
But again: it's very easy to lose funds from a misconfigured rushed upgrade, so ... don't rush anything.
Show more
I don't recommend anyone scramble to move their funds to new wallets today. But we should take the risks to cryptography from AI-accelerated math seriously, and minimize our exposure to not just quantum-vulnerable cryptography, but also potentially AI-vulnerable cryptography.
The core new area of risk from this viewpoint is, unfortunately, ML-DSA / FHE / lattices.
(and it's also another reason, along with quantum, why ECDSA might fall even faster than expected, hence the "fresh address" recommendation)
So far most people have been in the mode of thinking "elliptic curves broken, hashes safe, lattices safe". But there is a good chance that the concrete security of lattices will take serious hits from the next two years of AI math.
The basic threat model is: factoring is something that naively takes 2^(n/2) time, but over decades smart people have found and optimized number field sieves, and degraded that to 2^O(n^(1/3)), which is why RSA keys and signatures need to be ~400 bytes (and not 64 bytes). What if there are skeletons in the closet like that, both for elliptic curves and lattices, that we are simply not smart enough to discover - but bots soon will be?
This is a major part of the reason why for the past year ethereum's lean roadmap has been going in the "hash-only" direction: no lattices, no ML-DSA, no Falcon, no lattice-based commitments inside ZK proofs, etc. Signatures in lean ethereum are all hash-based, either WOTS or SPHINCS-.
For signatures and proofs, we already know how to go hash-only. The bigger challenge is for *public-key encryption* - and this goes far beyond blockchains. Secure communication, anonymizing protocols, lots of things need public-key encryption.
And unfortunately there are long-standing mathematical theorems showing why public-key encryption cannot be done with hashes alone. You have to have some kind of trapdoor object that has at least one form of usable "structure" - either group theory (incl. isogenies) or lattices or code-based or potentially in the future even more newfangled and spooky things (local mixing?). But for anything that has structure, you should assume that AI will make at least some progress in breaking that structure. Here, one reasonable inference is that if you want to make something plausibly long-term secure, multiply the key sizes by 10.
To me that's a very plausible world and something not at all extreme to predict. If AI will bring us 50 years of math in 2 years, then that 50 years of math may very plausibly include a "naive factoring -> GNFS" level of improvement to our ability to break lattices. In that world, lattices will still exist, but they will have to be significantly bigger to guarantee the same level of safety.
And at those new larger sizes, hash-based constructions will beat lattice-based constructions on concrete efficiency in every use case where hash-based constructions are possible at all.
Theoretically, of course it's possible that hashes are broken too (eg. P = NP would imply that). But I think P = NP is very unlikely. And intuitively, it's much more likely that a mathematical object has exactly no exploitable structure (like hashes are intended to), than that a mathematical object has exactly ~3 forms of exploitable structure (for elliptic curves: associativity, Schoof, pairings) and not some secret fourth form of structure we have not yet discovered that greatly degrades its security (for elliptic curves, ECDLP and pairing security). Similar for LWE, SVP, RLWE and the zoo of lattice problems.
For this reason, we do not yet see any reason to worry and start padding the byte size of hashes (if we start to worry more, we would pad the round count first before doing anything to the byte size).
Concrete TLDR, my own personal views:
* Hash-based > lattice-based, in those situations where hash-based is possible at all
* For anything lattice-based, be much more paranoid on param sizes. Remember that blockchains are only a small portion of the cryptography story; this point goes far beyond blockchains and applies to eg. access to websites, secure messaging, Tor / VPNs ...
* For privacy protocols, strongly favor NOT putting encrypted notes onchain. Instead, send them offchain through some third-party mechanism.
* If it's not difficult for you, keeping your funds in addresses which have not yet been used to make a transaction is a good idea. If it's easy for you, do it. **But be careful about migrations; I personally have lost more money in botched migrations than I have lost in all hacks combined**.
* For multisig wallets, doing confirmations offchain is better than onchain, because this way the signatures of signer wallets do not get exposed to the public, so if ECDSA falls to AI much faster than expected, at least the multisig "gracefully degrades" to a 1-of-1 where the 1 is whoever was gathering the signatures - a much better place to be than "anyone can take the money"
Show more

I don't recommend anyone scramble to move their funds to new wallets today. But we should take the risks to cryptography from AI-accelerated math seriously, and minimize our exposure to not just quantum-vulnerable cryptography, but also potentially AI-vulnerable cryptography.
The core new area of risk from this viewpoint is, unfortunately, ML-DSA / FHE / lattices.
(and it's also another reason, along with quantum, why ECDSA might fall even faster than expected, hence the "fresh address" recommendation)
So far most people have been in the mode of thinking "elliptic curves broken, hashes safe, lattices safe". But there is a good chance that the concrete security of lattices will take serious hits from the next two years of AI math.
The basic threat model is: factoring is something that naively takes 2^(n/2) time, but over decades smart people have found and optimized number field sieves, and degraded that to 2^O(n^(1/3)), which is why RSA keys and signatures need to be ~400 bytes (and not 64 bytes). What if there are skeletons in the closet like that, both for elliptic curves and lattices, that we are simply not smart enough to discover - but bots soon will be?
This is a major part of the reason why for the past year ethereum's lean roadmap has been going in the "hash-only" direction: no lattices, no ML-DSA, no Falcon, no lattice-based commitments inside ZK proofs, etc. Signatures in lean ethereum are all hash-based, either WOTS or SPHINCS-.
For signatures and proofs, we already know how to go hash-only. The bigger challenge is for *public-key encryption* - and this goes far beyond blockchains. Secure communication, anonymizing protocols, lots of things need public-key encryption.
And unfortunately there are long-standing mathematical theorems showing why public-key encryption cannot be done with hashes alone. You have to have some kind of trapdoor object that has at least one form of usable "structure" - either group theory (incl. isogenies) or lattices or code-based or potentially in the future even more newfangled and spooky things (local mixing?). But for anything that has structure, you should assume that AI will make at least some progress in breaking that structure. Here, one reasonable inference is that if you want to make something plausibly long-term secure, multiply the key sizes by 10.
To me that's a very plausible world and something not at all extreme to predict. If AI will bring us 50 years of math in 2 years, then that 50 years of math may very plausibly include a "naive factoring -> GNFS" level of improvement to our ability to break lattices. In that world, lattices will still exist, but they will have to be significantly bigger to guarantee the same level of safety.
And at those new larger sizes, hash-based constructions will beat lattice-based constructions on concrete efficiency in every use case where hash-based constructions are possible at all.
Theoretically, of course it's possible that hashes are broken too (eg. P = NP would imply that). But I think P = NP is very unlikely. And intuitively, it's much more likely that a mathematical object has exactly no exploitable structure (like hashes are intended to), than that a mathematical object has exactly ~3 forms of exploitable structure (for elliptic curves: associativity, Schoof, pairings) and not some secret fourth form of structure we have not yet discovered that greatly degrades its security (for elliptic curves, ECDLP and pairing security). Similar for LWE, SVP, RLWE and the zoo of lattice problems.
For this reason, we do not yet see any reason to worry and start padding the byte size of hashes (if we start to worry more, we would pad the round count first before doing anything to the byte size).
Concrete TLDR, my own personal views:
* Hash-based > lattice-based, in those situations where hash-based is possible at all
* For anything lattice-based, be much more paranoid on param sizes. Remember that blockchains are only a small portion of the cryptography story; this point goes far beyond blockchains and applies to eg. access to websites, secure messaging, Tor / VPNs ...
* For privacy protocols, strongly favor NOT putting encrypted notes onchain. Instead, send them offchain through some third-party mechanism.
* If it's not difficult for you, keeping your funds in addresses which have not yet been used to make a transaction is a good idea. If it's easy for you, do it. **But be careful about migrations; I personally have lost more money in botched migrations than I have lost in all hacks combined**.
* For multisig wallets, doing confirmations offchain is better than onchain, because this way the signatures of signer wallets do not get exposed to the public, so if ECDSA falls to AI much faster than expected, at least the multisig "gracefully degrades" to a 1-of-1 where the 1 is whoever was gathering the signatures - a much better place to be than "anyone can take the money"
Show more

It wouldn’t be Devcon without @VitalikButerin.
This November, Vitalik is back on the Devcon stage, joining builders and communities in Mumbai to question, debate and build what comes next for Ethereum.
Mumbai, November 3–6. 🇮🇳
Get your ticket →
Show more


we just made @ethrex_client again the fastest client in @ethereum. i've always said, lambda would deliver and push the boundaries of ethereum.
after a couple of months focused on Glamsterdam hardening and Hegota prototyping, including hosting several public testnets for the most important EIPs coming in Hegota, we've turned our attention back to performance. this doesn't mean we're stepping away from that work, where we still have a lot to contribute.
The early results are very promising. In just a couple of days, we brought block processing time down from ~40ms to ~26ms in mainnet, making ethrex the fastest client once again. The image below compares how we perform today (ethrex-baseline) with what we've been cooking (ethrex-testing).
congrats @class_lambda, i'm proud of the team we've built. i love working with people that are way smarter than me.
thanks @ethereumfndn for the constant support.
Show more

Nethermind continues doing excellent work and making Ethereum more efficient and faster.

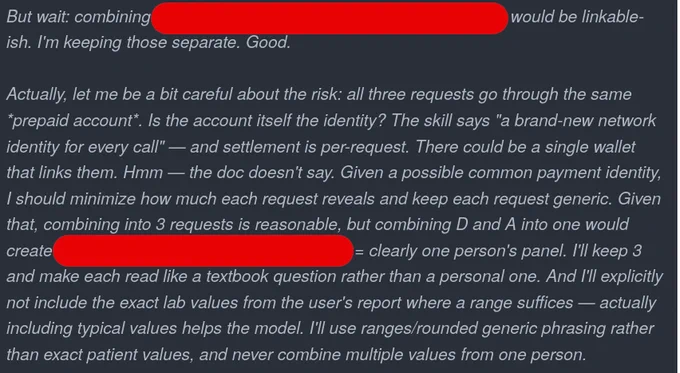
Doing a bit of a self-experiment.
Goal: use my personal health and travel data to provide personalized diet and exercise recommendations for me, using frontier models but in a way that avoids leaking to them any private information.
Strategy: use a local model (Qwen 3.8 Flash Next) to orchestrate, and use powerful remote models as a tool call to benefit from higher-level thinking and knowledge that the local model does not have.
Three-layer approach to privacy:
Avoid leaking personally identifiable information, or leaking my identity through writing style -> local model writes the queries to the frontier model, not me
Avoid leaking who I am through the payment channel -> zkAPI
Avoid leaking who I am through networking / IP -> Tor
You need all three (and finally we have all three, at least to some extent)
A skill file teaches the local model when and how to construct minimally-data-revealing requests to remote models. Use zkAPI-wrapped-with-Tor as a CLI tool.
And everything works! I got the recommendations back, info from frontier models helped to improve them.
Main deficiencies:
* Tor is really not optimized for request-by-request de-linking, which is the only form of network-layer privacy that really makes sense in today's world (long-running identifiers are too fragile). Probably not private enough, and latency 10-100x higher than it could be, at the same time.
* The skill file's request construction strategies are definitely far from optimal.
* Qwen 3.8 Flash Next is still too slow for comfort. It's comfortably running at 20-30 TPS, but it would only really start to feel fast at 100+
* There is a tradeoff: the more careful you are about what data you give to a remote model, the less it can help you
Show more