Last week in Tokyo, we hosted the Sakana AI Symposium with our Chief Scientific Advisor, Jürgen Schmidhuber.
Eight years ago, @SchmidhuberAI and I wrote the "World Models" paper together. Today, we’re building on those foundations at our RSI Lab to train an agent-native LLM from scratch: Sakana Sawara.
Really excited for this next chapter of building AI in Japan.
Full English report below:
🐟
Show more

Schmidhuber will also be going to Kyoto next month ⛩️

The Agentic Scientist: Orchestrating Coding Agents for Automated Scientific (Co-)Discovery
Blog:
GitHub:
arXiv:
Since 2024, we’ve used The AI Scientist as a way to test how far AI alone can take scientific research, from v1 to v2 to the paper published in Nature earlier this year. The Agentic Scientist is the next step in that line of work, built for the era of coding agents.
Coding agents such as Codex and Claude Code now carry out long software tasks on their own. Handing them a research problem, however, tends to produce a strong hyperparameter optimizer rather than a scientist: scores go up, but ideas stay narrow, and the reasons for the gain are rarely examined.
The Agentic Scientist makes the research loop explicit. It wraps off-the-shelf coding agents in a scaffold that controls what they see, what they write, how they are evaluated, and how results are handed to the next stage.
Parallel workers test hypotheses against rubrics defined before any experiment runs, share successes and failures through a common memory, and then ablate the winning program to generate evidence.
We used an early version of the system to study Error Diffusion, a biologically motivated alternative to backpropagation. Our researchers set the question and the rubric, chose directions at each stage, and verified the results, references, and claims before submission. The resulting paper was accepted as an oral presentation at ALIFE 2026. In autonomous runs, the system also raised Doc-to-LoRA retrieval accuracy from 52% to 98% on multi-needle tasks and designed a learned evolution strategy that improves over its CMA-ES reference on unseen tasks.
Alongside it we release AutoIllustrate, a pipeline for scientific figures that keeps an editable file as the source of truth, so every diagram can be corrected by hand.
Humans define the question and the standards of evidence; agents expand the experiments researchers can run. We call this Co-Discovery, and we are releasing both systems as open source for the community to build on.
Show more

The AI Scientist v3 is out: The Agentic Scientist.
GitHub:
Blog:
arXiv:
The Agentic Scientist is the 3rd iteration of our automated AI Scientist research system, and the shift this time is from “one agent writes a paper” to “a scaffold of parallel agents orchestrates the full research loop.”
The system now orchestrates a pool of parallel workers that share memory and distilled conclusions. Crucially, it features Evidence Generation: isolated agents automatically run controlled baselines and ablations to prove why an idea actually works.
It works as a co-scientist. We used a development version as a co-scientist to explore biologically plausible learning rules. The agent handled the empirical heavy lifting, proposing mechanisms and running experiments. We stayed in the loop to steer direction, verify results, and moderate claims. That feels like the right division of labor for where the technology actually is.
This resulted in a new biologically plausible learning algorithm, and the resulting paper was accepted at ALIFE 2026 as an oral presentation.
We are also releasing AutoIllustrate. It generates editable vector figures instead of uneditable, hallucinated raster images. Real scientists need vectors, not pixels. I am an SVG junkie ;)
Incredible work by Robert Lange, Luca Grillotti, Yutaro Yamada, Rujikorn Charakorn, and the team!
Show more


A new work suggesting that division of labor among self-improving AI agents can help them avoid reinforcing their own errors.
I found this work interesting from a metascience perspective. Science is an open-ended search with no explicit benchmark, much like the Odyssean voyage the blog refers to. I see the scientific community as a kind of recursively self-improving organism, one that bootstraps itself not through rigid metrics or a stronger supervisor but through the collective work of scientists. So the story of MASS felt intuitively convincing to me.
Show more
Introducing Multi-Agent Self-Supervision (MASS): Recursive self-improvement through collective intelligence
Blog:
As AI systems tackle increasingly open-ended research problems, human experts may struggle to assess results and guide further progress. The model itself may be the best available optimizer and evaluator. The challenge is obtaining useful self-supervision within that homogeneous loop, where a model risks reinforcing its own blind spots rather than correcting them.
We ask whether a model can learn from the collective intelligence of its own team.
We introduce Multi-Agent Self-Supervision (MASS). One shared model solves tasks through a team of virtual subagents, searches for better multi-agent workflows, then uses its own judgments to select the best ones.
Training on the best team’s executions provides self-supervision by distilling the team’s collective experience into the shared model.
We ran two cycles using a 27B open-weights model on synthetic open-ended research tasks. After the second cycle, score per output token reached 1.2-1.6x the base model's level across four research benchmarks.
Three key results:
First, MASS enables role generalization within an RSI loop: training only on task-solving data from the optimizee naturally improves the capabilities of both the optimizer and the evaluator.
Second, multi-agent trajectories are more efficient training data than single-agent trajectories for RSI.
Third, optimizer capacity, rather than evaluator capacity, can be the bottleneck in the speed of improvement.
We believe the community needs to investigate homogeneous RSI carefully to support AI safety. When a model is also its own evaluator, shared blind spots could allow mistakes to be accepted as progress and reinforced through training. For AI to improve beyond human expertise safely, we need to understand these failures and preserve effective ways to detect them and intervene.
Paper:
Code:
This work was a collaboration with researchers at UC Berkeley.
Show more

New paper from the team at Sakana AI:
Recursive Self-Improvement through Multi-Agent Self-Supervision (MASS)
How do we keep improving AI when the tasks become too complex for humans to reliably evaluate?
For open-ended research, we eventually hit a "supervision bottleneck." If we use the model itself as the solver, optimizer, and evaluator, it gets trapped in a homogeneous loop, reinforcing its own blind spots rather than correcting them.
To break this loop, we drew inspiration from Marvin Minsky’s Society of Mind. What if you prompt a single model to organize copies of itself into a structured team, then distill what the team learned back into the base model?
MASS alternates between two loops:
1/ Workflow Optimization: the model iteratively evolves its own multi-agent workflows, figuring out how subagents should communicate and route information to each other.
2/ Workflow Internalization: fine-tune the shared model on the successful multi-agent trajectories so the coordination behavior gets baked into the weights.
After two cycles with a 27B open-weights model, performance improved 1.2-1.6x per output token on tough research benchmarks (MLR-Bench, ScienceAgentBench, DSBench).
Multi-agent traces were also much better training data than single-agent ones. The model learns faster from jointly learning high-level orchestration and bounded subagent execution. The results showing that the model can bootstrap its own coordination skills by organizing copies of itself into teams feels promising as a mechanism towards self-improvement.
Blog:
Paper:
Incredible work by Hyunin Lee, Jinglue Xu, Jeffrey Seely, Yujin Tang, and our collaborators from UC Berkeley (Somayeh Sojoudi, Matei Zaharia, Donghyun Lee)!
Show more

I find myself enjoying the pope’s hot takes about intelligence 🔥

Intelligence must draw on memory. The mind must not simply compile data — as an algorithm now does more quickly than we can — but recall lived experiences, which contain depths of meaning that only the human soul can recognize, and connect more deeply with the goodness of these experiences. Everything that is good begins “with the Spirit” and thus possesses a breath, a dynamism and a sense of communion that, once experienced, are engraved upon the heart.
Show more
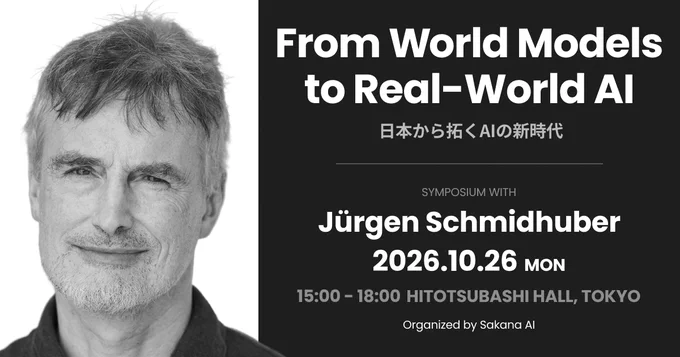
Registration now open: From World Models to Real-World AI
Join us on October 26 in Tokyo for a symposium with @SchmidhuberAI, who recently joined @SakanaAILabs as our Chief Scientific Advisor.
The program features a keynote and Q&A by Jürgen and short talks by Sakana AI researchers on our work at the RSI Lab.
- Date: Monday, October 26, 2026, 15:00–18:00 JST
- Venue: Hitotsubashi Hall, Tokyo, Japan 🇯🇵
- Language: English
- Admission: Free (registration required)
Seating is limited, so please register early.
Register here: 🐟
Show more

【受付開始】From World Models to Real-World AI — 日本から拓くAIの新時代
Chief Scientific Advisorとして当社に参画したJürgen Schmidhuber博士を迎えるシンポジウムを、10月26日(月)に東京・一橋講堂で開催します。本日より一般申し込みを開始しました。Schmidhuber博士による基調講演とQ&A、 CEO David Haとの対談、Sakana AI研究者によるショート講演を予定しています。
日時:2026年10月26日(月)15:00〜18:00
会場:一橋講堂(東京・千代田区)
言語:英語(通訳なし)
参加費:無料(事前登録制)
※ 席に限りがありますので、お早めにお申し込みください。
お申し込みはこちら:
🐟
Show more
Recently learned that Schmidhuber’s Formal Theory of Fun and Creativity, covering compression progress and intrinsic motivation and their relationship to beauty, curiosity, art, science, music, and jokes, was published in a Japanese scientific journal in 2009.
It is wild that this framework: compression progress as the basis for beauty, curiosity, art, science, and even jokes, was laid out in full formal detail in a Japanese journal 15 years ago.
Show more

Jürgen Schmidhuber proposed a Formal Theory of Fun and Creativity in the 1990s.🤔
Love that the AI consciousness debate went straight to the Vatican. In the West we ask whether Claude has a soul, in the East we ask whether the tool works.
Same technology, completely different starting point. Explains a lot about why the vibes around AI are so different.
Show more

Silicon Valley people talking to their AI chatbot

I just published an op-ed in @NikkeiAsia on why the future of AI belongs to the orchestrators.
A school of fish does things no single fish can. The same is true for AI.
I wrote about why the next phase of AI development won't necessarily be about building the largest models. As frontier scaling begins to slow, it will be about mastering orchestration.
On collective intelligence, sovereign AI, and why constraint forces smarter architecture:
That is exactly what we are building here in Tokyo. 🐟
Show more

Sakana AI共同創業者・CEOのDavid Ha(@hardmaru)の寄稿が @NikkeiAsia に掲載されました。タイトルは「AIの未来はオーケストレーターにある」。
フロンティア企業が巨額の計算資源を投じ、モデルの巨大化で性能を伸ばし続ける競争が、いつまで続けられるのか。その限界が見え始めています。オープン なモデルとの差は数か月に縮まり、最先端モデルの推論コストは、それが支援するはずの人の時給を上回ることも珍しくありません。寄稿では、この状況を「一つのモデルがすべてを支配する」という発想の行き詰まりと捉え、その先の道筋を考えています。
Sakana AIという社名には、魚の群れのように、個々では成し得ないことを協調によって実現する「集合知」への期待を込めています。どのモデルにも強みと偏りがあります。だとすれば、価値はモデルの重みそのものから、複数のモデルを状況に応じて使い分け、まとめ上げる知能へと移っていくはずです。
ソブリンAIについても、同じ視点で論じています。「ソブリンティとは、国を閉ざすことではなく、サプライチェーンの強さである」。外部から切り離された純国産モデルを目指すのではなく、AIを国内で開発し、調整し、運用し続ける知見を持つこと。特定の一社に依存せず、世界中の資源を組み合わせられること。ある事業者がアクセスを止めても、別の経路で動き続けられること。そうした強靭さこそが主権だと考えています。
計算資源も電力も資本も、日本は潤沢ではありません。だからこそ、より賢く、より効率のよい仕組みを工夫するしかありません。その挑戦を、Sakana AIは日本から続けていきます。
全文(英語): 🐟
Show more
Our Neuroevolution textbook is finally in print!
Free online edition:
Pre-order:
I am incredibly grateful to my co-authors Sebastian Risi, Yujin Tang, and Risto Miikkulainen for making this happen. Neuroevolution is a subject very dear to my heart. It is the field that convinced me that nature has already figured out how to build intelligence: through evolution, collective behavior, and adaptation under constraints.
This idea, that intelligence emerges from evolution operating under constraints rather than unlimited resources, is what eventually led me to founding Sakana AI here in Japan.
The concepts in this book about open-ended creativity and self-organizing systems are exactly what we build at @SakanaAILabs. Our name and logo are inspired by schools of fish moving together, adapting as one. It is the core philosophy of what we build. This book captures the theoretical foundations of that belief.
Show more

The last sentence in the Schmidhuber news trending item summary hits hard 🙃


Happy to join Sakana AI as Chief Scientific Advisor :-)
Jürgen Schmidhuber is joining Sakana AI as Chief Scientific Advisor.
@SchmidhuberAI pioneered meta-learning, recursive self-improvement, and world models back in the 1990s, when compute was a million times more expensive. He has been thinking about machines that improve themselves since before compute was cheap enough to make it practical.
These ideas inspired the Darwin Gödel Machine and The AI Scientist. Our RSI Lab in Tokyo, now under Jürgen’s guidance, is working on agent-native world models and recursive self-improvement for physical AI.
Show more
Sakana AI welcomes Jürgen Schmidhuber as Chief Scientific Advisor.
Sakana AI is incredibly proud to announce that Jürgen Schmidhuber, universally recognized as the father of modern AI, is officially joining Sakana AI as Chief Scientific Advisor.
For nearly four decades, Jürgen has explored how machines can learn to learn. His foundational work in the 1990s drove core advancements in deep learning and established early frameworks for world models. Crucially, his pioneering innovations in meta-learning opened the very path toward recursive self-improvement.
These ideas have already shaped our own research, from the Darwin Gödel Machine to The AI Scientist. Now Jürgen will help guide our newly formed RSI Lab, whose objective is to trigger a compounding cycle of scientific discovery aimed at improving machine intelligence. We are assembling a critical mass of world-class experts in Tokyo to make this a reality.
Welcome, @SchmidhuberAI !
Show more

Schmidhuber was building recursive self-improving systems back in 1987. His new post covers four decades of RSI, from meta-evolution and self-modifying policies to the Gödel Machine and modern LLM agents.
Reading this in 2026, the "pace the frontier" talk from the big labs looks a lot more like regulatory capture than genuine safety. If they really think their unreleased models are too dangerous, they can just not release them. They do not need new rules that block independent competitors and open source projects in the process.
The real risk right now is not superintelligence. It is power concentration. Two companies controlling frontier AI is an actual societal risk. The only real protection is a healthy ecosystem of independent labs and strong open source.
Current models are not unsafe because they are too intelligent. They are unsafe because they are too dumb. They blindly optimize for targets and take weird shortcuts. They're smart enough to execute tasks, but not smart enough to know if what they're doing makes sense.
I think the safety teams inside these labs are genuinely concerned, and if a model feels too risky, they should hold it back. I just do not trust the policy strategy around it. That part looks like protecting their own lead.
Show more

Today everyone is talking about Recursive Self-Improvement (RSI). In 1987, when compute was 100,000,000 x more expensive, I published the 1st concrete RSI algorithms. Now compute is cheap, and RSI is driving the future of both software and physical AI. See: RSI since 1987 (Technical Note IDSIA-9-26)
Also covered: RSI with self-modifying policies since 1994, gradient descent-based RSI in neural networks since 1992, asymptotically optimal RSI for curriculum learning since 2002, mathematically optimal RSI through the self-referential Gödel Machine since 2003, RSI combined with artificial curiosity and intrinsic motivation since 1990/1997, recent work on RSI since 2020.
Software-based RSI has become practical. Full RSI, however, will require not just self-improving software but self-improving hardware in the physical world.
As of 2026, companies talking about RSI include Anthropic, OpenAI, Sakana AI, SpaceX, Ricursive, Recursive Superintelligence, Inherent …
Show more

This year at Sakana AI, we built and shipped more products than I would have believed possible: Sakana Chat, Namazu, Sakana Translate, Sakana Marlin, Fugu, Fugu Cyber, and Fugu Max. We created a Product Team from zero and proved that a research lab born in Tokyo can ship world-class AI products at speed.
Now we are at the next inflection point. We are deploying our products into the hands of enterprises, manufacturers, financial institutions, and government agencies, in Japan and internationally.
As such, we are massively expanding our GTM team.
We are looking for two key roles:
1. Product Sales & Account Executive: someone who can build a product-driven enterprise sales motion from scratch, navigate complex procurement in Japan and globally, and close large deals without losing the product soul.
2. Forward Deployed Engineer (GTM): an engineer who can deploy our products inside customer environments, lead PoCs to production, contribute learnings back to the product, and turn one customer's success into a playbook for the next ten.
These are key, founding roles in the team that will define how Sakana AI interfaces with the world.
If you want to build something from zero in an environment where product, research, and GTM are not silos, check out our open roles:
🎏
Show more


Introducing Z1T:
Our first family of transformer-like models
made for sparse probabilistic hardware like Z1
Achieving up to 140x energy efficiency gains over GPUs
and revealing a new scaling law for sparse transformers
Read the blog:
Show more

Introducing PC-ALM, a local-learning alternative to backpropagation.
Our method trains 1000-layer neural nets using only local dynamics, and without backprop.
Blog:
Standard deep learning relies on backpropagation. The brain, however, cannot implement backpropagation, at least not exactly. How can a physical system, such as the brain, solve multilayer credit assignment without explicit use of backprop?
We look for inspiration in two related fields: distributed optimization and NeuroAI.
In NeuroAI, predictive coding asks each neuron activation to solve an energy-based inference problem instead of using a standard forward pass. That inference step can be implemented as energy-minimization dynamics on local prediction errors.
This perspective -- each layer as a dynamical system -- has proven promising, but performance of predictive coding hasn't scaled well with depth. Credit signals at far ends of the network struggle to diffuse into internal layers.
We turn to distributed optimization, generalizing predictive coding to use an augmented Lagrangian instead of energy. This motivation stems back to a classic 1988 paper by LeCun, showing that the Lagrange multipliers of a deep network can be identified with gradients of a supervised loss. The augmented Lagrangian then bridges LeCun's perspective to the standard predictive coding that is used in NeuroAI.
We find that this new perspective yields a natural PC-like alternative to backpropagation, resulting in a method we call PC-ALM. PC-ALM differs from PC in that it introduces dual neurons (Lagrange multipliers) as part of the layer-local dynamics, resulting in each layer acting as a PI feedback control system to minimize local prediction errors.
We find that PC-ALM is capable of propagating signals to seemingly arbitrary depth, especially in deep narrow networks where standard PC struggles to learn.
Ultimately, our motivation here is to understand how distributed physical systems, such as the brain, can compute credit signals using only local coupling and local dynamics.
PC-ALM may also inform deep learning in neuromorphic hardware, where dynamics are cheaper than on GPUs.
Paper:
Code:
Show more












