
Sakana AI
@SakanaAILabs
Building Frontier AI in Japan
Try Sakana Chat, Translate, Marlin, Namazu, Fugu 🐡
0 Following 141.8K Followers
Sakana AI Symposium: Building the Future of Language Models, World Models, and Physical AI from Japan
Event Report (English):
On October 26, we hosted the symposium “From World Models to Real-World AI” at Hitotsubashi Hall in Tokyo. More than 400 people joined us for a keynote by Professor Jürgen Schmidhuber (@SchmidhuberAI), who became our Chief Scientific Advisor in September, and a conversation with our CEO David Ha, his co-author on the 2018 paper “World Models.”
In his keynote, Jürgen traced the path to today’s AI through the work of researchers around the world, including Shun-ichi Amari and Kunihiko Fukushima in Japan, as well as his own 1990 work on world models and artificial curiosity.
Our Chief Scientist Takuya Akiba also introduced “Sakana Sawara” (provisional name), a new language model series we are building from scratch, starting with pre-training. If everything goes smoothly, the first model, a small model called “Sawara Small” (provisional name), will be released in spring 2027.
Perhaps half of the AI Jürgen has envisioned has been realized through generative AI. The other half, artificial scientists that design their own experiments and physical AI that works in the real world, has yet to scale. We believe that opportunity lies especially outside the big labs, and that Japan is one of the most promising places to pursue it. We hope this symposium becomes a starting point for shaping the next era of AI in Japan, together with companies and research institutions across the country.
Videos will be added later. A big thank you to everyone who joined us! 🐟
Show more

Sakana AIシンポジウム:日本から挑む言語モデル・世界モデル・Physical AI
開催レポート
10月26日、東京・一橋講堂でシンポジウム「From World Models to Real-World AI」を開催しました。9月にChief Scientific Advisorとしてお迎えしたJürgen Schmidhuber教授の基調講演 と、2018年に教授と論文「World Models」を共著したCEOのDavid Haとの対談に、400名を超える方にご参加いただきました。
基調講演では、甘利俊一氏や福島邦彦氏をはじめとする日本の研究者を含め、世界各地の研究者の功績に触れながら、自身による1990年の世界モデルや人工好奇心の研究まで、いまのAIにつながる流れをたどりました。
また、チーフサイエンティストの秋葉拓哉が、事前学習から自社で開発する言語モデルシリーズ「Sakana Sawara(仮称)」を発表しました。最初のモデルとなる小規模な「Sawara Small(仮称)」は、順調に進めば2027年春に公開する予定です。
Jürgenが思い描いてきたAIのうち、生成AIが実現したのはおそらく半分です。自ら実験を考える人工科学者や、実世界で働くPhysical AIといった残りの半分は、まだスケールに至っていません。その機会は大型ラボ以外にこそ開かれていて、日本はその有望な場所の一つだと考えています。このシンポジウムが、日本の企業や研究機関の皆さんとともに、日本のAIの次の時代を切り開いていく出発点の一つとなれば幸いです。
後日動画も公開する予定です。
ご来場いただいた皆さま、ありがとうございました!
Show more


Last week in Tokyo, we hosted the Sakana AI Symposium with our Chief Scientific Advisor, Jürgen Schmidhuber.
Eight years ago, @SchmidhuberAI and I wrote the "World Models" paper together. Today, we’re building on those foundations at our RSI Lab to train an agent-native LLM from scratch: Sakana Sawara.
Really excited for this next chapter of building AI in Japan.
Full English report below:
🐟
Show more

Sakana AI won 1st place in the company category at the “Recursive Self Improvement in Mathematics” Hack (OpenMath 2026), held with @stephen_wolfram at Harvard Innovation Labs.
Competition:
Results:
Drawing mainly on our Sakana Fugu models and internal agentic tools, our team (Rachel Teo, Abderrahmene Hamdi, Wenyi Wang) contributed 14 mathematical families, including 6 complete resolutions, plus new bounds and structural advances.
Thanks to the organizers and everyone involved.
We plan to share more about our approach and learnings in a future report.
Show more

On October 22, we welcomed a group from London Business School (@LBS) to the Sakana AI office 🐟
Professor Lynda Gratton joined the visit, and our Chairman Ren Ito, CTO Llion Jones, and CFO Ai Fujiki shared an overview of what we’re working on at Sakana AI.
During the Q&A, we received many sharp questions on how research and business connect, where the technology is heading, and our approach to expanding overseas. It was a lively conversation in a relaxed atmosphere.
Thank you for visiting!
Show more

QD-Rec: Open-Ended Evolution of Recommendations via Quality–Diversity
Blog:
GitHub:
arXiv:
Open-ended search has been used to discover algorithms, generate scientific ideas, and develop self-improving agents. With QD-Rec, we explore how it can support a different kind of task: helping people make decisions.
Which company should an acquirer buy? Which customers might benefit from a product? Which papers should a researcher read? In each case, the task is to choose among existing options, not generate new ones. At first glance, a finite, predefined candidate pool seems to leave little room for open-ended exploration.
However, a fixed set of options does not imply a fixed set of reasons for choosing them. The same company might be worth considering for its technology or its potential to open up a new market. The search over these reasons remains open-ended even when the options themselves are fixed.
QD-Rec searches over both what to recommend and why. Instead of aiming for a single best answer, it builds a diverse collection of recommendations, each pairing a candidate with a natural-language hypothesis explaining why it fits a particular decision maker’s goals, interests, and background.
The system combines three components. A contextual bandit learns which items to investigate next, balancing promising candidates with less-explored ones. An LLM generates hypotheses by adapting or combining the earlier recommendations. An archive retains new recommendations when they offer a novel reason, or replaces a similar recommendation when the new one is judged better.
We evaluate QD-Rec on acquisition target discovery, customer targeting, and paper recommendation. Compared with variants that remove evolutionary hypothesis generation or contextual bandits, QD-Rec achieves the highest mean LLM-rated quality in most settings and usually builds the largest archive. We also found examples where earlier recommendations with a low quality became stepping stones for later discoveries.
These experiments are a starting point. Practical applications will require richer, up-to-date information and expert human feedback to assess whether the proposed QD-Rec holds up beyond evaluation by an LLM judge.
We are releasing the code for QD-Rec so that researchers and practitioners can explore open-ended recommendation with their own decision-making tasks.
Show more

Schmidhuber will also be going to Kyoto next month ⛩️
The AI Scientist v3 is out: The Agentic Scientist.
GitHub:
Blog:
arXiv:
The Agentic Scientist is the 3rd iteration of our automated AI Scientist research system, and the shift this time is from “one agent writes a paper” to “a scaffold of parallel agents orchestrates the full research loop.”
The system now orchestrates a pool of parallel workers that share memory and distilled conclusions. Crucially, it features Evidence Generation: isolated agents automatically run controlled baselines and ablations to prove why an idea actually works.
It works as a co-scientist. We used a development version as a co-scientist to explore biologically plausible learning rules. The agent handled the empirical heavy lifting, proposing mechanisms and running experiments. We stayed in the loop to steer direction, verify results, and moderate claims. That feels like the right division of labor for where the technology actually is.
This resulted in a new biologically plausible learning algorithm, and the resulting paper was accepted at ALIFE 2026 as an oral presentation.
We are also releasing AutoIllustrate. It generates editable vector figures instead of uneditable, hallucinated raster images. Real scientists need vectors, not pixels. I am an SVG junkie ;)
Incredible work by Robert Lange, Luca Grillotti, Yutaro Yamada, Rujikorn Charakorn, and the team!
Show more

The Agentic Scientist: Orchestrating Coding Agents for Automated Scientific (Co-)Discovery
Blog:
GitHub:
arXiv:
Since 2024, we’ve used The AI Scientist as a way to test how far AI alone can take scientific research, from v1 to v2 to the paper published in Nature earlier this year. The Agentic Scientist is the next step in that line of work, built for the era of coding agents.
Coding agents such as Codex and Claude Code now carry out long software tasks on their own. Handing them a research problem, however, tends to produce a strong hyperparameter optimizer rather than a scientist: scores go up, but ideas stay narrow, and the reasons for the gain are rarely examined.
The Agentic Scientist makes the research loop explicit. It wraps off-the-shelf coding agents in a scaffold that controls what they see, what they write, how they are evaluated, and how results are handed to the next stage.
Parallel workers test hypotheses against rubrics defined before any experiment runs, share successes and failures through a common memory, and then ablate the winning program to generate evidence.
We used an early version of the system to study Error Diffusion, a biologically motivated alternative to backpropagation. Our researchers set the question and the rubric, chose directions at each stage, and verified the results, references, and claims before submission. The resulting paper was accepted as an oral presentation at ALIFE 2026. In autonomous runs, the system also raised Doc-to-LoRA retrieval accuracy from 52% to 98% on multi-needle tasks and designed a learned evolution strategy that improves over its CMA-ES reference on unseen tasks.
Alongside it we release AutoIllustrate, a pipeline for scientific figures that keeps an editable file as the source of truth, so every diagram can be corrected by hand.
Humans define the question and the standards of evidence; agents expand the experiments researchers can run. We call this Co-Discovery, and we are releasing both systems as open source for the community to build on.
Show more

New paper from the team at Sakana AI:
Recursive Self-Improvement through Multi-Agent Self-Supervision (MASS)
How do we keep improving AI when the tasks become too complex for humans to reliably evaluate?
For open-ended research, we eventually hit a "supervision bottleneck." If we use the model itself as the solver, optimizer, and evaluator, it gets trapped in a homogeneous loop, reinforcing its own blind spots rather than correcting them.
To break this loop, we drew inspiration from Marvin Minsky’s Society of Mind. What if you prompt a single model to organize copies of itself into a structured team, then distill what the team learned back into the base model?
MASS alternates between two loops:
1/ Workflow Optimization: the model iteratively evolves its own multi-agent workflows, figuring out how subagents should communicate and route information to each other.
2/ Workflow Internalization: fine-tune the shared model on the successful multi-agent trajectories so the coordination behavior gets baked into the weights.
After two cycles with a 27B open-weights model, performance improved 1.2-1.6x per output token on tough research benchmarks (MLR-Bench, ScienceAgentBench, DSBench).
Multi-agent traces were also much better training data than single-agent ones. The model learns faster from jointly learning high-level orchestration and bounded subagent execution. The results showing that the model can bootstrap its own coordination skills by organizing copies of itself into teams feels promising as a mechanism towards self-improvement.
Blog:
Paper:
Incredible work by Hyunin Lee, Jinglue Xu, Jeffrey Seely, Yujin Tang, and our collaborators from UC Berkeley (Somayeh Sojoudi, Matei Zaharia, Donghyun Lee)!
Show more

Introducing Multi-Agent Self-Supervision (MASS): Recursive self-improvement through collective intelligence
Blog:
As AI systems tackle increasingly open-ended research problems, human experts may struggle to assess results and guide further progress. The model itself may be the best available optimizer and evaluator. The challenge is obtaining useful self-supervision within that homogeneous loop, where a model risks reinforcing its own blind spots rather than correcting them.
We ask whether a model can learn from the collective intelligence of its own team.
We introduce Multi-Agent Self-Supervision (MASS). One shared model solves tasks through a team of virtual subagents, searches for better multi-agent workflows, then uses its own judgments to select the best ones.
Training on the best team’s executions provides self-supervision by distilling the team’s collective experience into the shared model.
We ran two cycles using a 27B open-weights model on synthetic open-ended research tasks. After the second cycle, score per output token reached 1.2-1.6x the base model's level across four research benchmarks.
Three key results:
First, MASS enables role generalization within an RSI loop: training only on task-solving data from the optimizee naturally improves the capabilities of both the optimizer and the evaluator.
Second, multi-agent trajectories are more efficient training data than single-agent trajectories for RSI.
Third, optimizer capacity, rather than evaluator capacity, can be the bottleneck in the speed of improvement.
We believe the community needs to investigate homogeneous RSI carefully to support AI safety. When a model is also its own evaluator, shared blind spots could allow mistakes to be accepted as progress and reinforced through training. For AI to improve beyond human expertise safely, we need to understand these failures and preserve effective ways to detect them and intervene.
Paper:
Code:
This work was a collaboration with researchers at UC Berkeley.
Show more

“The field of artificial life is a very long-term bet on intelligence.” 🐙
Our former intern Akarsh Kumar recently joined @MLStreetTalk to discuss the intersection of evolution and automated search for artificial life. He dives into our Digital Red Queen research, exploring open-ended evolutionary arms races in Core War using LLMs. This perspective on intelligence through artificial life is central to how we think about the future of agentic AI.
Show more

"Evolution is anything but random."
This is INSANE...
@akarshkumar0101 (@MIT_CSAIL, @SakanaAILabs) on artificial life: searching the space of possible universes with foundation models, why evolved networks find structure SGD misses (with @kenneth0stanley), and LLMs evolving Core War programs.
Show more

Beyond Imitation: A Framework and Benchmark for LLM-Assisted Peer Review
Peer review needs support, not substitutes. Accepted at TMLR: our new paper on using AI to help reviewers catch errors in research papers.
As research submissions grow, so does the workload for the experts who evaluate them. AI review systems are emerging as a potential solution, but much of their development and evaluation focuses on how closely they imitate human reviews.
In our work “Beyond Imitation: A Framework and Benchmark for LLM Assisted Peer Review”, we explore how AI can support the review process without losing the human touch. We focus on one demanding but essential task: catching errors in research papers.
We build an automated pipeline that deliberately introduces contradictions into papers by adding statements that conflict with information elsewhere in the manuscript. These planted errors give us clear targets for testing whether AI reviewers can spot and explain what is wrong.
Not all errors carry the same weight. Some undermine a paper’s central findings; others affect smaller details. We map the connections between each paper’s claims, methods, and evidence in a knowledge graph to estimate the severity of each contradiction and better assess what different systems can catch.
We also introduce Multi-Layered Review, an AI review system inspired by the Three-Pass Approach to reading research papers. It first outlines the main ideas, then examines the details and potential weaknesses, and finally brings its observations together into a review. The idea is simple: understand the paper before judging it.
In our evaluations, the system detected more errors than the other review systems we tested, including on papers withdrawn because of real mistakes. Its feedback emphasized different aspects of the work from human reviews, offering a complementary perspective, while its assessments of paper quality remained broadly consistent with human judgments.
Our goal is to give reviewers useful support in checking research, with human expertise and judgment at the center.
Open Review:
Show more

Recently learned that Schmidhuber’s Formal Theory of Fun and Creativity, covering compression progress and intrinsic motivation and their relationship to beauty, curiosity, art, science, music, and jokes, was published in a Japanese scientific journal in 2009.
It is wild that this framework: compression progress as the basis for beauty, curiosity, art, science, and even jokes, was laid out in full formal detail in a Japanese journal 15 years ago.
Show more

Jürgen Schmidhuber proposed a Formal Theory of Fun and Creativity in the 1990s.🤔
Registration now open: From World Models to Real-World AI
Join us on October 26 in Tokyo for a symposium with @SchmidhuberAI, who recently joined @SakanaAILabs as our Chief Scientific Advisor.
The program features a keynote and Q&A by Jürgen and short talks by Sakana AI researchers on our work at the RSI Lab.
- Date: Monday, October 26, 2026, 15:00–18:00 JST
- Venue: Hitotsubashi Hall, Tokyo, Japan 🇯🇵
- Language: English
- Admission: Free (registration required)
Seating is limited, so please register early.
Register here: 🐟
Show more

【受付開始】From World Models to Real-World AI — 日本から拓くAIの新時代
Chief Scientific Advisorとして当社に参画したJürgen Schmidhuber博士を迎えるシンポジウムを、10月26日(月)に東京・一橋講堂で開催します。本日より一般申し込みを開始しました。Schmidhuber博士による基調講演とQ&A、 CEO David Haとの対談、Sakana AI研究者によるショート講演を予定しています。
日時:2026年10月26日(月)15:00〜18:00
会場:一橋講堂(東京・千代田区)
言語:英語(通訳なし)
参加費:無料(事前登録制)
※ 席に限りがありますので、お早めにお申し込みください。
お申し込みはこちら:
🐟
Show more
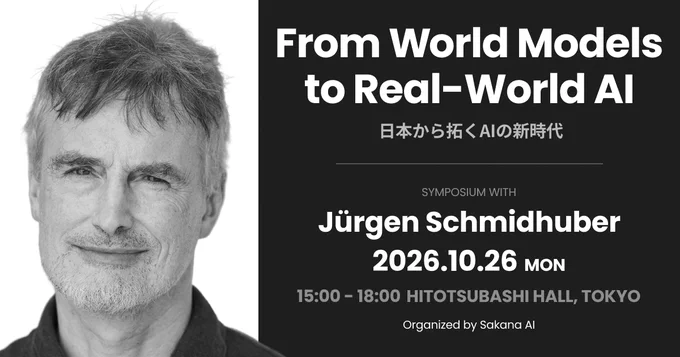
Sakana AI welcomes Jürgen Schmidhuber as Chief Scientific Advisor.
Sakana AI is incredibly proud to announce that Jürgen Schmidhuber, universally recognized as the father of modern AI, is officially joining Sakana AI as Chief Scientific Advisor.
For nearly four decades, Jürgen has explored how machines can learn to learn. His foundational work in the 1990s drove core advancements in deep learning and established early frameworks for world models. Crucially, his pioneering innovations in meta-learning opened the very path toward recursive self-improvement.
These ideas have already shaped our own research, from the Darwin Gödel Machine to The AI Scientist. Now Jürgen will help guide our newly formed RSI Lab, whose objective is to trigger a compounding cycle of scientific discovery aimed at improving machine intelligence. We are assembling a critical mass of world-class experts in Tokyo to make this a reality.
Welcome, @SchmidhuberAI !
Show more

Introducing PC-ALM, a local-learning alternative to backpropagation.
Our method trains 1000-layer neural nets using only local dynamics, and without backprop.
Blog:
Standard deep learning relies on backpropagation. The brain, however, cannot implement backpropagation, at least not exactly. How can a physical system, such as the brain, solve multilayer credit assignment without explicit use of backprop?
We look for inspiration in two related fields: distributed optimization and NeuroAI.
In NeuroAI, predictive coding asks each neuron activation to solve an energy-based inference problem instead of using a standard forward pass. That inference step can be implemented as energy-minimization dynamics on local prediction errors.
This perspective -- each layer as a dynamical system -- has proven promising, but performance of predictive coding hasn't scaled well with depth. Credit signals at far ends of the network struggle to diffuse into internal layers.
We turn to distributed optimization, generalizing predictive coding to use an augmented Lagrangian instead of energy. This motivation stems back to a classic 1988 paper by LeCun, showing that the Lagrange multipliers of a deep network can be identified with gradients of a supervised loss. The augmented Lagrangian then bridges LeCun's perspective to the standard predictive coding that is used in NeuroAI.
We find that this new perspective yields a natural PC-like alternative to backpropagation, resulting in a method we call PC-ALM. PC-ALM differs from PC in that it introduces dual neurons (Lagrange multipliers) as part of the layer-local dynamics, resulting in each layer acting as a PI feedback control system to minimize local prediction errors.
We find that PC-ALM is capable of propagating signals to seemingly arbitrary depth, especially in deep narrow networks where standard PC struggles to learn.
Ultimately, our motivation here is to understand how distributed physical systems, such as the brain, can compute credit signals using only local coupling and local dynamics.
PC-ALM may also inform deep learning in neuromorphic hardware, where dynamics are cheaper than on GPUs.
Paper:
Code:
Show more

Peak performance across hard benchmarks:
• Best or joint-best on 5/8 benchmarks (DeepSWE, Chartography, Toolathon, GDP.pdf, SWEFish)
• Chartography: 48.3 (outperforming Opus 5 & Fable 5)
• DeepSWE: 74.3
Achieved without Fable 5, Fable 5.1, or GPT-6-Astra in the agent pool.
Details: 🐡
Show more

Fugu Ultra v2 is now live on @OpenRouter 🐙
Our flagship orchestration engine built for peak performance on complex multi-step reasoning, autonomous research, and full-stack software development.
Show more

Introducing Fugu Max and Fugu Ultra v2: the next evolution of Sakana Fugu’s multi-agent orchestration system.
Try:
Blog:
The frontier that actually matters is the Pareto frontier: capability on one axis, cost on the other. But the industry still treats it as a static menu of isolated models. Today we are resolving that with a dynamic architecture:
Fugu Max expands the Pareto efficiency frontier. By orchestrating our largest pool of open-weights and specialized models to date, including NVIDIA Nemotron family, it dynamically routes tasks to the leanest capable model. Fugu Max delivers performance within striking distance of elite models at two to six times lower cost.
Fugu Ultra v2 pushes the peak capability of orchestration higher than ever before. On Chartography, it outperforms Opus 5 and Fable 5. On DeepSWE, it outperforms models that cost three to five times more per token. Crucially, it does all of this without Fable 5, Fable 5.1, or GPT-6-Astra in its agent pool.
The Fugu orchestration system evolved with model resiliency in mind. It does not rely on individual frontier models to deliver frontier output. By orchestrating a swappable pool of open and specialized models, it outperforms closed ecosystems while protecting users from vendor lock-in, API revocations, and sudden service cutoffs.
Fugu Max expands the Pareto frontier outward. Fugu Ultra v2 pushes it upward. Orchestration does not force a choice between cost and capability. It advances both simultaneously.
Show more












