

Loktar 🇺🇸
@loktar00
I test what models can build.
Christian. Dad. Veteran.
1.7K Following 7.2K Followers
My goodness...
Deepseek Flash Local EXL3 with Maya.
136 minutes, Deepseek Harness.. turned out crazy good.
I'm hoping Qwen 4 demolishes this output.. but what these models are doing lately is blowing me away.
Show more

Asked Deepseek official API and EXL3 2.9 BPW using Maya to create fungal asteroids with a HD 2d look to them.
I'm partial to Mayas output honestly. Was pretty impressed with the results.
What we can generate locally is just absurd at this point.
Show more

Doing some small play mini games
Deepseek vs Opus 5.5.
This is a play on Starfox as a small play.
It's absolutely crazy how far Open models have come.

Deepseek 1017 this is the same prompt I used with Opus and a few other models..
Deepseek is definitely the best Open model result by far, rivaling Opus result.
Show more

@teortaxesTex This is why I stopped testing them, I have a sneaking suspicion voxels are part of the training data / benchmaxed now or will be VERY soon.
This does look excellent though.
The craziest thing happened to me in an interview yesterday.
I interviewed my first deep fake candidate. It took me a bit to catch on.
My coworker noticed his glasses looked off.... there was a second ghost frame smeared across his cheeks. He'd been running a live face filter the whole interview
So I asked him to put his hand in front of his face. He put it up right NEXT to his face lol, never in front. Asked again, still wouldn't do it
He looked a little different from his linked in and his github (which I wont link here) hiring and interviewing is so ridiculous now.
In the days of AI we're going to have to be more careful.. and forced to move to in person interviews.
Show more

My favorite firearm platform of all time.
Locally generated the models with trellis on a 5090, and had Opus make it a showroom experience.


Inspired by @loktar00 and @Blackwellboy I started using Claude to make rapid prototypes of a 4x RTS based around the start of the copper age through the Bronze Age collapse.
Discord in comments.
Show more

Not a 3090, but a 2080 ti 22gb I picked up for my son. Was tempted to put it in one of my boxes to test but I'll let him I guess.


POV: Your Ram in 2026


Deepseek Flash, created a playable version as well.
0 shot 1 turn. In fairness have played with this prompt and generated it 10-15 times lol.


Using @AiClairvoyance, made Star Control Hyper Melee. In the background while I was working on other things.


Real talk. Amazing work. adopting for my work. Credit will be in the readme: @haoailab


What the AI industry did to its customers in the last 8 days:
OpenAI cut the $200 Pro plan in half.
OpenAI launched a $500 plan.
OpenAI started watermarking your text.
DGX Spark went from $3,999 at launch to $6,950.
Micro Center started scanning ID to sell an RTX 5090.
Micron sold 75% of its 2027 memory to someone who is not you.
What happened to the things I own:
Nothing. My 4x 3090 are the same cards. The Qwen weights on my SSD are the same file. Nobody emailed me about a new tier.
I dont run local models because they are the smartest. I run them because its the only part of my AI setup where the rules didnt change this week.
Download the weights. Buy the hardware. Do it before the next announcement.
Show more


@ItsmeAjayKV Maybe of interest to you just recently did my set of 4 3090's and did a maintenance guide vid. Save the GPUS!


Introducing Beam: a highly efficient agentic open model with 501B total parameters and 23B active.
- Frontier reasoning efficiency
- Advances the Western open frontier on coding & agentic tasks
- Trained end-to-end from scratch
Full weights release this month.
Learn more about Beam:
Show more


David vs Goliath, AI edition 😅
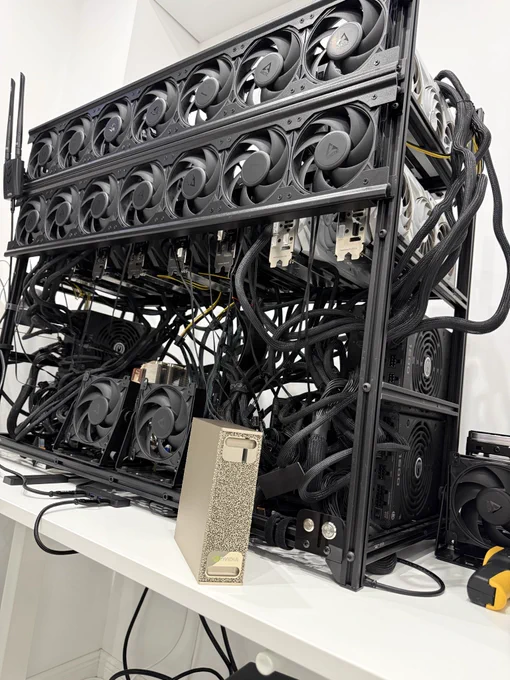
My DGX Spark sitting next to the 14× RTX 3090 Godzilla monster.
David won’t be fighting alone.
Once I get all 4 Sparks, I’m going to benchmark them against this beast. Really curious to see how close four tiny boxes can get in real-world LLM workloads.
Should be a fun comparison 🔥
Show more

GLM Flash 5.3 locally, little spring beaver dam.


GLM 5.3 Flash on 4 x 170HX - Need for SPEED edition 🔥
Single stream: Up to 481 tok/s (+10%)
Concurrency 8: Up to 949 tok/s (+13%)
Prefill: 3197 tok/s (+4%) / KV Cache: 1.2 million (+12%)
RTX Pro 6000 tier performance at a fraction of the price? Yes please! Full repo below. 👇
Show more












