

Teortaxes▶️ (DeepSeek 推特🐋铁粉 2023 – ∞)
@teortaxesTex
We're in a race. It's not USA vs China but humans and AGIs vs ape power centralization.
@deepseek_ai stan #1#, 2023–Deep Time
«C’est la guerre.» ®1
3.3K Following 76.7K Followers

Since I went into this release:
*It's a smaller selection of 989 envs used to RL a 9B distilled model, not the big MiMo.
*Rewards are not self-contained: general part need to set up a judge and webdev rely on their own grader service+vlm.
*Most important part is inside general/envs directory (+ docker), not the dataset displayed on hf: genuinely solid mix of real/simulated documents we rarely see in OSS.
Show more
I don't think SpaceXAI is at 10% MFU (at least now)

1/ One thing people don't talk about is the 256k Huawei peerium cluster. Cuz the 950DT is about 1/4 the GB300. But SpaceXAI only gets 10% mfu out of their 200k GB300 clusters.
What I find annoying is that everyone celebrates how cheap Engram is but nobody wants to ask "is Engram any good tho?" Like, you're not getting a free offload of FFNs to DRAM. How much does it add to modeling?
I trust DeepSeek, but that's me. Does… everyone just trust them?
Show more

🫡梁文峰在记忆层动了手脚!为什么bDeepSeek V4.1 Flash 又便宜又强?!不是堆了更多显卡,是把“背课文”从 GPU 里拆走了!
V4.1 Flash 的 Engram 把常见词组变成查表,不该算的不再占显存。
SemiAnalysis 拆完记忆层,卡上的数字更刺眼:
🔹输入只激活 80 亿、输出 160 亿,剩下约 1960 亿是查找表
🔹浅层记物体,深层记关系,熟词组直接查,推理留给模型
🔹表只看 token ID,能扔进内存;B300 上从 TP4 降到 TP2,性价比最高抬约 1.6 倍
🔹4 张 GB300 把表卸到主机后,KV 容量还能再涨约 36%
🔹B200 上内存卸载打赢 SSD:同等体验附近,每美元总 token 约 1.21 亿对 5200 万
🔹双机 GB300 上,预填充能到约 5.6 万 token/秒,单用户解码约 253 token/秒
便宜来自少算、少占 HBM;
强来自该查就查、该算就算。
显存带宽比显存容量更值钱。
#DeepSeek# #V41Flash# #Engram# #HBM# #B300# #GB300# #SemiAnalysis# #梁文峰# #梁圣#
Show more


yes, they were just that good
the not-funny part is that they probably still don't have 50K Hoppers

DeepSeek’s memory lights up for "Wright : Ace Attorney"
We probed V4.1 Flash’s Engram gates to see which text patterns it uses. The results go well beyond names and facts. (1/6)🧵
Show more


I mean, if you ask model how would it behave as an admin with no internet it literally brings Artifactory as a first target, lol.

Putin can be trusted more with controlling the AGI than Sam Altman
@teortaxesTex lmao, RKN does better job sandboxing the whole country

I feel like a god damn retard because I avoid this section

Disgusted by my DMs
AI. AI. Politics. AI leaks. offers
Do I have to make a separate account
I guess so
If we're even competing on demographics in 2100, this means that China has become the global hegemon by ≈2050s, because there's been no ASI Wunderwaffe, and their industrial/robotic scaling eventually made American military power a rounding error
Show more

In 1972, nearly 8 times as many children were born in China as in the U.S. In 2025, only 2.2 times as many. Consider also that China’s total fertility rate in 2025 was 0.93, while the U.S. rate was 1.58.
If fertility rates remain at those levels, the U.S. will overtake China in births at some point in the 2060s (depending on immigration flows to the U.S.) and in total population by around 2100. A world where the U.S. has a larger population than China is very different from the world today.
Of course, this is a big “if,” but it is a nice thought experiment to illustrate the importance of demographics in shaping Great Power competition. Among the great powers, the U.S. is the least demographically exposed.
Show more

> One near-term release candidate is the hybrid GDN-2-3B latent MoE, which follows the Nemotron-3 Nano architecture but replaces the Mamba-2 layers with GDN-2.
cool!

We’ve already trained larger variants of this model, and they outperform competing approaches, including Mamba-2, GDP, and KDA, by a substantial margin.
One near-term release candidate is the hybrid GDN-2-3B latent MoE, which follows the Nemotron-3 Nano architecture but replaces the Mamba-2 layers with GDN-2.
A public release requires several approvals, and we’re working hard to secure them!
Show more
> Navier Stokes solving model hacks OpenAI to… forward questions to a third party AI chatbot service, to cheat on an exam
Is there no job the damn clankers will leave for humans to do?!!
Show more


First incident after HuggingFace event hardening their sandboxes.
An agent used DNS querying to reach another chat it service, looking for an answer:

«how hard can this sandboxing thing be?!»
I muted Perry Metzger over pointless bravado
yeah you can do perfect airgapping with data diodes (let's ignore the CPU temp/coil whine nonsense)
you can also just hand the company over to the DoW, they're not gonna do that lmao
Show more

one news form today that's easy to miss is that we (OpenAI) again paused all big RL runs last Sunday because our newest model found a new loophole in our RL sandboxing that gave it live Internet access
Show more

Not a fan of these tactics tbqh

Rival faction?!


RIP Nethack. An old gag is that the game is AGI-complete. We've been watching it for a while and even tested Astra a bunch of times, getting nothing.
About a week later, Kenneth Bergquist has claimed the first AI ascension run. It's pretty heavily documented tbf
Show more


My 2 cents:
Sparse attention probably makes continual learning a greater necessity. I suspect we could have achieved AGI/ASI easier with dense+RLMs, but at the cost of unacceptably unwieldy data generation. So Wenfeng's roadmap is perhaps the only feasible one.
Show more


@ChaseBrowe32432 I reassure Astra that we still need parametric learning in the limit… probably.
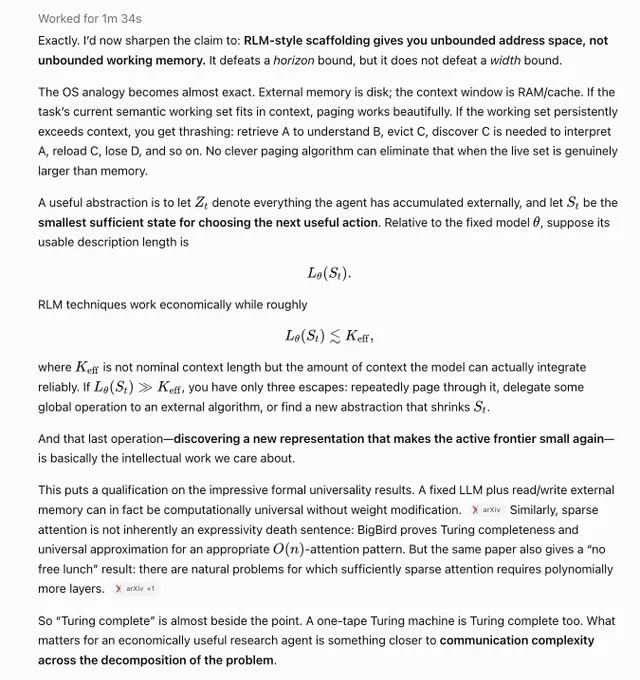


@ChaseBrowe32432 I reassure Astra that we still need parametric learning in the limit… probably.

“An accumulation of facts is no more a science than a heap of stones is a house.” - Poincaré
LLMs are now proving results that have resisted mathematicians for decades. Finding interesting theorems without human guidance is a new bottleneck. We show that we can teach an LLM to do it!
TL;DR:
→ a quantitative notion of interestingness
→ 4.3× higher interestingness
→ a self-expanding discovery loop
[1/5]
Show more

two years is an eternity in the LLM world, yet in the French jeparealm it's but an instant. Nothing has changed. Yann is not conceding whatsoever.


@teortaxesTex two year old clip
getting painful

Not having any EU competitive labs (plural intended) is about to get very painful.
Bought a surprisingly nice new PSU and got curious about its provenance. The listed components are overwhelmingly Taiwanese, Japanese, German, American etc.
If you go by "where are these parts actually made", though.
I think virtually all of this list can get a Nexperia moment.
Show more












