

Noctus
@noctus91
Benchmarking for fun | Ambassador @MistralAI |
Open to interesting projects & collaborations 📩
356 Following 1.3K Followers
Grok 4.7 is looking pretty rough.
26% on Terminal-Bench 4.0, way behind the top models. And across the other benchmarks, it doesn’t exactly look impressive either.

Well, they launched it, and as expected... Grok 4.7 is pretty terrible. Better luck next time

Grok 4.7 by @SpaceXAI might be dropping soon 👀
Leaked benchmarks put it up against Grok 4.6, GPT-5.6 Sol and Fable 5.1 across a bunch of tasks.

Seeing Jev all over my feed got me curious, so I tried the same idea with LFM2.5-VL on a driving video.
Just a small demo to test visual decision readouts from first token probabilities.
Not perfect and the latency is definitely there 😅
Show more

"The craft of writing code will disappear
yes there are Italian shoemakers around.
but look at your feet."


Most predictions I see are still way too conservative.
Here's mine

There should be a hackathon for this.
A competition to build the most useful and creative connectors for @Muse .
Would love to see what people build.
Opening access for developers to build Muse connectors. You bring the API -- Muse brings the agent, the browser, and the context of what the person actually wants. People reach your service just by asking for it, and their agent takes it from there.
New connectors are live today. Come build with us.
Show more

Just another day in AI.
And somehow, we’ve got another Chinese lab pushing a frontier level model.
@StepFun_ai Step 5 Preview is reportedly at 44 on Artificial Analysis, around Kimi K3 and Grok 4.6 territory.
Show more
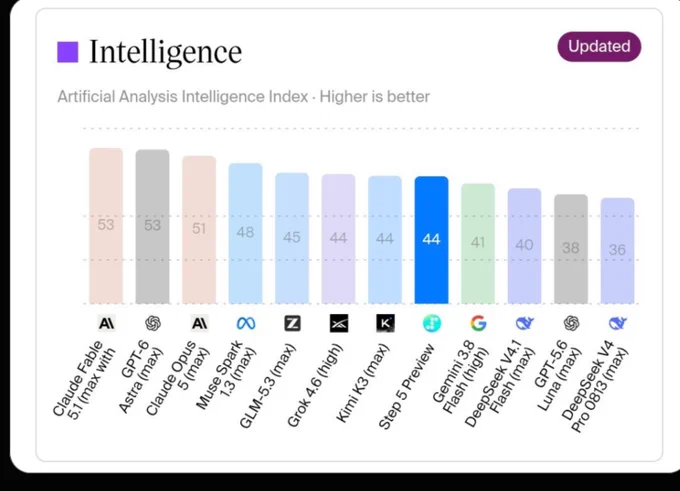

No official announcement yet, but Step Fun Step 5 Preview is up on AA:
44 on Intelligence Index
1M context window
$1.00 / 1M in
$2.70 / 1M out

Bonsai 2 27B by @PrismML is genuinely one of the few local models I can run reliably on my M3 Pro.
The coding and agentic performance is seriously good. It handles long tasks, tool calls, file operations, code execution, and vision/multimodal work without feeling like a stripped-down local model.
The main downside is speed.
I’m getting around 8.5–11 tok/s, but this is a 27B model running at 1-bit locally. Getting this level of capability on-device at that size is pretty impressive.
Show more


Today, we’re announcing Ternary Bonsai 2 27B.
Based on Qwen3.8 27B, Bonsai 2 27B is 9x smaller than its full-precision counterpart while retaining 98.2% of its aggregate benchmark performance.
Two months after the first Bonsai 27B release, the biggest change is quality. The footprint remains 5.9 GB, but the gap to full precision has narrowed materially, with particularly strong gains in agentic coding, multimodal reasoning, and long-horizon tool use.
Ternary Bonsai 2 27B is available today under Apache 2.0.
Show more

We basically got a Claude Opus 4.6-level model that can run in 8GB of RAM.
Bonsai 2 27B by @PrismML is just 5.9GB and reportedly retains 98%+ of the base model’s performance.
Show more

Today, we’re announcing Ternary Bonsai 2 27B.
Based on Qwen3.8 27B, Bonsai 2 27B is 9x smaller than its full-precision counterpart while retaining 98.2% of its aggregate benchmark performance.
Two months after the first Bonsai 27B release, the biggest change is quality. The footprint remains 5.9 GB, but the gap to full precision has narrowed materially, with particularly strong gains in agentic coding, multimodal reasoning, and long-horizon tool use.
Ternary Bonsai 2 27B is available today under Apache 2.0.
Show more
One of the clearest examples of what model specialization can buy you.
At 2.6B and 1.2B parameters, these models are also small enough to run locally on mobile devices.


In a new article published today on the cover of @CellCellPress, we obtained Liquid Foundation Model instances that establish state-of-the-art performance on biological longevity tasks, outperforming the best frontier models such as Gemini-3.1-Pro, GPT-5, and Claude Opus.
In partnership with @InSilicoMeds, we built and released:
> A comprehensive eval suite of 17 biological longevity tasks (i.e., LongevityBench), to assess whether a general-purpose language model can interpret aging data spanning clinical records, DNA methylation, transcriptomics, plasma proteomics, and genetic evidence.
> LFM2-1.2B-Longevity and LFM2-2.6B-Longevity: two compact models specialized for interpreting structured aging data across these tasks.
These results are important! 🧵
Show more

My guess for tomorrow: either the LFM 3 series or the longevity model.

announcing something important tomorrow! 🌊
Mistral partners with Mozilla to bring its AI models to Firefox.
@MistralAI models will power Firefox new Smart Window AI features, with the partnership initially rolling out across France and North America.
Show more
Today, we are announcing a partnership with @mozilla to bring privacy, control and choice to people using AI to browse online. 🦊🐈
Today, we are announcing a partnership with @mozilla to bring privacy, control and choice to people using AI to browse online. 🦊🐈
It’s honestly absurd that Meta Muse Spark 1.3 and other meta models are available for free on OpenCode and other coding plans.
while @AIatMeta own coding plan doesn’t even have a free tier.
Show more

Zuck’s redemption arc needs to be studied.

Last month I wrote about how we can build a positive and safe future for everyone:
Every lab has the responsibility and incentive to move at the pace required to train its models safely, and the ability to take its own actions to ensure that happens.
The reality is:
- People won't want to use agents that are misaligned with them and that don't do what they ask, so labs have a strong natural incentive to make their models more aligned.
There is a lot of debate about slowing progress on capabilities until alignment catches up. My view is that trust and alignment are quickly becoming the most important capabilities that will differentiate agents and models. Any lab that doesn't focus on alignment will fall behind.
- Labs face significant liability if their models cause harm, so they have a strong incentive to prevent this as well.
Meta delayed shipping Muse for several months to focus on safety and security. We didn't call for everyone else to do this before we would. We just did it as part of our day-to-day work because it was clearly the right thing for people and for us. I'm proud of the security foundations we've built.
- Engaging independent evaluators and advisors is industry best practice. MSL already does this today in several areas because it helps produce better work. Other labs can just do this too. In general, it would be helpful for there to be a larger and more diverse ecosystem of evaluators.
- Committing the significant majority of compute towards serving people rather than racing towards recursive self-improvement is one of the best ways to ensure we develop this technology safely. Meta has made this commitment and other labs can do this as well.
I believe the key to building a positive future for everyone is maintaining the right balance of power. This is within our power to do.
Show more
Honestly, I was tempted to buy the CrofAI coding plan, but the price just felt too cheap for the models they were offering.
The CrofAI situation is a good reminder to be a little more careful with these plans.
Glad I’ve only been using opencode and commandcode.
Show more
I posted asking how people are actually using @Muse.
The replies gave me a pretty good idea of where people are already finding value:
1) Personal assistant / daily life
2) Job hunting + applications
3) Work & business tasks
4) Building websites + content
5) Automating all the annoying busywork
And honestly, we’re still pretty early for normies.
Meta might be able to crack the B2C market for AI agents.
Show more
For those using @Muse what’s the one thing you’ve found yourself using it for the most?
Personal projects, work, business, agency, content, or something completely unexpected?
Curious to see what people are actually doing with it.
Show more
This is actually so based coming from Zuck lmao
Did not expect him to be the one pushing this hard for accelerating the frontier.


The internet botnet part is wild 💀.
Didn’t expect that part of Dario’s post to be the one that stuck with me.


We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here:
Show more

For those using @Muse what’s the one thing you’ve found yourself using it for the most?
Personal projects, work, business, agency, content, or something completely unexpected?
Curious to see what people are actually doing with it.
Show more
I really hope the @AIatMeta team lets more people off the Muse AI waitlist soon.


what are your top muse feature requests?












