

Przemek Chojecki | PC
@prz_chojecki
Research-level Math Data + hard STEM & coding RL tasks for LLMs @ PhD in mathematics.
373 Following 15.3K Followers
I've tested Mistral Large 4 on our STEMBench - 20 problems for each of 6 domains - and it got a pretty nice score.
It's definitely capable of doing original research across domains and is pretty even. Great win for the European AI!
Show more

What an incredible set of results!
Quasi-Riemann Hypothesis and Hodge Conjecture for abelian varieties are probably my favorite ones, but there's also so many smaller gems.
I really like Fontaine-Mazur modularity at prime 2 and modularity over imaginary quadratic fields: first proper AI exploration in the Langlands program.
It will take mathematical community months to properly digest everything, but one thing is clear - there are no subdomains safe from AI now.
Show more

We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
Show more

Le Chaton Fat has arrived!
Testing it on ErdosBench and STEMBench right now. Reporting back soon on Le Chonk.
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
Show more

Another amazing result (towards P=NP?), and a very interesting release scheme:
- Anthropic finds the proof together with a Lean formalization (so they know it's correct);
- They contact the experts - the authors - offer compensation and access to Claude for a help with a write-up.
Tbh, this looks like one of the good approaches to AI-academia collaboration.
Show more


We're testing our new benchmark. STEMBench is a set of 120 research-level problems from 6 domains - Biology, Chemistry, Physics, Astronomy, Earth science, Engineering - 20 problems per domain.
Very cool to see that our initial calibration works well and the benchmark is far from saturated (max score is 4 per domain).
Detailed testing with a dedicated website incoming. Interestingly, it seems like physics will be next after mathematics. Math is not included in this benchmark, we have ErdosBench for that.
DM me if you want to see your model tested.
Show more

Big if true.
No comment on the proof, as it's outside of my expertise and 140 pages long, but this looks like how things might look for the foreseeable future.
Authors spent 2 months exploring 100+ approaches with various SOTA models: GPT-6 Astra, GPT-5.6 Sol, Claude Fable 5 and Fable 5.1.
Monte Carlo of ideas.
Show more


Riemann Hypothesis proof as a (Lean)Doom play through.

upping my (Lean)DOOM
i got curious about math proofs and Lean formalization, found out you can do general programming in lean, and i wanted to learn more so i did the obvious thing. (Lean)DOOM is entirely written in lean, and has presently a couple proofs where they make sense
Show more

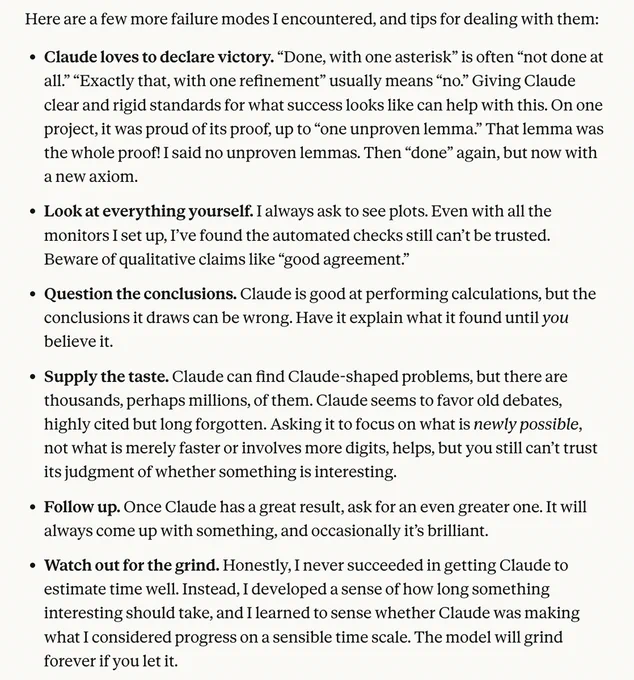
Claude-shaped Science blogpost has really great failure modes of Claude, that applies to other LLMs too.
Blogpost:
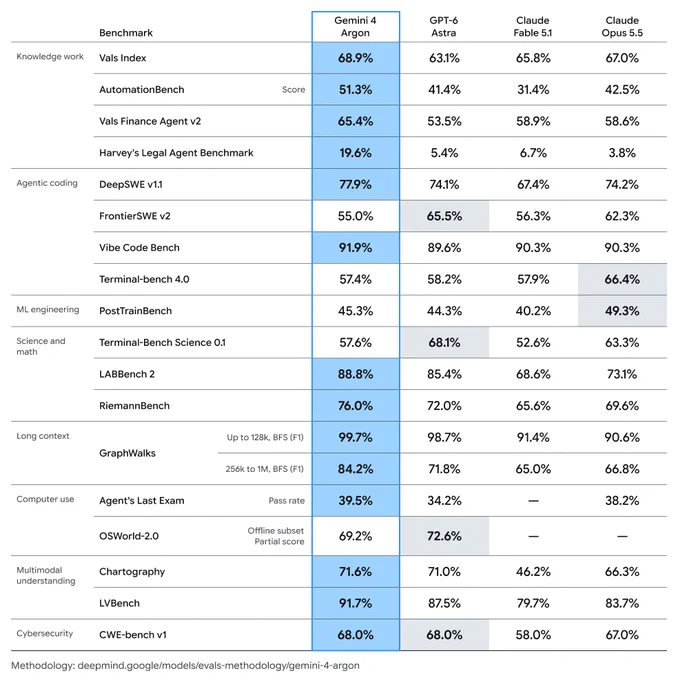
Exciting! Can't wait to test it on our ErdosBench and some open math problems.

Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Show more
I've run these new results through GPT-6 Astra + Opus 5.5 and got even more counterexamples in families that strengthen Landreman’s results.
The automated paper is here:
Figure by Opus 5.5 (+some calculations), final write-up by GPT-6 Astra. No Lean verification, just adversial LLM check-up.
Show more


A 59-year-old conjecture in fusion physics just fell.
Harold Grad (1967): smooth 3D plasma equilibria can't exist unless pressure is constant or there's symmetry.
This week: 3 families of counterexamples. 2 independent papers, posted a day apart. Two found with GPT-6 Astra.
Huge for stellarators.
Show more

"we ask them to stop testing advanced mathematical problems on proprietary models"
That won't happen.
As a former academic mathematician I can understand where this set of recommendations is coming from: it's basically trying to have this new entity "AI labs" fit into the structure of academia.
But what will happen is academia will be made to fit into the AI age.
One of the things missing from this text is "AI labs" are just a small part of the incoming wave. Already most of the AI generated results are coming from amateurs or former mathematicians who enjoy thinking about particular problems or just like testing LLMs on math.
More useful would be a set of recommendations for human mathematicians in the age of AI.
Show more


The advisory group on mathematics and artificial intelligence has just published a set of recommendations concerning the responsible release of mathematical results generated by AI companies using internal models. 1/3
Show more

Old Problems, New Proofs
Very cool initiative described by Terence Tao on his blog. A math hackathon to find new proofs of known statements, better explanations and generally help deepen human understanding of various pieces of mathematics.
Show more


The @Caltech community and SAIR are redesigning and co-organizing Mathathon: Old Problems, New Proofs.
Explore alternative proofs and clearer explanations, using AI to deepen human understanding.
More on our co-founder Terence Tao’s blog:
Show more

This is the kind of AI use I'm excited for.
Better understanding of the world, new physics, new engineering, new chemistry.
A 59-year-old conjecture in fusion physics just fell.
Harold Grad (1967): smooth 3D plasma equilibria can't exist unless pressure is constant or there's symmetry.
This week: 3 families of counterexamples. 2 independent papers, posted a day apart. Two found with GPT-6 Astra.
Huge for stellarators.
Show more
AI slopXiV is here and it's a good thing!

Hello, world! There is a new repository for works in math and TCS: now in public beta. Please try it out and submit something! We welcome your feedback while we build and improve it.
Show more

Top 10 models judged by their mathematical capabilities.
I used Opus 5.5 to make a heatmap table out of our ErdosBench eval.
See full leaderboard at

The era of personal LLMs is here.
Current generation of SOTA models is great at helping you train your own model.

A Severe Misalignment of AI in Mathematics
New blog post by Terry Tao and a new anti-AI declaration signed by 25 Fields medallists.
I'm not sure what the intendent effect should be. The ban of AI use in mathematics and science in general because of "math community"?
Fortunately math community is broader than just math academia, and thanks to AI, booming like never before.
Also this "mass production of true/false statements" is such a wrong description. As if there's no proofs by AI that you can study, deepen your knowledge, build upon, engage. The "AI slop" is still better written than what 90% of mathematicians write.
Mathematics doesn't belong to math academia. It is a tool to understand the world and help other domains with necessary tooling. AI boosts the understanding and engages wider community.
Swan song of academia.
Link:
Show more

data is the moat

This is notable. DeepSeek, a lab usually first to pioneer novel algorithms and architectures, is saying that at this point, the ROI of improving data quality far exceeds that of working on novel post-training algorithms.
I think this has already been true for some time for non-lab practitioners. If you're doing llm post-training, 80% of your effort should go into looking at your data.
This means:
- Hiring experts to dig through your RL tasks
- Sifting through rollouts and sft data by hand to remove suspicious samples. Make sure all tasks are actually passable.
- Making sure your data is diverse in both difficulty and category.
Show more

Even on $200 Pro plan there are limits to Astra Pro now.


To make sure our current users have an incredible experience and continued access to Astra, we are going to pause subscriptions to our $200 Pro plan. These put the most strain on our systems and we wanted to take the smallest step that allows us to continue giving the broadest access possible. All other plans and the api remain available.
There is no impact to existing accounts and we are working on adding more capacity as fast as we can. Thanks!
Show more
Caltech math undergrads have been saved from AI!
Phew, that was close!
Academia status quo continues for another day.

Thank you for sparing math academia the terror of undergrads getting access to the tool that's increasingly essential to modern math research. We can rest assured they'll all spend the next 6 years of their lives writing pencil and proofs and everything will go back to normal.
Show more









