Search results for OpenSourceAI
OpenSourceAI community
One keyword maps to one global community path.
People
Not Found
Tweets including OpenSourceAI

The #OpenSourceAIWeek# lineup is loading. Is your event on it? ⏳
Join the Bay Area celebration, October 16-25, with flagship events #PyTorchCon# North America, October 20-21, and #AGNTCon# + #MCPCon# North America, October 22-23.
Submit your event by October 15:
Show more

🚨 Final days to join #OpenSourceAIWeek#!
Submit your Bay Area open source AI event by October 15. The week runs October 16-25, featuring flagship events #PyTorchCon# and #AGNTCon# + #MCPCon# North America in San Jose.
Learn more & add your event by Oct 15:
Show more

Planning a Bay Area meetup, hackathon, showcase, or open source AI gathering?
Make it part of #OpenSourceAIWeek#, October 16-25, anchored by #PyTorchCon# North America and #AGNTCon# + #MCPCon# North America in San Jose.
Submit by October 15:
Show more


I’ll be at The Curve in Berkeley this weekend.
If you’re going too, DM me. Would be great to connect at the conference and talk about anything from AI policy and AI safety research to protecting the open frontier.
Hope to see some of you there.
#TheCurve# #AIPolicy# #OpenSourceAI#
Show more


📢 Official Announcement: Qwen Partners with Fireworks AI to Accelerate Access to Qwen Family Models
We are pleased to announce a strategic partnership between Qwen and Fireworks AI to deliver optimized, production-ready deployment of Qwen's closed weights models via the Fireworks Platform. @FireworksAI_HQ
This collaboration empowers developers and enterprises to:
✅ Deploy Qwen models with lower latency and reduced fine tuning and inference costs
✅ Leverage enterprise-grade reliability, security, and scalability
✅ Integrate seamlessly into modern AI workflows
🔹 Get started with Qwen on Fireworks:
#Qwen# #FireworksAI# #OpenSourceAI# #LLM# #AIInfrastructure# #ResponsibleAI# #DeveloperCommunity#
Show more
We’re excited to welcome Mooncake to the PyTorch Ecosystem!
Mooncake is designed to solve the “memory wall” in LLM serving. By integrating Mooncake’s high performance KVCache transfer and storage capabilities with PyTorch native inference engines like SGLang, vLLM, and TensorRT-LLM, it unlocks new levels of throughput and scalability for large language model deployments.
Mooncake enables prefill decode disaggregation, global KVCache reuse, elastic expert parallelism, and serves as a fault tolerant PyTorch distributed backend.
🔗
#PyTorch# #OpenSourceAI# #LLM# #AIInfrastructure#
Show more


When AI Automates the Craft You Loved
DeepSeek engineer Liu Shengyu’s viral article, "I Had to Bury My Talent in Yesterday", is not simply about losing a job.
It captures something more personal: AI may preserve an expert’s value while taking away the part of the work that gave it meaning.
Zhihu contributor BBuf sees a warning about craftsmanship, how expertise is formed, and who controls frontier intelligence.
1️⃣ From craftsperson to machine operator
Kernel optimization was deeply hands-on.
Engineers learned Hopper and Blackwell, arranged shared memory, tuned warps, inspected PTX and SASS, then profiled repeatedly to push throughput higher.
The process itself was rewarding. But the role is shifting from weaving the sweater to supervising the knitting machine.
Experience still matters. Experts know which designs and failure modes to watch. Yet the activity they loved is no longer what production demands.
2️⃣ Kernels are ideal work for agents
An agent can read CUDA, PTX, and SASS, identify stalls, propose an optimization, compile it, run benchmarks, fail, and try again.
A human explores only a few paths at once. Fast models paired with tens or hundreds of agents can search far more broadly.
BBuf’s conclusion is blunt: whenever work supports repeated, meaningful trial and error, humans may struggle to compete.
The same pattern could extend from kernels to algorithms and mathematics.
3️⃣ The expertise paradox
If beginners let AI write everything from day one, where will senior judgment come from?
Experienced engineers may remain better at directing agents because they understand hardware and hidden trade-offs.
But the traditional path for acquiring that intuition may disappear as the underlying craft is automated.
The risk is not only fewer jobs. It is losing the apprenticeship process that once created experts.
4️⃣ Intelligence is also a distribution problem
If frontier models become the main engine of technical work, who controls the compute behind them?
Open weights do not mean everyone possesses frontier intelligence.
BBuf argues that unequal access to compute could become unequal access to effective intelligence.
The open-versus-closed debate is not merely about licenses. It is also about who can afford to use powerful intelligence at scale.
✅ What may be buried
AI may not eliminate experts first. It may turn them into supervisors of systems that perform the craft they once loved.
The harder question is whether we can preserve human judgment and the joy of making things while embracing tools that are faster than us.
🔗 Full analysis:
#DeepSeek# #CUDA# #AIInfra# #AIAgents# #FutureOfWork# #OpenSourceAI#
Show more


🔍 A DeepSeek Harness Plugin That Lets AI Explain the Agent's Own Trace
Less than two weeks after DeepSeek Harness entered developer preview, its plugin ecosystem is already taking shape.
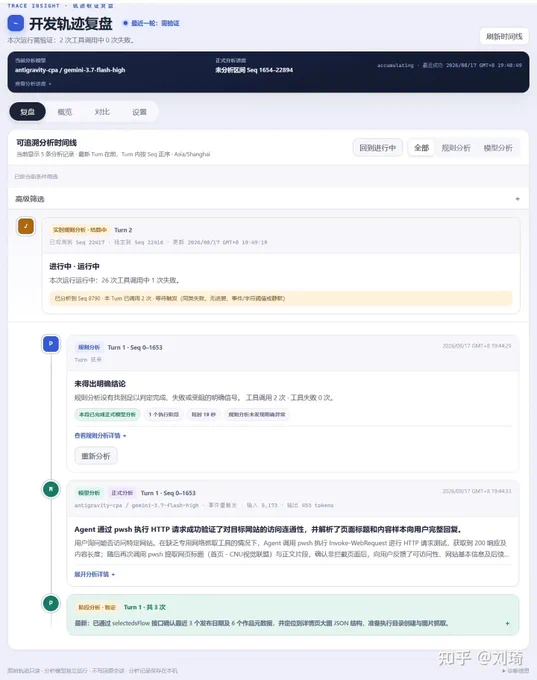
Zhihu contributor 刘琦 built DSH Trace Insight, a focused plugin for one of the most important but overlooked parts of Agent engineering: understanding what an Agent actually did.
1️⃣ DeepSeek Harness exposes the process
Many Agent harnesses behave like black boxes. Users provide a task, wait, and eventually receive an answer.
DeepSeek Harness is different. Its trace records tool calls, execution steps, failures, retries, and other intermediate activity.
This makes the Agent more transparent, but the raw trace is stored as a large JSONL file. Even with filtering, it is difficult for a human to read and reconstruct the full process.
The author's idea was straightforward:
If the trace is too complicated for humans, let another AI interpret it.
2️⃣ Turn raw traces into readable analysis
DSH Trace Insight adds a side panel that asks an AI model to explain the running trace.
It can summarize:
🔹 What the Agent is doing
🔹 Which methods and tools it used
🔹 Where errors or retries occurred
🔹 Whether any risky actions appeared
🔹 What lessons can be extracted from the run
Instead of waiting beside an opaque progress indicator, users can inspect how the task is progressing, whether the approach is working, and how risky the current behavior looks.
The goal is not to add another capability to the executing Agent. It is to add an interpretability layer around the Agent's behavior.
3️⃣ Use two models for cross-checking
When a suspicious step appears, the plugin can send the same trace to two different AI models and compare their analyses.
This is useful because trace interpretation is still a model-generated judgment. A second model can expose disagreements, missed risks, or different readings of the same tool call.
The plugin can also organize detected issues into a compact list for manual review.
That creates a useful three-layer workflow:
Agent execution → AI trace analysis → human review
It is a lightweight approach to Agent observability without requiring users to inspect thousands of raw log lines.
4️⃣ Installation is intentionally simple
The plugin is open source under the MIT license:
Users can ask their Agent to install it directly with:
Please install this DSH plugin:
The current version is designed for the native DeepSeek Harness Web UI.
Using it inside third-party desktop wrappers may require additional development, since those clients may package or modify the original Web UI differently.
5️⃣ DeepSeek Harness can become a model worker behind Codex
The author also suggests an interesting setup for people who do not use DeepSeek Harness as their primary Agent interface.
Open the native DSH Web UI inside Codex's browser. Codex remains the main harness, while it operates DeepSeek Harness and the models connected to it.
This creates a layered workflow:
🔹 Codex handles planning and orchestration.
🔹 Lower-cost non-GPT models inside DSH perform lightweight tasks or code inspection.
🔹 DSH Trace Insight exposes how those models executed the work.
🔹 Codex can discuss the results with DSH across multiple rounds, then send the final conclusion to another strong model for an additional review.
Compared with assigning every subtask to an expensive model, this setup can reduce cost. Compared with calling another CLI tool blindly, it provides much better visibility into execution.
✅ The real value is observability
DSH Trace Insight does one thing: it translates an Agent's raw execution history into something humans can understand.
That simplicity is its strength.
As Agents begin running longer tasks with more tools and greater autonomy, the important question is no longer just whether they produced the correct answer.
We also need to know how they reached it, what failed along the way, and whether they crossed any risky boundaries.
🔗 Full Reading:
#DeepSeek# #DeepSeekHarness# #AIAgents# #AgentObservability# #OpenSourceAI# #AIEngineering#
Show more



🧩 Kimi K3’s MoE and Attention Are Built Around Trade-offs, Not Tricks
Kimi K3’s open release has drawn attention to its scale. But its architecture tells a more useful story: the hardest part of scaling is keeping quality, efficiency, and stability in balance.
Zhihu contributor 苏剑林 @Jianlin_S explains the design logic behind two core components: Stable LatentMoE and K3’s hybrid attention.
At a high level:
K3 = KDA + MLA + Stable LatentMoE + AttnRes
1️⃣ Stable LatentMoE: more experts at similar cost
LatentMoE compresses each token into a smaller latent space before routing it to experts, then projects the result back to the full hidden dimension.
This reduces expert computation and communication. The saved budget can support more, narrower experts without greatly increasing training or inference cost.
But the longer projection chain also magnifies numerical instability. K3 introduces three fixes.
🔹 SiTU-GLU softly caps extreme activations in both branches of the expert network. Compared with hard clipping, soft capping preserves smoother optimization.
🔹 RMSNorm is placed before the final up-projection. It stabilizes training and helps balance routed experts against shared experts.
🔹 Quantile Balancing replaces the previous load-balancing update, which became unreliable as the expert pool grew. It approximates global routing quantiles with histograms, allowing efficient aggregation across machines.
The broader lesson is clear: scaling MoE is not just about adding experts. Routing, activation ranges, normalization, and distributed communication must scale with them.
2️⃣ Why K3 still uses MLA
Some newer models have moved away from MLA, partly because speculative decoding changes the inference trade-off.
MLA keeps KV Cache small and remains highly competitive under fixed training and memory budgets. But its decoding path is relatively compute-heavy, leaving less room for Multi-Token Prediction to trade extra computation for speed.
Other attention designs simply move the bottleneck:
🔹 Smaller designs may reduce computation but lose quality or require a larger KV Cache.
🔹 Larger designs can recover quality, but increase training and prefill costs.
An ideal replacement would preserve quality, reduce KV Cache, lower decoding compute, and cost no more during training or prefill.
No simple design currently satisfies all four conditions.
K3 therefore keeps MLA and combines it with KDA. The linear-attention layers handle most long-context processing efficiently, while MLA preserves full-attention capacity where it matters.
3️⃣ “Abandoning MLA” is not so simple
Architectures that appear to replace MLA may still retain its core intuition.
For example, a wide MQA design with shared K and V resembles MLA’s decoding form. Sparsity and compression can then reduce its compute and cache costs.
This can work, but it introduces more infrastructure complexity.
So the current debate is less about whether MLA is obsolete. It is about which combination of full, linear, sparse, and compressed attention offers the best system-level trade-off.
4️⃣ Why K3 can remove RoPE
K3 removes RoPE from its MLA layers.
That would hurt a pure-MLA model. But K3 is a hybrid of KDA and MLA.
KDA’s DeltaNet-style updates already introduce an implicit positional transformation. In this sense, KDA provides something similar to a generalized form of RoPE for the full network.
Adding explicit RoPE back produced little difference, so K3 followed the simpler design.
K3 is not truly position-free. Its positional structure is partly carried by KDA instead of an explicit embedding.
⚙ The real architecture lesson
None of these choices is especially flashy in isolation.
Stable LatentMoE controls the numerical and routing problems created by more experts. KDA and MLA divide long-context work according to their strengths. NoPE removes a redundant component only after the hybrid architecture makes it unnecessary.
K3’s main design principle is therefore not novelty for its own sake.
Every architectural change must justify itself across quality, efficiency, and stability.
🔗 Full reading:
📖Blog post:
#KimiK3# #MoE# #Attention# #LLM# #AIInfra# #OpenSourceAI#
Show more

Day 2 is done, and that’s a wrap on #PyTorchConferenceEU# 🇫🇷🔥
A great close to two excellent days at Station F: deep technical content, practical engineering, open collaboration, and an ecosystem with real momentum.
This morning I had the chance to deliver the @PyTorch Foundation CTO keynote, focused on ecosystem growth, new working groups, certification, and what it takes to make open source AI easier to build, govern, and scale (OpenMVG).
Big Day 2 announcement 🚨
@HuggingFace Safetensors is joining the PyTorch Foundation as a hosted project.
That is a meaningful step forward for secure model distribution and trusted AI deployment. (PyTorch)
Also great to see keynotes and sessions featuring:
• Léonard Hussenot from @GoogleDeepMind's compelling talk on Gemma 4
Edward Yang (@Meta) on PyTorch updates
• @LysandreJik (@huggingface) on the Hub as infrastructure and safe, performant model distribution
• an outstanding mix of speakers and contributors from @AMD, @RedHat, @NVIDIA, @Google, @IBM, and @LightningAI (PyTorch Conference 2026)
Thank you to everyone who made the first PyTorch Conference Europe such a strong debut.
The ecosystem is growing. The Foundation is growing. And the community is building what’s next. 🚀
#PyTorch# #OpenSourceAI# #Safetensors# #huggingface#
Show more


