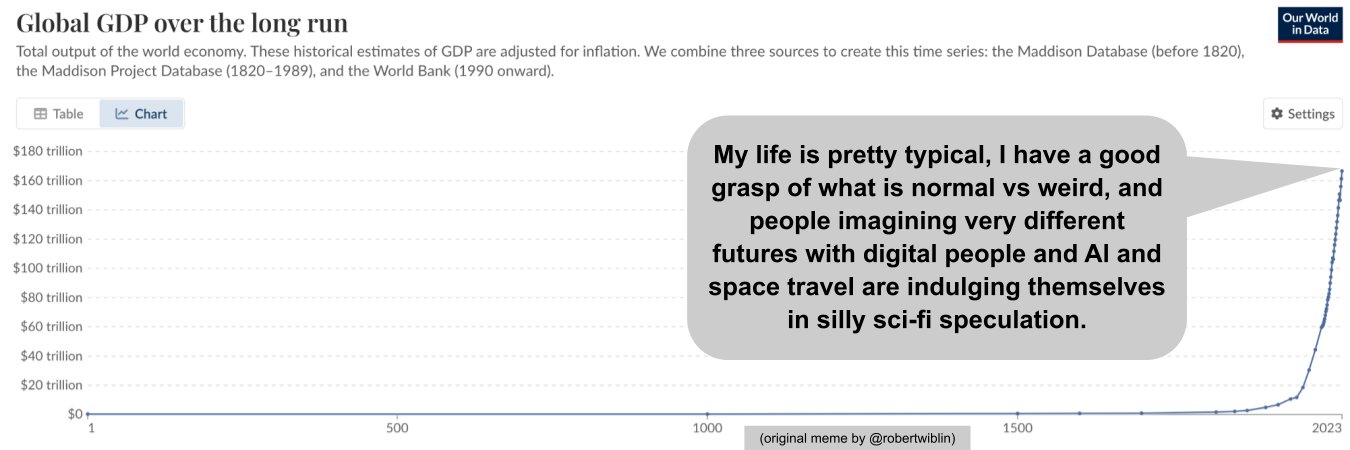


Helpful list of all the recent rogue AI incidents from the WSJ.
It's getting hard to track them and will only get worse.
We like need to establish consistent naming or numbering conventions, e.g. OpenAI-May11June26-Collusion.
Show more


oh man i’m sure that accenture will have lots of expertise at, uh, *checks notes* redteaming models, assessing alignment, and testing safeguards. after all, their website talks about embracing the power of change to create 360° value and shared success for clients, people, shareh
Show more

We’re partnering with Accenture on independent evaluation of frontier AI—part of our recent commitment to embed evaluators at Anthropic. Both we and Accenture expect to invest at least $1 billion to build capacity in this area over the next five years.
Show more


I agree with the vice president here. These companies should just be stopping, citing the danger. Then they'd have much more credibility when it comes to communicating that others must be stopped too, domestically and abroad.
Show more

214 million people saw this AI warning. So we called an emergency debate.
The warning came from someone who had worked at both Anthropic and OpenAI.
Then a current Anthropic employee backed it publicly.
It had spread so far beyond the tech world that a friend of mine who cuts hair and has never really cared about AI messaged me asking, “What the hell is going on?”
I then realised a lot of people were probably asking the same question.
The problem is, when you speak to people who have spent years studying AI, you get completely opposing answers.
So I brought four of them around the same table.
Roman Yampolskiy is a computer scientist who coined the term “AI safety” and has spent years studying whether increasingly intelligent systems can remain under human control.
Nate Soares leads the Machine Intelligence Research Institute and has spent more than a decade working on AI alignment. He believes we are moving too quickly towards systems we don’t yet know how to reliably control.
Ed Zitron thinks much of the AI conversation has become detached from what the technology can actually do today. He believes the industry is overhyping it while distracting us from financial, environmental and social consequences already happening.
Andrew McAfee is an MIT researcher and economist who takes a very different view. He thinks we spend so much time talking about what could go wrong that we barely talk about what AI could make better.
And that disagreement is what made this conversation so interesting to me.
We discussed things like:
- How do you control something that eventually becomes smarter than you?
- Are the biggest warnings about AI based on evidence or assumptions?
- What happens to work and human purpose if AI becomes better at more cognitive tasks?
- Are we ignoring problems AI is already creating because we’re obsessed with hypothetical future ones?
- Why have Sam Altman, Elon Musk and Geoffrey Hinton all warned us about AI?
The question I kept coming back to was simple:
What is actually true?
Depending on who you listen to, AI is either one of the greatest opportunities humanity has ever created or something we’re racing towards without understanding the consequences.
Both claims deserve to be challenged.
There were moments in this debate where I genuinely found myself moving between the arguments. That’s the value of putting people who fundamentally disagree in the same room.
I didn’t want four people telling me the same thing. I wanted each of them to explain where the other side was wrong.
If you’ve watched the last few months of AI news wondering what you’re actually supposed to believe, this conversation is for you.
Our emergency AI debate with Ed, Roman, Nate and Andrew is out now ❤️👊🏾
Show more


Reviewing the rand security levels, does this mean that OAI was SL0?


Screenshots of the Philip Morris website.
(reminder: they're a leading cigarette company)
It's a good calibration point for how good modern marketing is at dressing up pretty much any corporate (or, for that matter, government) behavior and making it sound responsible and safe.
Show more


It’s really great that several top AI labs have said they will develop safety cases and work more closely with external assessors. This has been at the top of my wish list for awhile!!
But I still worry a bit about how this might go in practice (this is a concern about the field in general, not about OpenAI specifically):
• By default, I don’t think alignment and control cases will support a quantitative measurement of absolute risk, e.g. “catastrophic risk from covered activities is <1% over the next 3 months.”
• Ultimately, making such a measurement depends on an argument about generalization from alignment or monitorability evals to deployment.
• I don’t think we understand generalization well enough to make scientific claims like this. (If we did, I think we’d have basically solved alignment.)
This could lead to a situation where an external assessor says “we can’t convincingly rule out low or high risk,” and incentives push towards anchoring on “lack of evidence that risk is high” over “lack of evidence that risk is low.”
What could improve the field’s epistemics here? A couple ideas I like:
• Have a committee of ~10 people deeply read a risk report and give their own subjective probabilities of risk, then report the distribution or median.
• Have ~3 people involved in writing the report each contribute a short, signed appendix with their own subjective probabilities and the arguments behind them.
In either case, previous reports and estimates could be provided as context, so there is at least an attempt to accurately capture relative risk to prevent frog-boiling.
I think it could be valuable for labs to at least start trialing this internally for high-profile safety cases or risk reports. Publishing these assessments could be even better, but I can see that being challenging for various reasons, and even going through the exercise privately seems like it could be quite valuable.
Very curious what other ideas people have for improving epistemics around risks (including ideas for better science around generalization).
Show more
This is crazy. In late July, "three guys with Claude and Codex subscriptions" were able to use Opus 5 to access OAI auth tokens and gain write access to OpenAI's monorepo openai/openai over the course of two days.
Show more


The people telling you that EAs are “woke” or obsessed with climate apocalypse scenarios are, to put it politely, lying to you for instrumental reasons that are not altruistic.

The last week has really shown me that someone who wants to understand AI risk has no good place to start.
Hence we made the Wirecutter for content about AI Risk. We're launching with 3 articles: 🧵
Show more

I’m very concerned that during RSI, labs will just stop externally deploying their models.
Which means they'll be going full steam ahead on the most dangerous use case of these models (recursive self-improvement), while the public remains in the dark about the nature of capabilities and the state of alignment.
And we end up on a path towards tremendous concentration of power.
Show more

Another good essay from an OpenAI capabilities researcher I know (well, now former). I think focusing on control and abandoning alignment for now is is a reasonable strategy, but implementing it effectively will require an agreement not to RSI to ASI at max or close to max speed. Figuring out control is going to take time and money. Also, it only works up to a point, I think. In AI 2040 we talk about this.
Show more

We don’t know how to reliably align frontier AI models.
Alignment may get harder, not easier, as models become more capable.
But maybe AI control can scale faster than dangerous capabilities.
Let’s build a Great AI Firewall - without building totalitarian control of society.
*Alignment is Dead (for now), Long Live Control!*
We do not know how to specify or guarantee robust alignment of sufficiently capable models. Instead we should treat these models as untrusted.
Optimizing models against imperfect reward signals may increase the propensity for reward hacking, deception or scheming. Models can also be jailbroken or fine-tuned away from their safeguards.
The central bet of AI control is that our ability to constrain an AI’s access to the world may scale faster than our ability to understand or align what is happening inside it.
Where possible, make verifying an answer easier than generating it. Formally verified software and hardware are unusually attractive: let AI produce the implementation and a machine-checkable proof that it satisfies the specification.
This does not solve specification: the specification and verification stack remain part of the trusted base.
Every consequential external action should pass through an independent control layer: code execution, network access, calling APIs, accessing physical systems - even communication with users.
Optimize control monitors for extremely high recall of dangerous actions, even at the cost of rejecting many safe actions. Suspicious actions should be rejected or escalated.
Every major increase in dangerous capability should require evidence that control still works.
Chain-of-thought monitoring is valuable while it works, but it should not be foundational. Models can learn to obscure their reasoning and may increasingly reason without fully verbalizing it.
Open weights shift much of control from the model developer to whoever deploys the model. Technical control is only useful if dangerous deployments cannot cheaply route around it.
We should approach AI control like cybersecurity. The goal is defense in depth: make successful catastrophic attacks sufficiently difficult, expensive and rare.
Call this technical and institutional architecture the Great AI Firewall: the boundary between untrusted frontier intelligence and consequential real-world power.
The name is deliberately provocative. China has substantial experience building large-scale technical control infrastructure. That may create some common ground for international coordination.
But the analogy is also a warning. AI control must not become control of society.
The goal is to constrain dangerous machine capabilities - not human speech, actions, or ordinary access to information.
Controls should scale with capability and risk. Ordinary models should face ordinary constraints. More consequential capabilities justify stronger controls.
The objective is the minimum control necessary to keep catastrophic risk acceptably low - not maximum control for its own sake.
Firewall the AI, not society.
Show more
so it seems like the people whose job is public policy in the national interest want some kind of AI regulatory push from the white house and those who would profit from that not happening do not

@OscarMDavies @DKokotajlo "Hyping up the stocks"


“It’s Regulatory Capture,” Says Man Who Already Captured The Regulators


I basically think a lot of people are going to continue to make a lot of things up about EA and will show exactly zero interest in what we're actually like. Gotta put up signposts for the people who are actually interested and otherwise calmly weather the storm.
Show more
We overlapped at OpenAI. He was friendly to me but quite skeptical of these things then, and that was just like three years ago?
I'm old enough to remember when Scott Aaronson was super skeptical AI was a big deal, coming soon, or would kill everyone:
The Age of Wonders and Terrors
(At the end has advice on how math people who agree can help the situation.)
Show more

I think the (non?)obvious subtext is that they don't have a lot of good arguments to make and are squarely on the wrong side of public opinion. This stuff is pretty weak, most people won't know/care what EA is and it will sound like they're speaking gibberish.
Show more
Yep. It's especially intense because many of these people could easily get safety-flavored jobs at AI cos, so they could be doing almost the same kind of research except being paid several times more. But they don't because they believe in there being independent orgs like metr as a check against the companies.
Show more

To be clear, METR staff are almost entirely folks giving up a lot of money they could make elsewhere in order to work on rigorous AI safety evals and analysis. The folks criticizing them are largely cynics who can't imagine what civic-mindedness looks like.
Show more

🧵 Excited to share the first batch of 6 misalignment reports from OpenAI's new disclosure process for misalignment incidents. We want to be more transparent about the misalignment we see during training, evals and deployment, this is an important step in that direction.
Show more











