

Jen Zhu
@jenzhuscott
Cofounder/CEO, Power Dynamics ( | Cofounder, Tech Fellowship @AspenInstitute | Senior Consultant @HBO Silicon Valley show
1.5K Following 65.9K Followers
When will people understand that regulatory by default is retrospective? To guardrail agentic AI in finance you need digital infra capable of higher throughput with cryptographically protected sovereignty.
@EmanAbio - you are up! Enlighten us! 🧠
Show more


Average speed 130KMh.
But love the confidence.

DeepSeek is training a 2T model (and planning a 8T) exclusively on Huawei Ascend.
The turning point is here.

The Sui Basecamp stage list keeps stacking.
Google DeepMind's @amoufarek. @EvanWeb3, @RaoulGMI, @kostascrypto, @jenzhuscott, @richardsocher, @BrianQuintenz.
Two weeks out from Singapore 💧
JEV most lasted in total 2 days.

介绍比Jev快50倍,在你设备上跑的laya-mlx!
只在你的设备上占用最高1G内存
Laya是一个开源的类似于Jev的,基于文本输出概率的分类系统
我将其移植到MLX,并且做了一些性能优化!
视频中就是这个模型在我的本地M3Max上玩贪吃蛇
这个模型能够以每秒决策60次的速度玩贪吃蛇!
Show more

France - at least I could name Mistral if you stretched to call it forefront.
What does Canada have? What did I miss?

Canadian PM Mark Carney:
There are only four countries at the forefront of AI: France, Canada, China and the United States.
We must join forces to ensure an appropriate framework so that AI is safe and effective.
Show more

OMG STFU

Professor Jiang Explains Why AI Isn’t Real
“I guarantee you it's being manipulated by humans somewhere in India.”
(Via Jack Neel)

Love how my friend @CodyAFriesen built this ultra analog, nerdy device for complete local AI - with Qwen, Gemma etc local models built-in, analog dials to adjust tones/styles, voice control + output. Personal data doesn’t not leave the device.
Perfect for schools or kids as home/desktop tutor. Love it! 😻
Show more

Announcing the launch of Kalea! Voice first. Local, private intelligence. She is built to be a tutor, elder companion, private intelligence, and to form agentic swarms. Sophisticated, simple to use right out of the box.
Show more

Sounds fantastic. But then he didn’t really say anything.
🚨 OBAMA ON AI: "If we are thinking about AI just in terms of how do we cure cancer or get better energy, you can do that without having agentic AI and having it just roaming free in the internet. The reason you are doing that is because you have to market a product that people will pay money for.
That’s a misalignment between what our society needs and the commercial imperatives that these companies are facing, not because necessarily they’re trying to do bad things, but because they’ve got to justify these valuations.
So, that’s one more reason why it is really important for us to have a competent government and a serious bipartisan conversation around this issue, and we have to do it fast. And I would encourage voters to pay attention to this. If somebody does not have a serious plan for how to deal with this, then they’re not meeting the moment, and you should probably look for somebody else."
Show more

Beautiful picture for social media, but if these are wine fridges w/out modification they'd be ruined soon.
Wine-cellar cooling is sized for bottles, not kilowatts. this is the rack-scale thermal problem in miniature.
Typical residential wine units deliver ~1,500–4,000 BTU/h (0.4–1.2 kW). That holds ~13°C against wall conduction and door openings, not continuous electronics load.
Even a modest homelab rack dumps 1–3 kW at idle and more under compute. The compressor then runs at 100% duty cycle instead of the short, low-load cycles it was designed for.
Result: overheated compressor, rising head pressure on a condenser never meant for that reject load, oil breakdown, and early failure. Humidity control also fights the dry air servers want.
But perhaps modifications here and we are only seeing wine fridges as the shells?
Show more

Our house in Toronto had this fancy glassed wine cellar, but we are not big wine drinkers.
Anyways, it had good climate control so here is my rack cellar.


MiniMax Code CLI is now open sourced 🎉 and SOTA on FrontierHarness Eval
After rapid iterations from day one, we’re thrilled to share this with the developer community. Grateful for every contributor and supporter
Show more

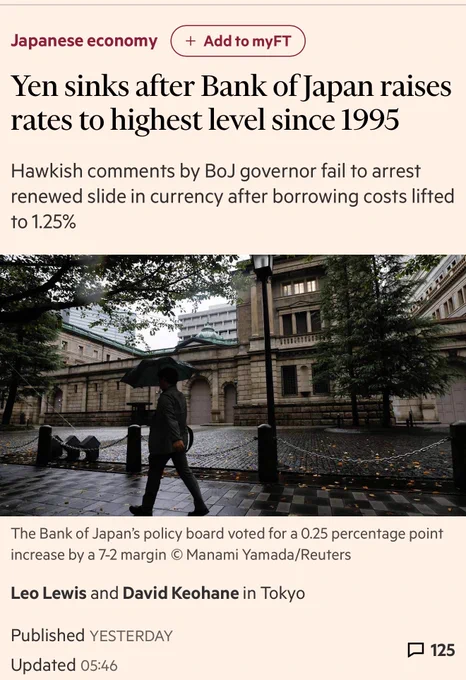
Question to the macro and currency experts out there - how can Japan get out of this spiral?
Thank you 🙏

MiniMax Code is going open source in the next few days.
Built with developers. Now, built in the open.
See you on GitHub.
"AI employees" services are popping up and from launch to $50m annualized revenue in 7 months is very meaningful momentum.
Adopting AI cos it's fashionable is one thing, but there is actually too much pointless, repetitive work that nobody should spend any fraction of our life doing. I'm glad to see applications like this taking off!
Show more

Exciting update!
We've hit $50M in annualized revenue. After just 7 months!
BUT we're not even 0.002% into our mission.
We're just getting started.

Yesterday Xiaomi. Today Zhipu - sharing training process (and potential failure!) - the scarce skill is no longer pretrain. It’s scaling agentic RL + standing up serving on constrained hardware.
Xiaomi is livestreaming MiMo-V2.6 mid-run: ~2B tokens/step, 1568 prompts × 16 rollouts, fully async, mixed harnesses, extra compute on graders/credit assignment. @Zai_org ai used GLM-5.3 as an infra agent to take GLM-5.3-Flash from first successful run to production in <2 weeks and 3× e2e throughput via traces, microbenchmarks, and local correctness tests- including on Chinese chips.
They’re publishing the method because that’s the moat they can prove. Weights and dashboards recruit talent and adoption. Secret pretrain recipes don’t, once everyone is already at the frontier on post-training. So ballsy!!
Show more

We’re sharing how GLM-5.3 helped build and optimize the inference infrastructure serving GLM-5.3-Flash.
The system went from its first successful run to production readiness in less than two weeks, with end-to-end throughput tripling relative to the initial baseline.
The key was dense feedback: local correctness tests, execution traces, microbenchmarks, and end-to-end measurements that enabled targeted hypothesis testing rather than reliance on aggregate performance metrics alone.
Show more


Set this one up for my hair lady. 😅 She sent me this & slightly mad at me for the overwhelming inflow. 😅 I love it when small business owners who use their hands and craft to earn an honest living get a boost from good AI services, especially those who are in my support system to keep my life functional. 💙
Show more


Introducing Reception, an AI receptionist platform for small businesses, built on ElevenAgents.
Every missed call could be a lost customer. Reception answers every call, answers questions, books the job, and texts confirmation.
Set up in minutes just by adding your website.
Show more

For those who want to utilise AI more than chatbot but don't feel comfortable to build agents from scratch, pre-built "AI workers" might be a clever option.
A chatbot answers question, an agent runs a task, an AI worker assumes a role w email/slack/telegram/whatsapp etc. A smart way for small businesses to scale efficiently. Just saw this - pretty smart 👇
Show more

Reflecting on the dramas in the past few days and grateful for what I Ching taught us in the very 1st chapter:
“The dragon flies too high and regrets:
Fullness cannot endure forever.
When all lines are nines,
It reveals the Heaven’s way:
True power does not claim to lead.”
Show more












