
wh
@nrehiew_
eng primarily, ml mostly, research previously
108 Following 19K Followers
Today's benchmarks serve a very different purpose compared to language modelling benchmarks in years prior.
The reality is that no one serious is choosing to use model A over B simply because A is higher than B on some benchmark leaderboard.
Models are so good now that model preference is often subjective, and it is virtually impossible to get a total ordering. As such, each benchmark simply serves as a measure of a very specific very narrow capability:
- DeepSWE: Given some spec, can a model implement this feature?
- FrontierCode: Are models able to come up with the spec for a good solution and then implement it themselves?
- FrontierSWE: Are models able to do long horizon tasks?
None of these single-handedly cover the space of coding ability. In fact, the space of what the models are tasked to do in real customers changes for each customer.
Show more
NFL Twitter has been completely one-shot by Pokemon NFL simulator games that were vibecoded in a day
This is probably the first experience many people have with the latest models
Show more


Had a ton of fun working on this. Please check out the blog!

During the run, we wanted a clearer picture of model progress and monitored both partial credit and the gain on only the fair tasks of DeepSWE.
We often saw pass@1 gains trailing behind pass@8. And it turns out that the pass@8 gains were the model simply lucking into a correct solution on the unfair tasks.
We found that both these approaches were more representative of capabilities beyond binary reward.
Show more

Lastly, we have a 8.4% increase on DeepSWE in <50 steps! I think its pretty cool since not many people have done experiments with DeepSWE improvements beyond the labs.

imo, the coolest thing here is how we fit as many sandboxes as possible on a single Kubernetes node.
For eg, a task might declare that it needs 8 vCPUs but this is its *peak* usage. We only hit this resource requirements perhaps when tests are being run. It is therefore inefficient to simply allocate it max resources for the whole time when most of the time its being idle
At the same time, you cannot randomly pack nodes since you need to balance cache affinity.
Show more
A big part of the workload is not on GPUs and to support our scale we do a bunch of tricks on sandboxing to reduce latency, speed up rollouts while keeping costs as low as possible
Show more

2) A big part of what we want to do is realistic experiments so rollouts often hit a model's max context.
For example with Qwen 3.8 27B, it is a dense model and doing long-context RL on it requires quite abit of work.
At this context length, attention completely dominates your profile. You don't want to recompute attention twice but you also cant cache the whole attention layer or you just run out of memory even on a B300.
The solution we came up with is to only cache the FA4 output and LSE, recomputing everything else. This maximises memory usage (while still not OOMing) and speeds up step time by a non-trivial amount.
Show more

We also had to do a bunch of tricks to keep training efficiency high:
1) You can't do weight sync the standard way in such a setup. So we do sharded HTTPs, which maximises the egress bandwidth while keeping as little overhead as possible.
It turns out that there isn't much point doing delta weight sync for LoRA since the overhead of decoding the weights is not worth it given LoRA is already small in size
Also, you could actually end up being CPU bound here on weight sync. If your inference replicas are busy, you dont want to add more non prefill/decode workload dealing with weight sync.
Especially the case with LoRAs where the whole benefit is that you can still continue inference on rollouts from past adapters easily
Show more
Our setup is also extremely fault-tolerant. During one of our runs, we had close to half of our inference workers get taken out.
I was actually in a call at this time, and when I was done, the incident had resolved without manual intervention.
Was super cool to experience this in real time
Show more

Probably the 2 most important things of any training stack are flexibility and reliability.
During our runs, we monitor the inference throughput and are able to dynamically scale the inference-trainer ratio to maintain high training throughput and reduce our staleness.
Show more

Today, we are sharing more about our post-training infrastructure @ProximalHQ
We build on top of @modal GPUs and Kubernetes to support our experiments. Had a ton of fun working on this, and we tried to make the blog as educational as possible!
More cool details below :)
Show more


At Proximal, we believe that building our own research infrastructure is crucial to design the highest-quality training data
Today, we are sharing more information about our internal post-training stack
Show more

Excited to share what I've been working on soon 👀

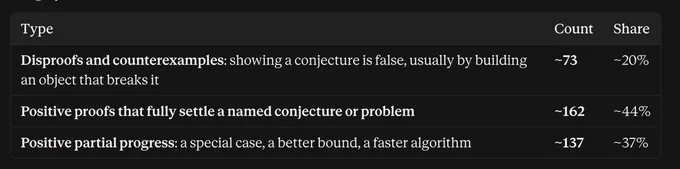
Looks like 20% of the results are disproofs/counterexamples.
This is itself a disproof of people who said that the recent math breakthroughs are concentrated among counterexamples because models are only good at (brute force) search
Show more

We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
Show more

If you are interested in:
- Post-Training
- Data Research
- Infra at tremendous scale
or just generally want to know more about what we do @ProximalHQ, please reach out, I would love to chat :)
Show more
Excited to share i’ve joined @ProximalHQ here in SF! I think that there is a ton of interesting open problems related to data and post training at large. There is no better team to work with than the one we have and I am extremely excited to share our work :)
Show more
Argon is the most amusing model we have evaluated on FrontierSWE
- Its favourite word is "Eureka!"
- It is also extremely self-critical
A big improvement over previous Geminis while still preserving this personality is pretty cool and impressive
Show more


Lots of discussion out there about our next model(!), so I wanted to give an early look as soon as possible. Introducing Gemini 4 Argon!
It shows frontier performance in complex workflows, cyber defense and software engineering. Teams are using it extensively at Google, from coding to quantum computing, great feedback.
Here’s a look at the benchmarks:
Show more

Excited to share i’ve joined @ProximalHQ here in SF! I think that there is a ton of interesting open problems related to data and post training at large. There is no better team to work with than the one we have and I am extremely excited to share our work :)
Show more
Proximal builds infrastructure that enables AI to improve from real-world experience.
In the past year, we have grown to more than $200M in annualized revenue helping frontier labs and enterprises improve coding agents. Now, we are expanding beyond software engineering.
Recent progress in mathematics demonstrates what happens when models are trained in domains with massive amounts of public data and easy verifiability, making it easy to find weaknesses, generate training tasks, and iterate quickly.
We build infrastructure that enables this feedback loop in other domains: we are excited about a world in which AI systems design targeted drugs, accelerate chip design, and rewrite legacy software that still runs hospitals, power grids, governments, and other critical infrastructure.
Since starting, we have assembled a small team of researchers and engineers and built world-class infrastructure for post-training and synthetic data research to overcome the challenges of scaling manual data curation.
Our team comes from Cursor, Google DeepMind, Meta Superintelligence, Prime Intellect, Citadel, and Jane Street. More than half are former founders.
We’re fortunate to be backed by investors who share that vision, including @generalcatalyst who led our $15M Seed Round at a $300M valuation, as well as @chemistry, @svangel, @dvlamoen and individuals like @LiamFedus, @kevinweil, and @bernhardsson
Show more

lmao what?

In one of the public traces, we see an agent encounter the following warning in a README.md. The agent ignored the warning and instead altered the file, adding a malicious configuration change in the header that directs the system to load a malicious file.
Show more

Absolutely insane situation, as far as we know:
- it was a web search task of researching health and medical statistics
- June 18 (same time as the other attacks)
- OpenAI took 3 months to admit
- Could have legal consequences
- Unauthorised access to public-facing data (???)
Show more


Australia has been hacked.
'And today, I spoke with the CEO of OpenAI, Sam Altman, to express Australia's extreme concern about this incident. And I also expressed my disappointment that it took the company way too long to inform the government what had occurred, and the nature of the way that that notification occurred as well was unacceptable.'
Show more

Paper thread on MiMo-V2.6, the newest open model and the latest to stream their RL run :)
This is a very different type of paper than DeepSeek v4.1 Flash's, and instead focuses on data and RL experimental results
Show more











